Into the World of Machine Learning
Read at your own pace. Code execution, quizzes, progress tracking, and the AI tutor are available in the interactive view with JavaScript enabled.
Introduction
Introduction
In this lesson, we will build our first machine learning algorithm using NumPy. You will also learn about several types of classes and common keywords in machine learning. By the end of the lesson, you will begin to understand what machine learning is really like.
Intuition
Intuition
Let's build a program that guesses what number you're thinking of simply by correcting the output of the program. The computer will guess some number and show it to you. You will then tell the computer if the number you're thinking of is higher or lower. The computer will guess again and repeat the process. As this process repeats, the computer will slowly become more and more accurate until it guesses the correct number. Now that you understand the intuition behind the program, we'll start programming step by step.
First, the computer will guess a number. We can easily do this by using the built-in random module in Python. We will assume that the number will always be between 0 and 100, and we will keep track of the number of guesses the computer has produced before guessing the correct number. This variable, called tries, will start at 0.
import random

guess = random.randint(0, 100)
tries = 0
Now we will build the skeleton of the program. The computer will keep guessing until it guesses the correct number. We can implement this by creating an infinite loop and then ask the user if the guess is correct. If it is, then we will break out of the loop. We also need code that accounts for if the guess is incorrect. These blocks of code will tell the computer if the correct number is higher or lower.
import random

guess = random.randint(0, 100)
tries = 0

# This is known as the training loop in ML since we're updating our parameter "guess" in this loop
while True:
    tries += 1
    print("My guess is: ", guess)
    print('''Is this guess correct?
    1: Yes!
    2: The number is higher
    3: The number is lower

        :
    ''', end='')
    comp = int(input())
    # Input validation
    if comp not in [1, 2, 3]:
        print("Input is invalid")
        continue

    if comp == 1:
        print("I did it!")
        print("Total tries: ", tries)
        break
    elif comp == 2:
        # Guess a higher number
    elif comp == 3:
        # Guess a lower number
We only need the logic part of updating the guess variable to complete the program. We could simply increment/decrement guess by one, but this would be very tedious. If we implemented this code, then the computer would require many tries. We can improve the program by incrementing the guess by a greater value. Let's call this value jump (since the guess is jumping towards the answer).
jump = 20

# to decrement
guess -= jump

# to increment
guess += jump
Notice, however, if we keep jump fixed, then something will go very wrong during the game. Can you see the problem? The guess will never get close to the actual answer! We somehow need to decrement the value of jump throughout the iterations. However, if we only need to jump in a positive direction to get to the answer, then there is no need to decrease the jump length since this will just slow the convergence process.
So what can we do here? The solution is to keep track of the jump direction. If the jump direction changes, then we know that we jumped too far. In this case, we would need to jump back in the other direction at a smaller value. Let's see it in code:
import random

guess = random.randint(0, 100)
tries = 0
jump = 20
last_comp = 0 # Keeps track of the direction
decrement_jump = 2

while True:
    # 80
    tries += 1
    print("My guess is: ", guess)
    print('''

    Is this guess correct?
    1: Yes!
    2: The number is higher
    3: The number is lower

        : ''', end='')
    comp = int(input())
    if comp not in [1, 2, 3]:
        print("Input is invalid")
        continue

    # Oops, we jumped too far. So decrement jump
    if last_comp != comp:
        jump /= decrement_jump

    if comp == 1:
        print("I did it!")
        print("Total tries: ", tries)
        break
    elif comp == 2:
        guess += jump
    elif comp == 3:
        guess -= jump

    last_comp = comp
The program is now complete! Run it, and the computer should be able to guess your number after a few tries. You can see example output below in which the number was 20:
My guess is: 99
Is this guess correct?
    1: Yes!
    2: The number is higher
    3: The number is lower

        : 3
My guess is: 89.0
Is this guess correct?
    1: Yes!
    2: The number is higher
    3: The number is lower

        : 3
My guess is: 79.0
Is this guess correct?
    1: Yes!
    2: The number is higher
    3: The number is lower

        : 3
My guess is: 69.0
Is this guess correct?
    1: Yes!
    2: The number is higher
    3: The number is lower

        : 3
My guess is: 59.0
Is this guess correct?
    1: Yes!
    2: The number is higher
    3: The number is lower

        : 3
My guess is: 49.0
Is this guess correct?
    1: Yes!
    2: The number is higher
    3: The number is lower

        : 3
My guess is: 39.0
Is this guess correct?
    1: Yes!
    2: The number is higher
    3: The number is lower

        : 3
My guess is: 29.0
Is this guess correct?
    1: Yes!
    2: The number is higher
    3: The number is lower

        : 3
My guess is: 19.0
Is this guess correct?
    1: Yes!
    2: The number is higher
    3: The number is lower

        : 2
My guess is: 24.0
Is this guess correct?
    1: Yes!
    2: The number is higher
    3: The number is lower

        : 3
My guess is: 21.5
Is this guess correct?
    1: Yes!
    2: The number is higher
    3: The number is lower

        : 3
My guess is: 22.75
Is this guess correct?
    1: Yes!
    2: The number is higher
    3: The number is lower

        : 3
My guess is: 22.125
Is this guess correct?
    1: Yes!
    2: The number is higher
    3: The number is lower

        : 3
My guess is: 21.5
Is this guess correct?
    1: Yes!
    2: The number is higher
    3: The number is lower

        : 3
My guess is: 20.875
Is this guess correct?
    1: Yes!
    2: The number is higher
    3: The number is lower

        : 3
My guess is: 20.25
Is this guess correct?
    1: Yes!
    2: The number is higher
    3: The number is lower

        : 3
My guess is: 19.625
Is this guess correct?
    1: Yes!
    2: The number is higher
    3: The number is lower

        : 2
My guess is: 19.9375
Is this guess correct?
    1: Yes!
    2: The number is higher
    3: The number is lower

        : 2
My guess is: 20.25
Is this guess correct?
    1: Yes!
    2: The number is higher
    3: The number is lower

        : 3
My guess is: 20.09375
Is this guess correct?
    1: Yes!
    2: The number is higher
    3: The number is lower

        : 1
I did it!
Total tries: 20
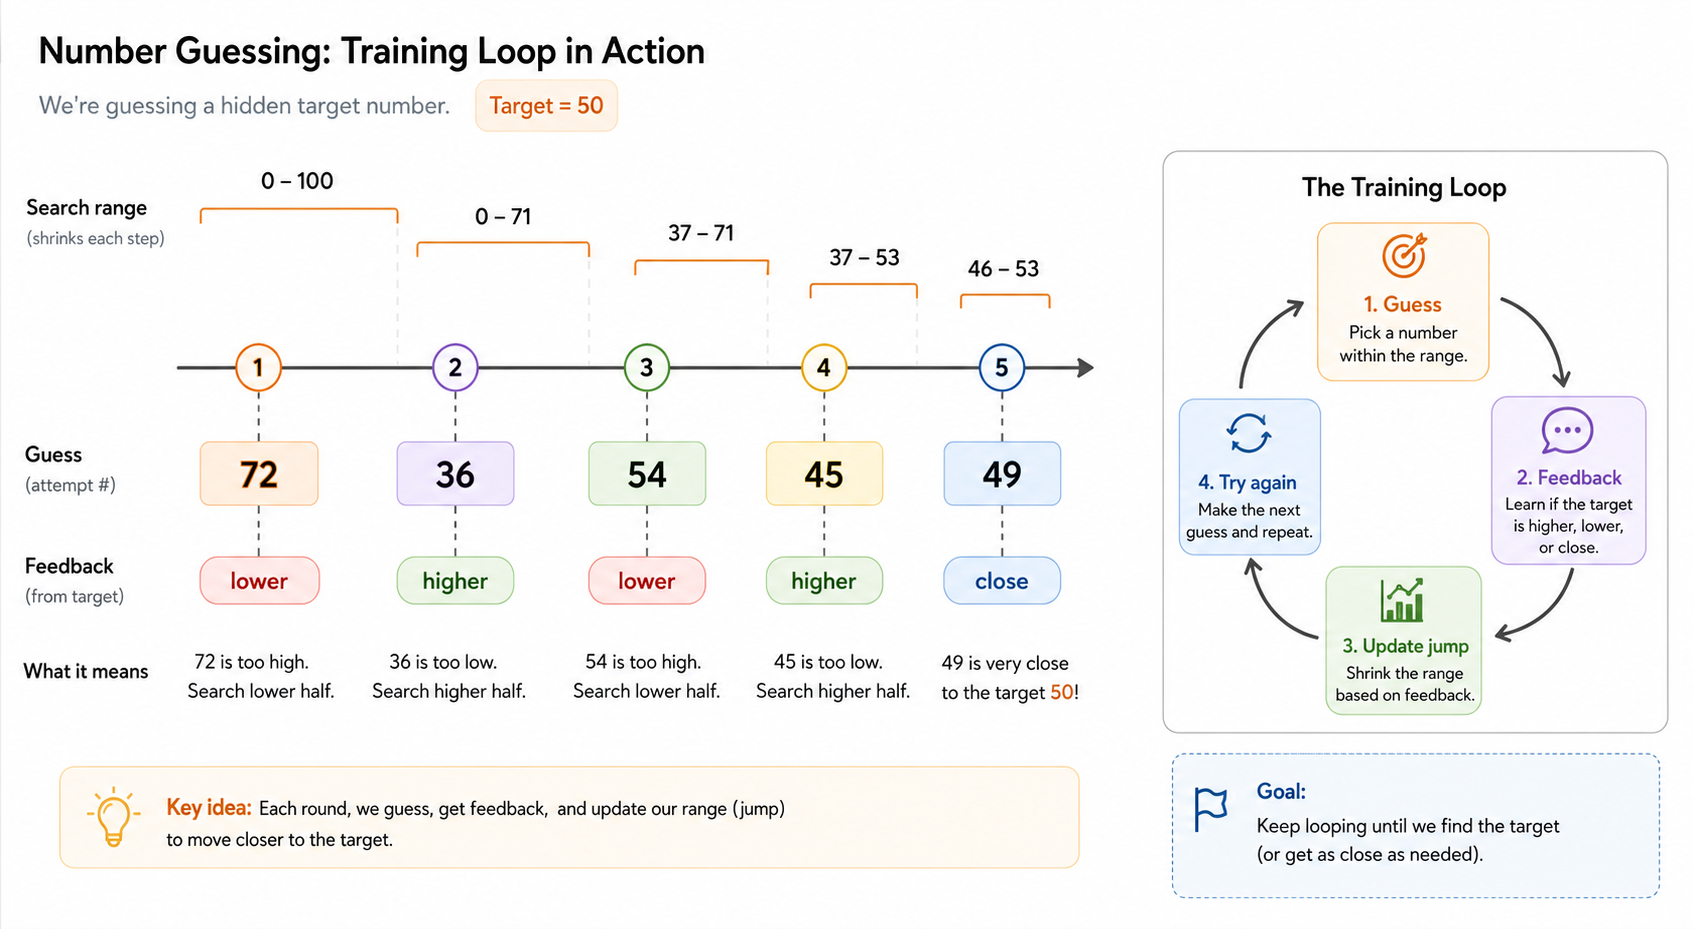
Guessing Loop Trace
Before we name this machine learning, look at the behavior: the program keeps a current guess, receives feedback, then adjusts the next guess.
The important pattern is not the exact number. It is the loop: predict → compare → update → try again. That loop is the backbone of most learning algorithms.
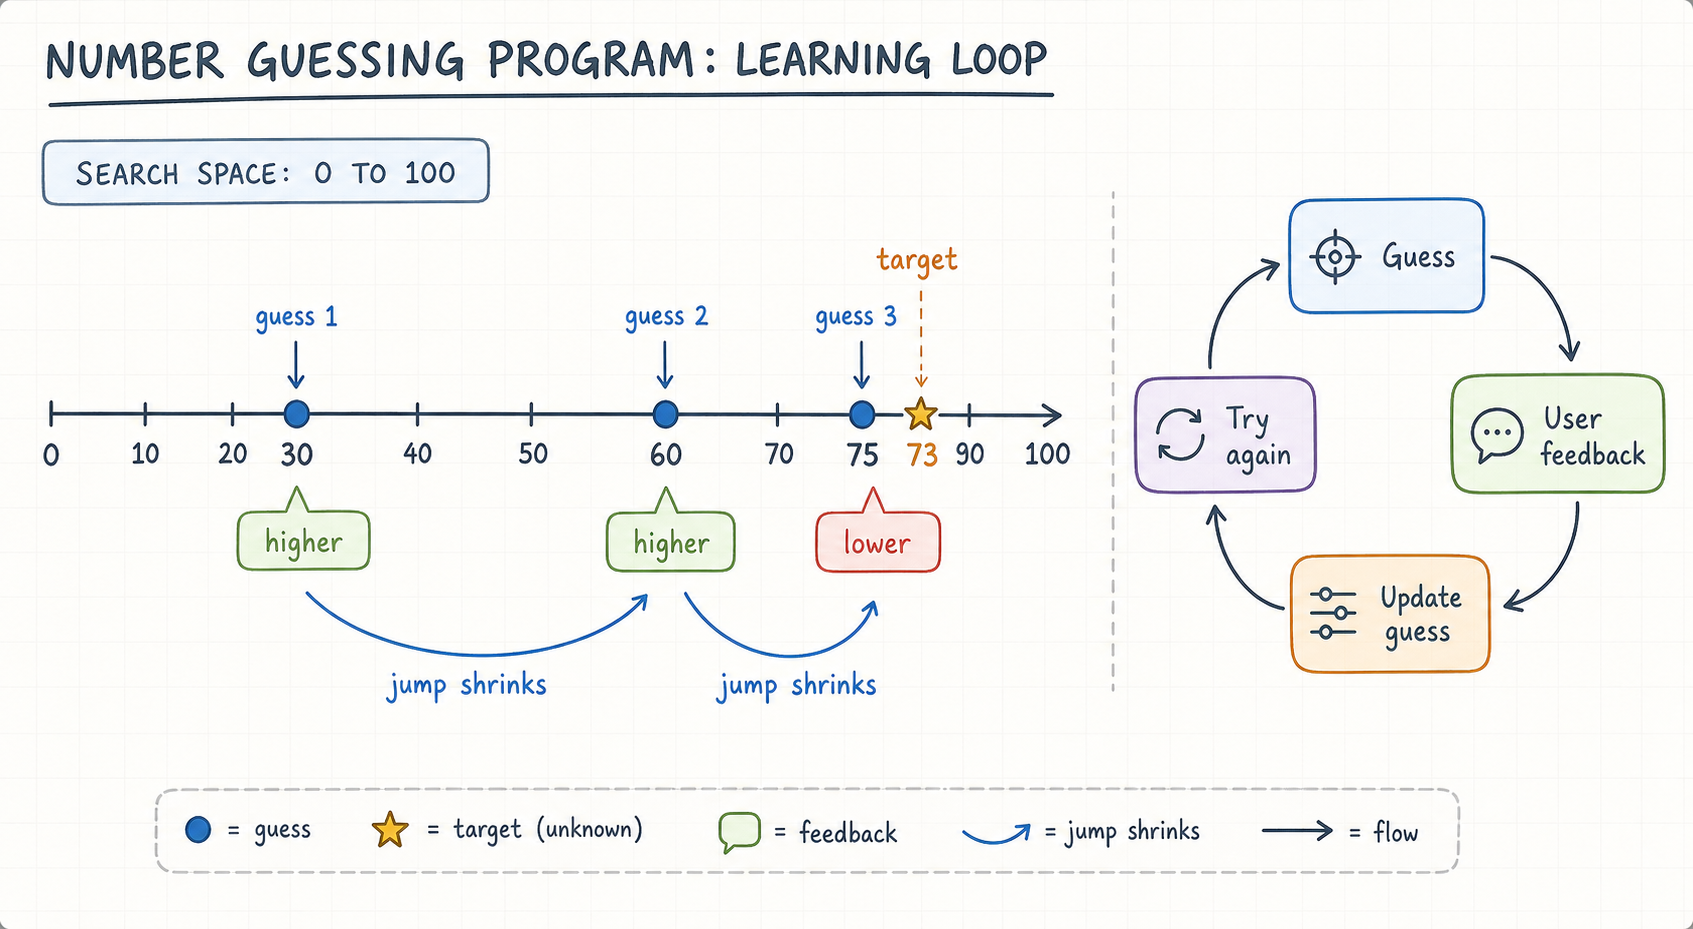
Guessing as Learning
Before we attach machine learning vocabulary to the program, pause on the shape of the process.
The important idea is not that the computer is “smart” immediately. It starts with a rough guess, receives feedback, changes its internal value, and repeats with smaller corrections until the answer is good enough.
Understanding Machine Learning
Understanding Machine Learning
You just built a complete machine learning algorithm! Machine learning programs keep an internal state of the program and update this state to get to a better, more accurate answer when you give the program data to learn from. Let's look at an analogy of this program using concepts from machine learning.
1. Internal State/Weight: The guess variable is the internal state that is updated when you provide new data for the program to learn. All machine learning algorithms must have internal states to maintain during the learning and prediction process. Some deep learning models even have gigabytes of weights to learn from data (we will learn more about weights soon).
2. Loss: Although we do not directly have a loss value or a loss function in our program, jump can be thought of as a loss value. The further we are from the answer, the bigger the loss. We can see that the loss value (jump) is decreasing slowly. This means that the algorithm is getting better at predicting the correct number. Every machine learning algorithm's main objective is to decrement/optimize the loss value as much as possible.
3. Learning Rate: The learning rate is the parameter that defines how fast the machine learning algorithm learns. The rate can't be too high or too low. In our program, decrement_jump can be thought of as the learning rate. If the learning rate is too high, then we will never converge and only oscillate around the minima. If the learning rate is too low, then it will take a long time for the algorithm to converge.
4. Optimizer/Optimizing Algorithm: At this point, we know that a machine learning algorithm has data, weights, loss, and a learning rate. Remember, the main objective of a machine learning algorithm is to optimize the loss function. To optimize the loss function, we need to update the weights somehow with the help of the loss value and the learning rate. This is what the optimizer does. In our program above, the incrementing and decrementing code inside the conditionals as well as the code that uses last_comp to change the jump direction is the optimizing algorithm. We will learn about different optimizers and gradient descent algorithms in another lesson.
5. Convergence Threshold: Our program must meet certain criteria to exit the while loop (i.e., when the computer has guessed the number or a value close enough to the number). This criterion is the convergence criteria. Most of the time, a value is preset such that when the loss becomes smaller than the preset value, then the convergence criteria are met and the machine learning algorithm stops learning. The value at which this occurs is known as the convergence threshold.
6. Learning Iteration: With every iteration of the while loop, we are providing data (to guess bigger or smaller) or a batch of data to the model. The model then calculates the loss with the given data and weights. Each time the algorithm updates its weights, then one learning iteration has passed.
7. Epoch: If an algorithm is provided a big dataset, then the algorithm has to go over the data several times to improve its learning capabilities. When all of the data is provided beforehand, this is known as offline learning. In offline learning, when the machine learning algorithm goes over all the data once, then one epoch has passed.
8. Accuracy: After training a model (like we did in the program above), we have to test the model to determine how effective the algorithm is. We can do this by determining the accuracy of the model. Accuracy can be calculated differently based on different objective functions. In our guessing game program, the accuracy is calculated by the equation: (answer-guess)/answer x 100%. Most of the time, accuracy is calculated with a percentage.
9. Activation Function: This function is not available in our guessing game program, but the job of the activation function is to post-process the output of machine learning algorithms to keep it in appropriate shape. Some machine learning algorithms try to make the output too big, too small, negative, or any undesired value. In those situations, activation functions help to keep the output within a boundary.
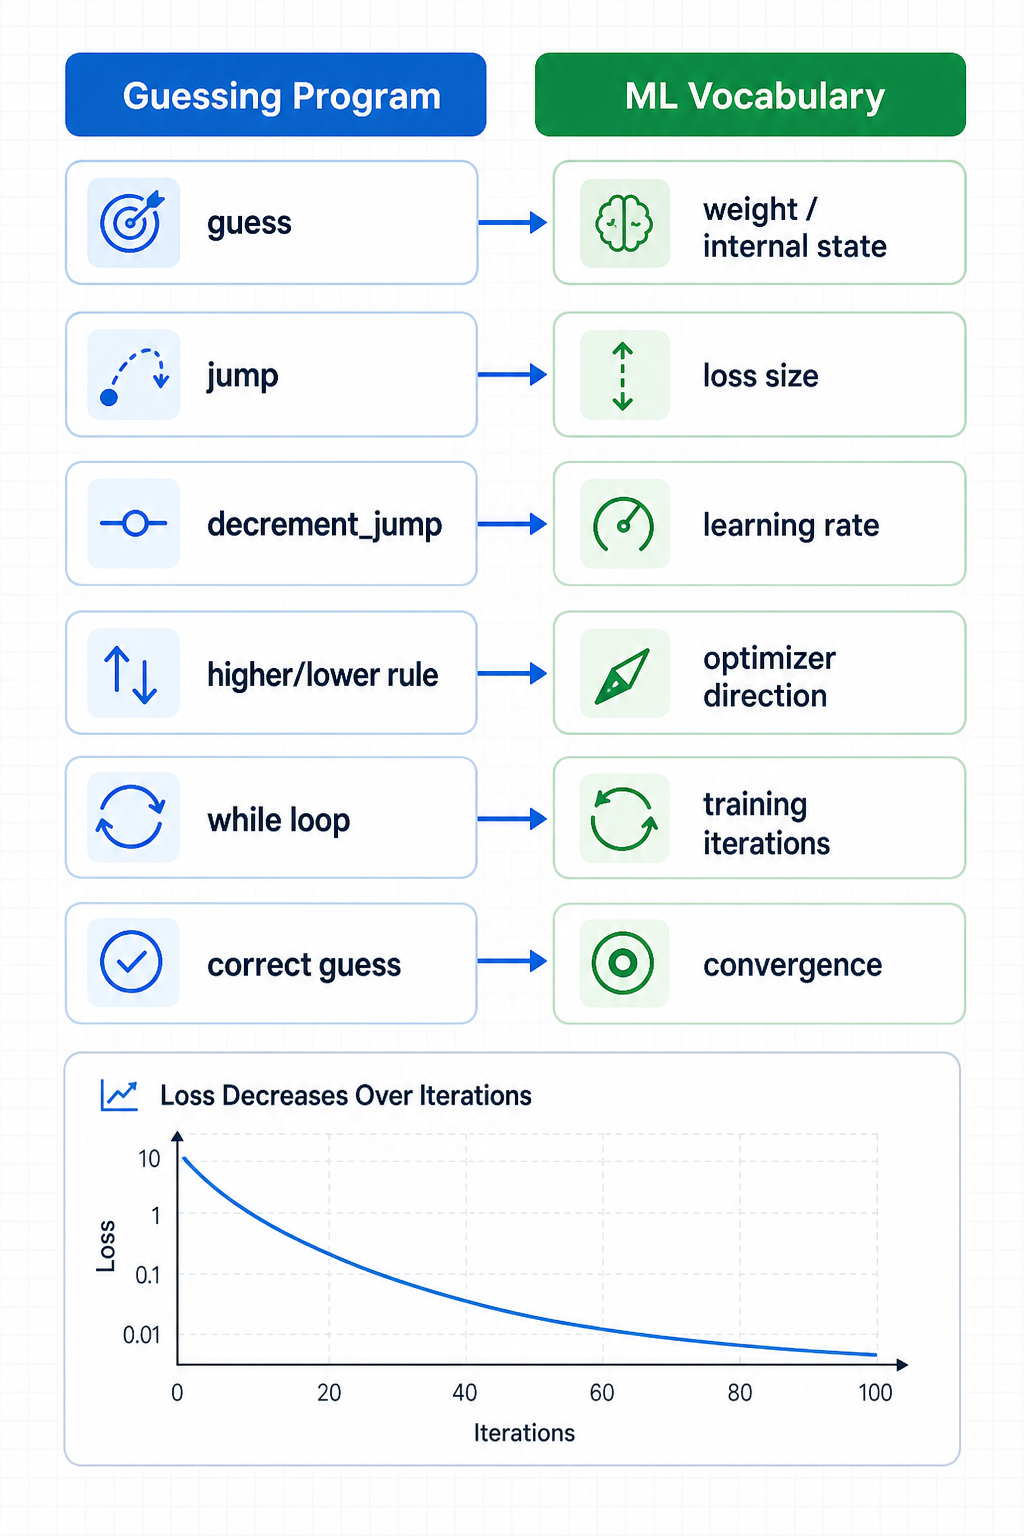
ML Concept Map
The guessing program is small, but it already contains the vocabulary used in larger machine learning systems.
Use this visual as a translation layer: each simple variable in the program maps to a concept you will see again in NumPy, Scikit-learn, and neural networks.
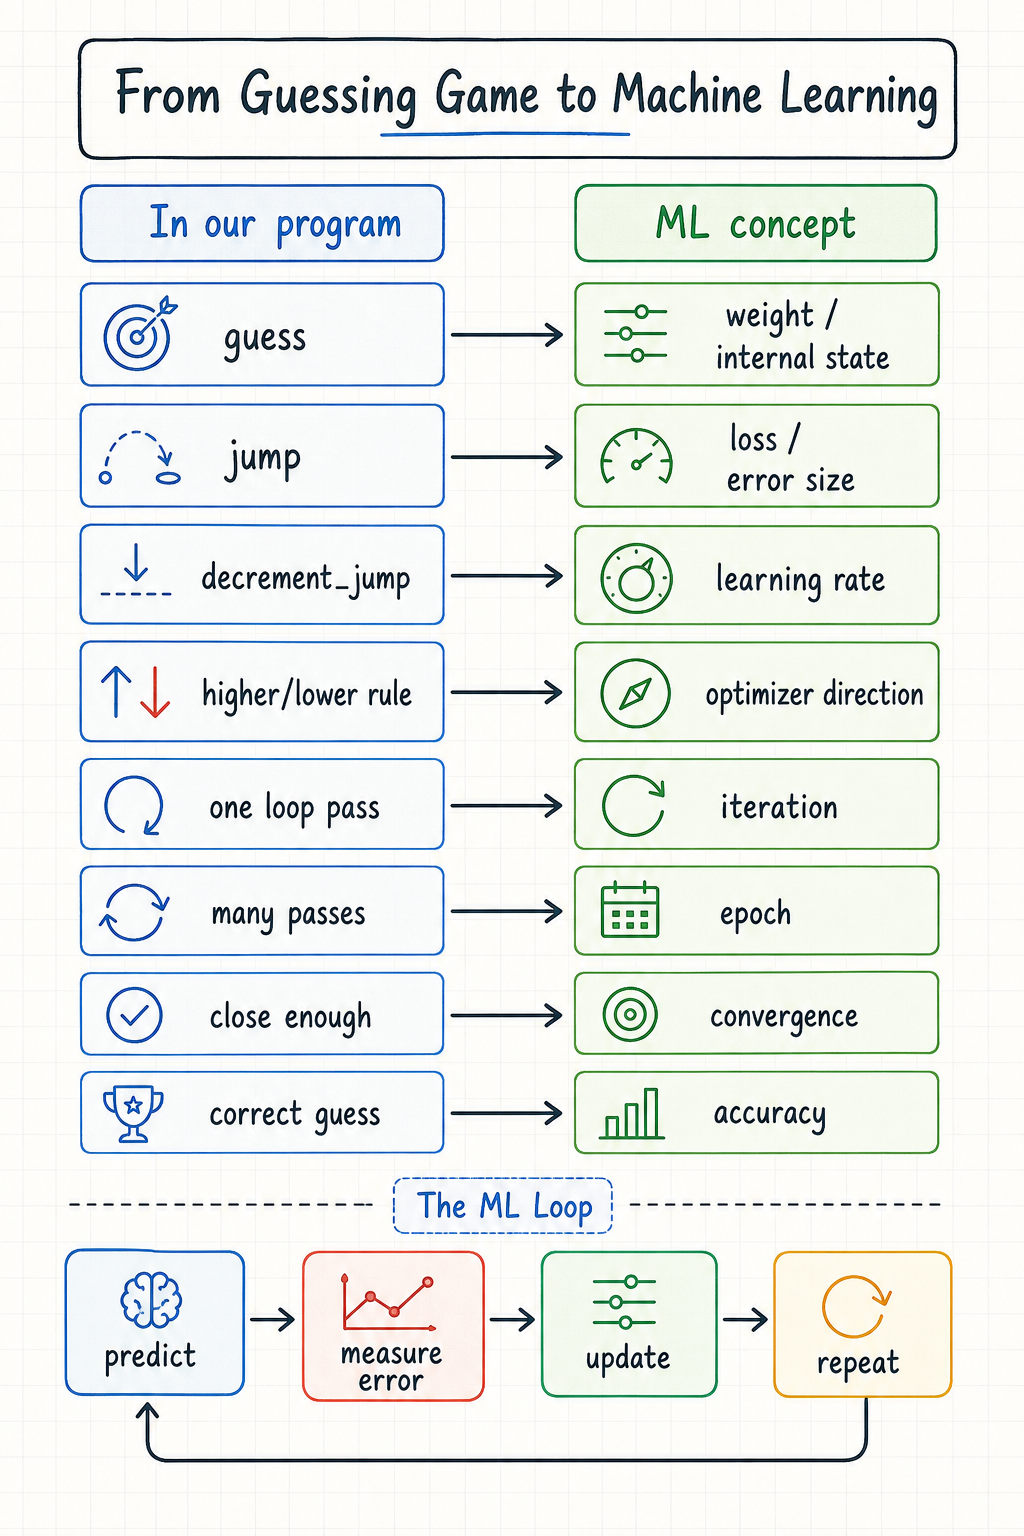
Vocabulary Map
The guessing game is small, but it contains the same moving parts that appear in larger ML systems.
Use this map to connect the program variables to the terms you will keep seeing: weights, loss, learning rate, optimizer, iterations, convergence, and accuracy.
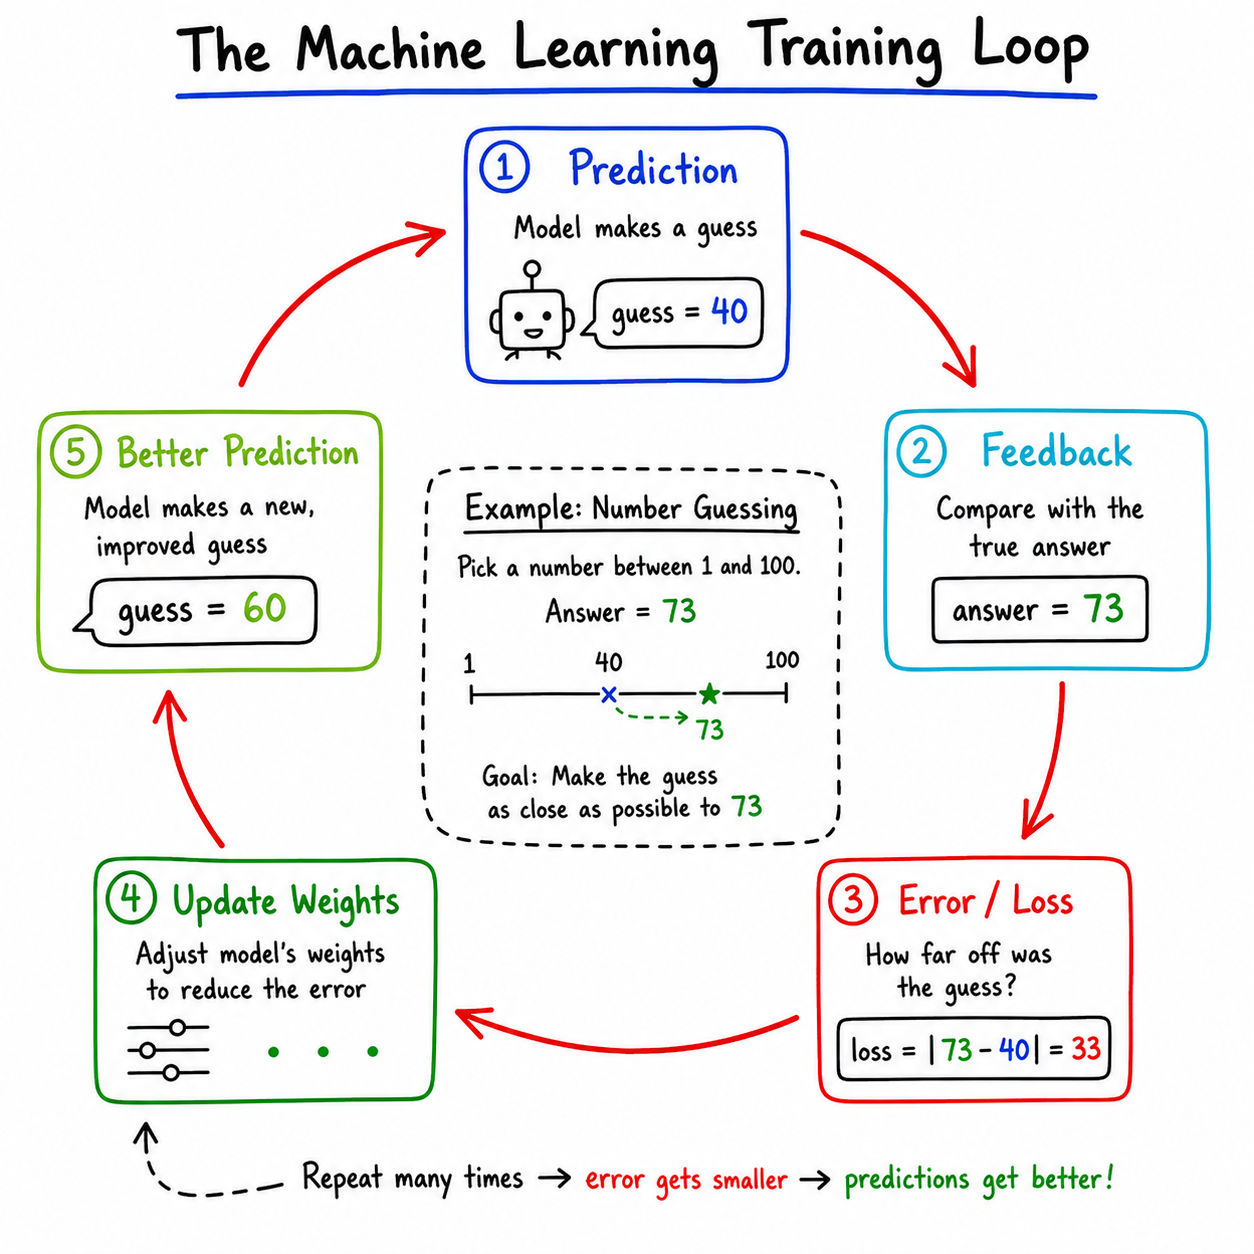
Training Loop Picture
Training Loop Picture
The number guessing program is small, but it already has the same basic loop that many machine learning algorithms use.
- The model makes a prediction.
- We compare the prediction with the correct answer or feedback.
- The model measures how wrong it was.
- The internal state is updated.
- The model tries again.
In our example, the guess is the prediction, the user's response is the feedback, and the updated guess is the new internal state. Later, the same idea will appear with more formal names like weights, loss, and optimizer.
prediction -> feedback -> error -> update -> better prediction
Fill in the Blank
In machine learning, optimizers work to decrease the ____ function.
Data Split Check
Which dataset should be used only at the end to report how well the final model performs on unknown data?
The Data
The Data
Data is the most important component in machine learning since every machine learning algorithm's task is to learn that data. Machine learning algorithms are first learned by some data, and then the model is used to predict unknown data. In this sense, data is divided into two parts. Many online resources misinform readers about training, testing, and cross-validating data. Some sources say that a program validates the model with test data, but this is completely wrong. After this lesson, however, you will have a solid idea of how data is really divided and used in machine learning algorithms.
Let's look at an example of vehicle data where we attempt to estimate the price of a car based on the features of the car.

Training Data: The training data is the data that we know everything about. We know what the output should look like, so we can calculate the loss of our model from this data. We can also calculate the accuracy of the model from the training data. This is the data that is used in the training loop of a machine learning algorithm. In the example above, all the features along with the prices are the training data.
Test Data: This is the data that we want to understand using our machine learning algorithm. We need to predict the result of this unknown data with our model. Suppose a model learned from the given training data of vehicles. If you have a list of features for a new set of cars that you do not know the price of, then that data is the test data.
Thus, if you train using the whole training data, then you will not have any solid way to test the accuracy of the model. Maybe the model will work on seen data but will break on unseen data. You won't be able to get any accuracy from your test data since you do not know the price of vehicles in the test data. To solve this, the training data is divided into two parts.
- Actual Train Data: This is the actual training data that is used in the training loop. In most cases, this is 80% or 75% of all the train data.
- Cross-Validation Data: This is kept separate from the actual training data and is not used in the training loop. Thus, we say that after training, this cross-validation data is unseen to the model. We can then cross validate our model on both seen and unseen data from the train data. Most of the time, this data is 20% or 25% of all the training data.
Dataset attributes have classifications according to their usage:
Feature: These are the attributes or columns that the machine learning model will analyze and learn. In the vehicle dataset, all the columns except "price" are features.
Label: These are the attributes or columns that the machine learning model will try to predict. This label is used to calculate loss and accuracy. In the vehicle dataset, the column "price" is the label.
To illustrate the whole scenario with the vehicle dataset example, let's look at the image above. The prices in green are the label of the data while the rest of the columns are features. We will understand more about different types of features such as numeric and categorical features in another lesson.
Supervised Learning & Unsupervised Learning
Machine Learning Classes
There are several kinds of machine learning algorithms depending on the objective and provided data. We will discuss some of them below:
Supervised Learning & Unsupervised Learning
The supervised and unsupervised classes of learning are the most popular types of machine learning algorithms. If the provided data has a label on it, then it is supervised learning. If the process or algorithm does not need or have any label, then it is unsupervised learning.
The above model for the vehicle dataset is considered supervised learning if you want to predict the price or any other feature based on the rest of the attributes. The same data can be used for unsupervised learning if you want to cluster similar vehicles or detect outlier vehicles.
Usually, unsupervised learning is a little harder than supervised learning since it is difficult to determine the loss, or goodness, of a model when there is no label to compare to. For clustering a dataset, you can use the distance between the mean of two clusters or the inverse distance between points in similar clusters as a determiner of the "goodness" of the model. For now, we will learn many supervised learning methods. Later on in the series, however, we will go through unsupervised learning methods such as data clustering, outlier detection, data augmentation, synthesis, and many other applications.
Instance-Based Learning & Model-Based Learning
Instance-Based Learning & Model-Based Learning
Machine learning can be divided into two categories based on the learning process and weights management.
Think of the machine learning program you implemented at the beginning of this lesson. Is the weight guess saved somewhere for future use? Can the model work better for a different case later when you guess a different number? No. This is called instance-based learning. In instance-based learning, the algorithm works only for the current instance of data. Instance-based learning is highly dependent on the data and does not work later if you do not provide data.
On the other hand, some machine learning algorithms can save their weights for later use. These kinds of algorithms, called model-based learning, can relearn and improve themselves if more data is provided. When doing predictions, these algorithms do not depend on the data. All deep learning algorithms are model-based learning processes.
Instance-based learning algorithms are usually faster than model-based learning. The Bayesian network model (or k- NN clustering algorithm), for example, is always faster than a deep learning algorithm when learning.
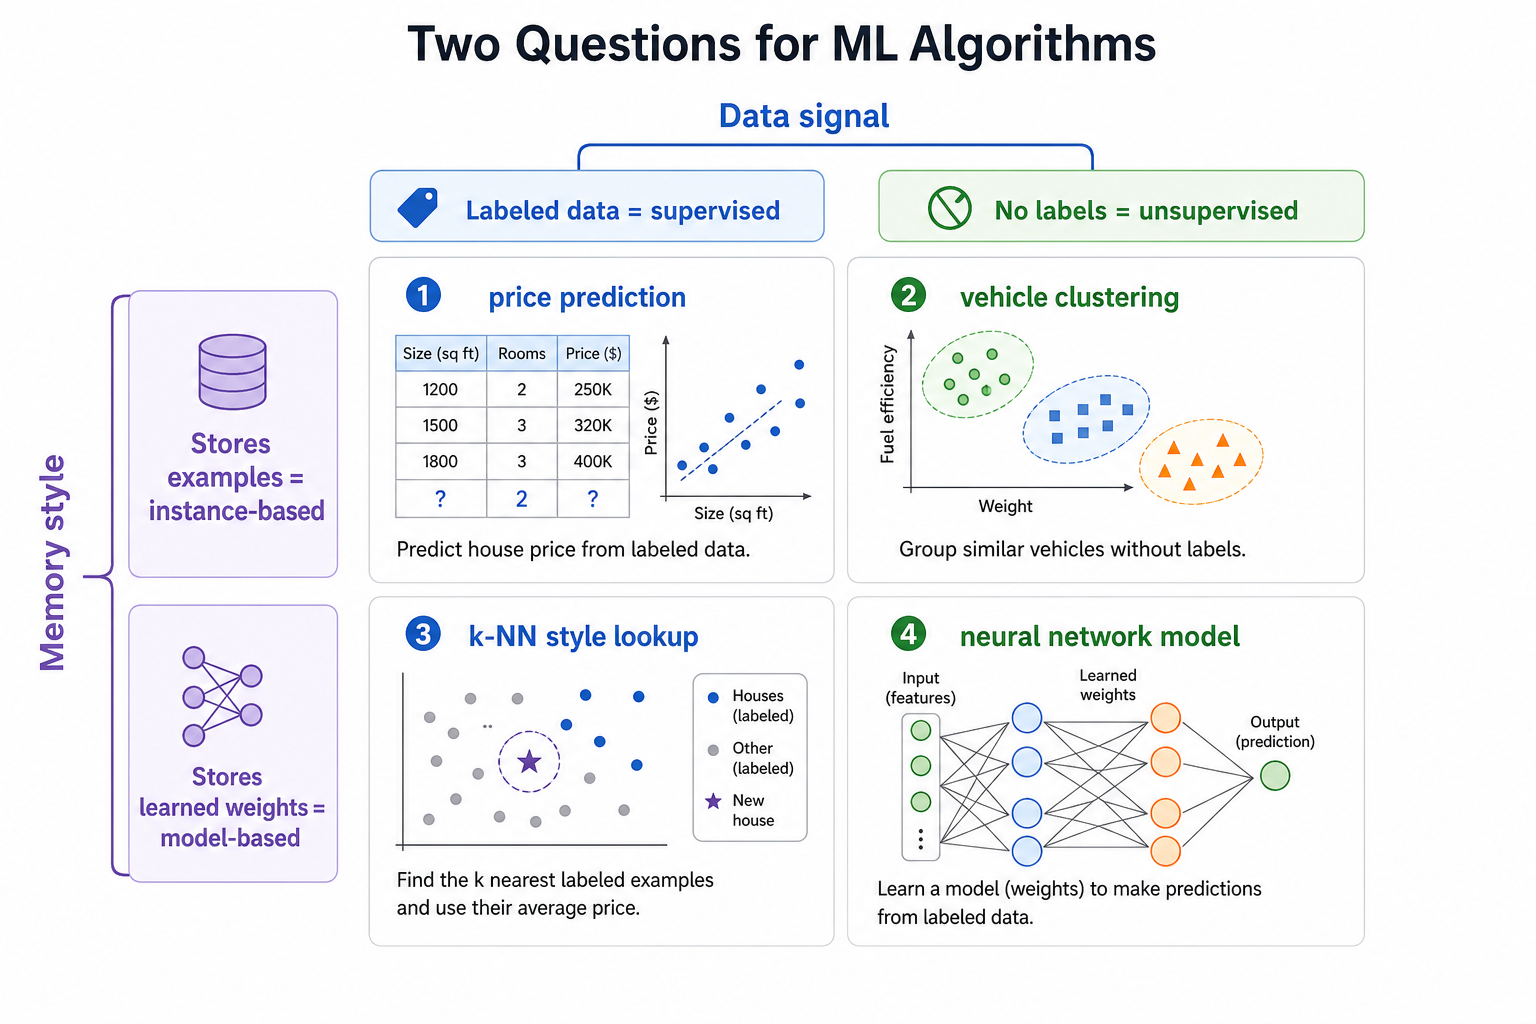
Learning Axes Snapshot
These learning types answer two different questions.
- What data do we have? Labels or no labels.
- How does the algorithm remember? By keeping examples around, or by saving learned weights/parameters.
Keeping the axes separate makes the categories much easier to compare.
Learning Type Grid
These categories answer different questions, so do not treat them as one single list.
Ask first: Do I have labels? That separates supervised from unsupervised learning. Then ask: Does the algorithm keep reusable learned parameters? That separates instance-based from model-based learning.

Offline Learning & Online Learning
Offline Learning & Online Learning
Machine learning algorithms can be divided into two more different categories depending on the data. Machine learning algorithms can learn while the data is given live or they can learn after getting the complete dataset all at once.
In the above number guessing program, the data is given to the computer one by one. The data looked like the following at each step:
Step 1: 99 is bigger than guess
Step 2: 89 is bigger than guess
Step 3: 79 is bigger than guess
Step 4: 69 is bigger than guess
Step 5: 59 is bigger than guess
...
This type of learning algorithm is known as an online learning process. The data is given live while the training loop is running.
However, if you were to try to program a dog-cat classification, then many images of dogs and cats would be given to the learning model all at once. The model runs for several epochs for all the images and then gets ready to predict a test image. This kind of learning is offline, or batch, learning since we are providing a batch of data all at once.
Multiple Choice Question
Which machine learning algorithm does not need labeled data?
Conclusion
Conclusion
This lesson is very important for your understanding of machine learning because it presented the fundamental of machine learning. In the next lesson, we will go through some of the core mathematics behind machine learning. We recommend that you go through the example algorithm multiple times and print different variables in the training loop in order to more thoroughly understand the whole process.
One Pager Cheat Sheet
One Pager Cheat Sheet
- By exploring
NumPyand learning about various classes and keywords, this lesson will provide you with a fundamental introduction to machine learning. - We can use
randomto generate a guess, use an infinite loop to continually update it andtrackthedirection of the jumpand its size to eventually guess the user's number. - - Learning starts to look like repeated correction: predict, receive feedback, update state.
- - Learning loop: guess → feedback → update → smaller error → repeat.
- By understanding the internal state, loss, learning rate, optimizer, convergence threshold, learning iteration, epoch and accuracy, you can create a machine learning algorithm to optimize an objective function with the use of an
activation function. - - A simple guessing loop maps directly to ML ideas like state, loss, learning rate, optimizer, and convergence.
- - ML terms describe how a model stores state, measures error, updates, and decides when it is good enough.
- Optimizers are part of the machine learning algorithm which work to minimize the loss by updating the weights in order to make the
loss functionsmaller and get more accurate predictions. - Data is divided into the categories of Training, Test, Feature, and Label, with the Actual Train Data and Cross-Validation Data being two subsets of the Training data which helps to test the accuracy of the model by exposing it to both seen and unseen data.
- Machine Learning consists of two main classes: Supervised Learning, which uses labeled data, and Unsupervised Learning, which does not require labels and is more difficult to measure the "goodness" of a model.
- Machine learning can be divided into two categories; instance-based learning, which does not save weights for later use, and model-based learning, which saves weights for future use and can be improved upon with additional data.
- - ML categories often describe either the data setup or how the algorithm stores what it learned.
- - Supervised/unsupervised is about labels; instance/model-based is about how learning is stored and reused.
- Machine learning algorithms can be divided into two categories: online learning, where data is given live while the training loop is running, and offline, or batch, learning, where data is given all at once.
- Unsupervised ML is a
type of Machine Learning algorithmthat discovers patterns or similarities within data sets without the need for labeled data. - Understanding the
fundamentals of machine learningis essential to succeeding with machine learning, and it is recommended to go through the example algorithm multiple times to gain a better understanding.