Low-Latency C++ for HFT
Read at your own pace. Code execution, quizzes, progress tracking, and the AI tutor are available in the interactive view with JavaScript enabled.
Why Low Latency
From market data to decisions
In Course Overview & Environment Setup, you built the toolchain and measured a tiny program. In Market Microstructure & Data Feeds, you saw quotes, trades, sequence numbers, and timestamps.
Now we connect those ideas to C++ performance:
market event -> parse -> update state -> decide -> emit action
In HFT, latency is not just “make it fast.” It means:
- Predictable runtime: fewer surprise pauses
- Low tail latency: not just average speed, but rare slow cases
- Cache-aware data: the CPU should find what it needs quickly
- Measured decisions: optimize only after timing
This lesson stays inside one process and one thread. Later lessons will handle networking, kernel bypass, and lock-free concurrency.

Latency Budget
Think in budgets
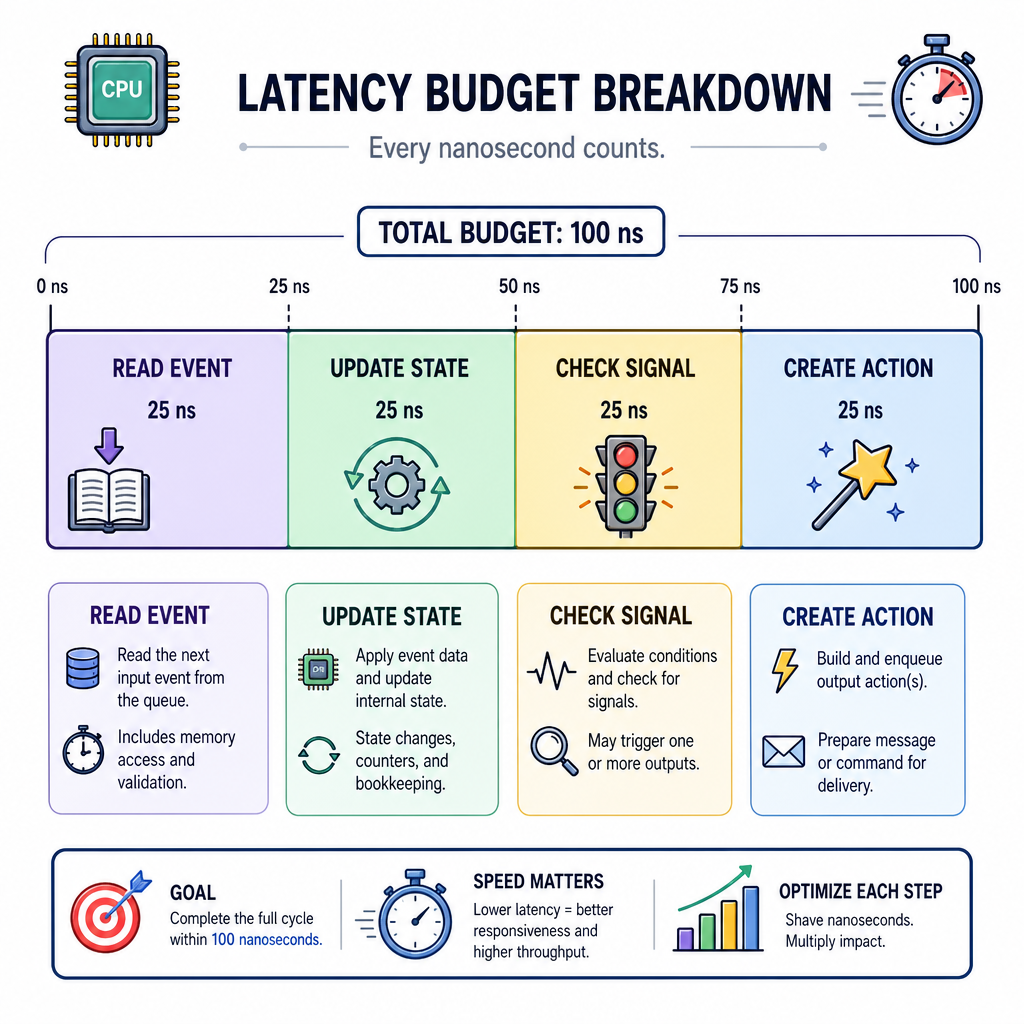
A low-latency C++ system is easier to reason about when each stage has a budget.
Example target for a simplified hot path:
Read decoded event       50 ns
Update instrument state  80 ns
Check simple signal      40 ns
Create internal action   60 ns
--------------------------------
Total                   230 ns
The exact numbers are less important than the habit: every operation spends time.
Two important terms:
- Hot path: code executed for every market event or order decision
- Cold path: startup, configuration, logging setup, error reporting, admin tools
Beginner-friendly rule: put complexity in the cold path when possible, and keep the hot path boring, small, and measurable.
Measure First
A tiny benchmark harness
Before optimizing, measure. C++ gives you low-level control, but also many ways to fool yourself.
This small program measures a simple integer loop. It is not a perfect benchmark, but it demonstrates the basic workflow:
- Run enough iterations
- Prevent the compiler from deleting the work
- Print total time and time per operation
Compile with optimization enabled, for example:
g++ -O2 -std=c++17 measure.cpp && ./a.out
```cpp
#include <chrono>
#include <cstdint>
#include <iostream>

volatile std::uint64_t sink = 0;

int main() {
    constexpr std::uint64_t N = 50'000'000;
    std::uint64_t x = 0;

    auto start = std::chrono::steady_clock::now();

    for (std::uint64_t i = 0; i < N; ++i) {
        x += (i * 3) ^ (i >> 2);
    }

    sink = x;

    auto end = std::chrono::steady_clock::now();
    auto ns = std::chrono::duration_cast<std::chrono::nanoseconds>(end - start).count();

    std::cout << "result=" << sink << "\n";
    std::cout << "total_ns=" << ns << "\n";
    std::cout << "ns_per_iteration=" << static_cast<double>(ns) / N << "\n";
}
```
Hot Path Check
Which operation is usually most suspicious inside a per-market-event hot path?
Cache Shapes
The CPU is fast; memory is not
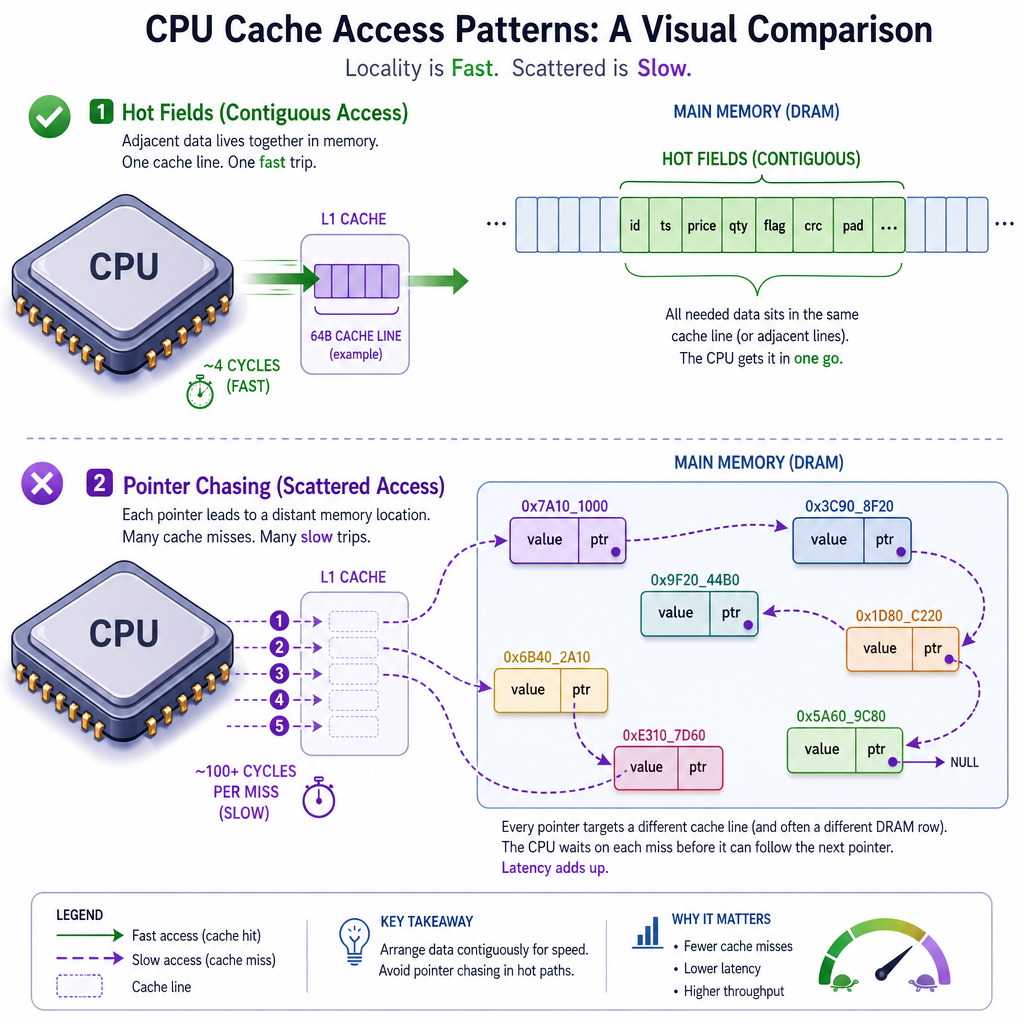
Modern CPUs can execute simple arithmetic extremely quickly. But if data is far away in memory, the CPU waits.
For HFT code, this means data layout matters.
Common low-latency preferences:
- Keep hot fields close together
- Avoid pointer chasing in the hot path
- Prefer contiguous arrays when scanning many items
- Keep rarely used fields away from frequently used fields
Imagine tracking many instruments. If your strategy only needs bid, ask, and last_trade_price, placing those fields in a compact, predictable layout can matter more than adding clever code.
Layout Experiment
Contiguous data helps scans
This example compares two ways to store market state for many instruments:
- Array of structs: each instrument keeps all fields together
- Struct of arrays: each field has its own contiguous array
If we only scan bid, struct-of-arrays often gives the CPU a simpler memory pattern. Real results depend on your CPU and compiler, so treat this as a measurement habit, not a universal law.
```cpp
#include <chrono>
#include <cstdint>
#include <iostream>
#include <vector>

struct QuoteAOS {
    double bid;
    double ask;
    double last;
    std::uint64_t seq;
};

volatile double double_sink = 0.0;

template <typename F>
long long time_ns(F&& f) {
    auto start = std::chrono::steady_clock::now();
    f();
    auto end = std::chrono::steady_clock::now();
    return std::chrono::duration_cast<std::chrono::nanoseconds>(end - start).count();
}

int main() {
    constexpr std::size_t N = 2'000'000;

    std::vector<QuoteAOS> aos(N);
    std::vector<double> bids(N), asks(N), lasts(N);

    for (std::size_t i = 0; i < N; ++i) {
        double price = 100.0 + static_cast<double>(i % 100) * 0.01;
        aos[i] = QuoteAOS{price, price + 0.01, price - 0.02, i};
        bids[i] = price;
        asks[i] = price + 0.01;
        lasts[i] = price - 0.02;
    }

    double sum1 = 0.0;
    auto aos_ns = time_ns([&] {
        for (const auto& q : aos) sum1 += q.bid;
    });

    double sum2 = 0.0;
    auto soa_ns = time_ns([&] {
        for (double b : bids) sum2 += b;
    });

    double_sink = sum1 + sum2;

    std::cout << "aos_bid_scan_ns=" << aos_ns << "\n";
    std::cout << "soa_bid_scan_ns=" << soa_ns << "\n";
    std::cout << "checksum=" << double_sink << "\n";
}
```
Allocation Claim
True or false: calling reserve() on a std::vector guarantees the vector will never allocate again, no matter how many elements are later inserted.
Preallocate Buffers
Move allocation out of the hot path
A common HFT C++ pattern is:
- Allocate during startup
- Reuse memory during event processing
- Avoid unexpected growth in the hot path
std::vector::reserve() is not magic, but it lets you prepare capacity before processing begins.
The program below logs when vector capacity changes. Capacity changes are a clue that allocation may have happened.
```cpp
#include <iostream>
#include <vector>

void push_and_log(const char* label, std::vector<int>& v, int count) {
    std::cout << label << "\n";
    std::size_t last_capacity = v.capacity();
    std::cout << "initial_capacity=" << last_capacity << "\n";

    for (int i = 0; i < count; ++i) {
        v.push_back(i);
        if (v.capacity() != last_capacity) {
            last_capacity = v.capacity();
            std::cout << "  capacity_changed_at_size=" << v.size()
                      << " new_capacity=" << last_capacity << "\n";
        }
    }
}

int main() {
    constexpr int events = 20;

    std::vector<int> without_reserve;
    push_and_log("without reserve", without_reserve, events);

    std::vector<int> with_reserve;
    with_reserve.reserve(events);
    push_and_log("with reserve", with_reserve, events);
}
```
Name The Path
Fill in the blank: Code executed for every market event or decision is called the ______.
Latency Checklist
What to carry forward
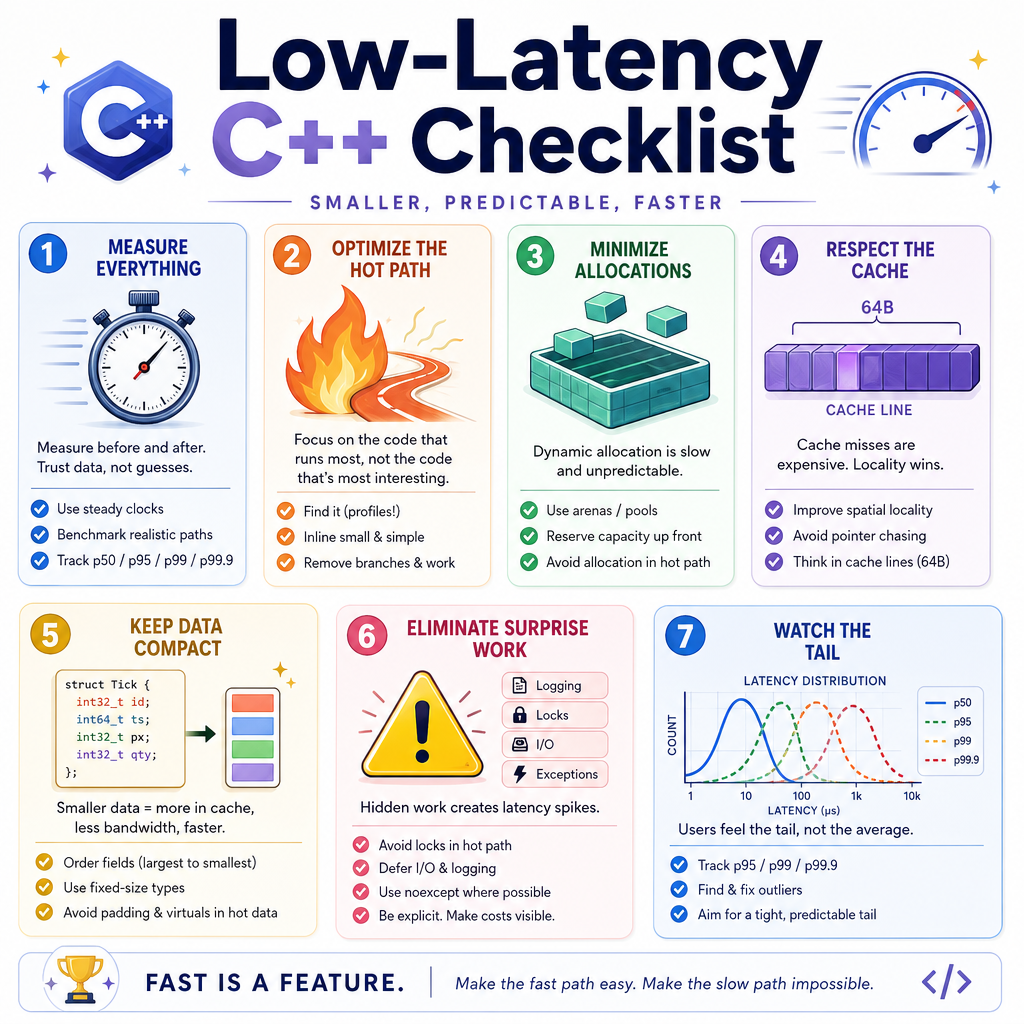
Low-latency C++ is not about using obscure tricks first. It is about building code that is measurable and predictable.
Use this checklist when writing HFT-style C++:
- Measure before and after every optimization
- Separate hot path from cold path
- Preallocate buffers used during event processing
- Prefer contiguous data for scans and tight loops
- Keep hot structs small and focused on frequently used fields
- Avoid surprise work: allocation, formatting, exceptions, excessive logging
- Watch tail latency, not only average latency
In the next lesson, we will move closer to the machine boundary and discuss how market data reaches your process through networking choices.