Data Retrieval and Preprocessing
Read at your own pace. Code execution, quizzes, progress tracking, and the AI tutor are available in the interactive view with JavaScript enabled.
From Idea to Data
Why this lesson matters
In Introduction to Algorithmic Trading, you built the mental model of a trading system: observe data, make decisions, manage risk, and execute under constraints.
Now we zoom into the first engineering dependency: market data quality.
A creative alternative algorithm is only as good as the time series it consumes. Before we build models, backtests, or live deployment logic, we need a dependable pipeline that can:
- Retrieve raw market data
- Validate schema and timestamps
- Clean missing or duplicated records
- Aggregate data into multiple time frames
- Produce safe numeric inputs for later trading logic
Think of this lesson as building the “data intake valve” for the rest of the course.
API / CSV / Feed
      ↓
Raw ticks or candles
      ↓
Validation + cleaning
      ↓
Aligned time series
      ↓
Multi-time-frame bars
      ↓
Model-ready features
We will stay focused on retrieval and preprocessing. We’ll briefly prepare data for future modeling, but we will not build trading signals yet.

Data Has Contracts
Treat market data like an API contract
When retrieving financial data, do not think only in terms of “download prices.” Think in terms of a contract between the data provider and your C++ system.
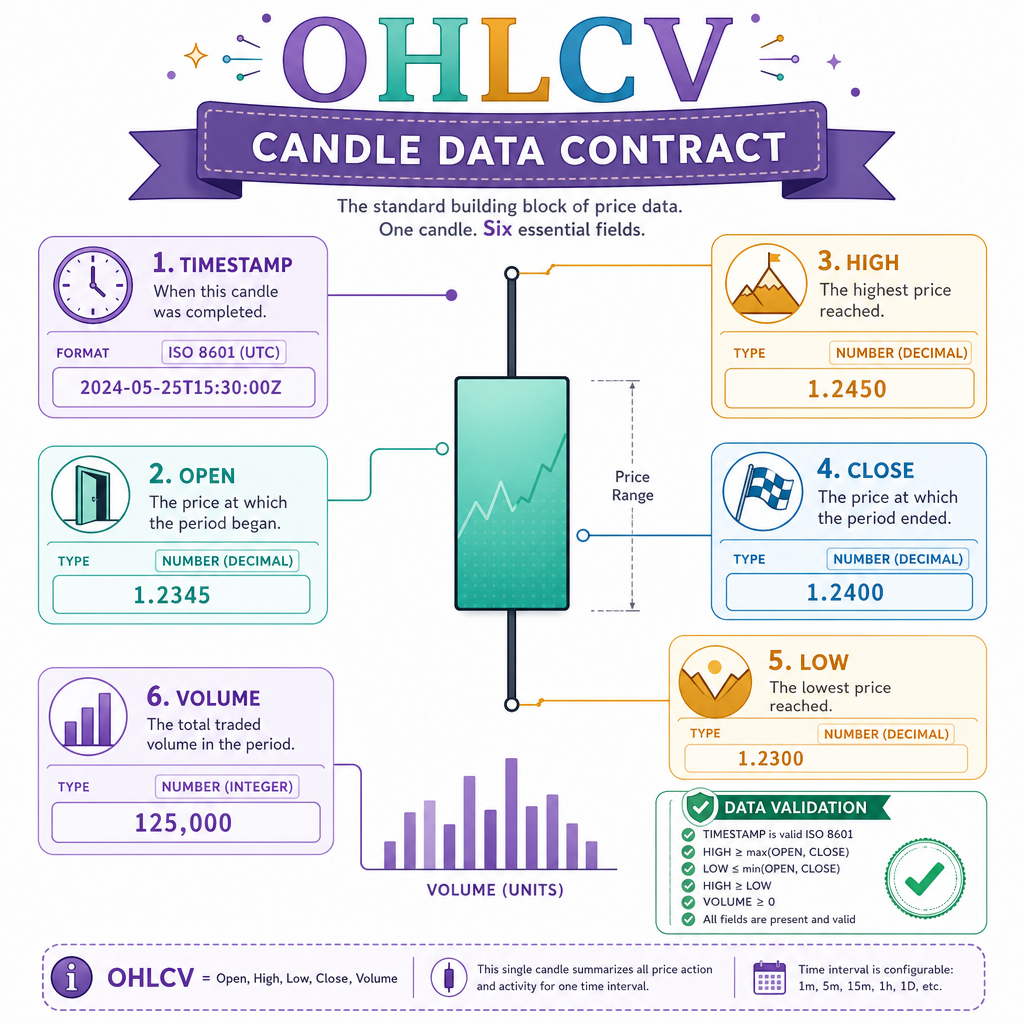
A basic OHLCV candle contract usually contains:
Field Meaningtimestamp
Start or end time of the bar, depending on provider
open
First traded price in the interval
high
Highest traded price in the interval
low
Lowest traded price in the interval
close
Last traded price in the interval
volume
Total traded quantity or notional volume
Before doing math, ask:
- Is the timestamp UTC, exchange-local, or Unix epoch?
- Is each bar start-labeled or end-labeled?
- Are weekends/holidays included as gaps or omitted?
- Is volume actual traded quantity, quote currency, or adjusted volume?
- Are prices adjusted for splits/dividends?
For innovative algorithms, especially ones using unusual time aggregation or alternative signals, these details matter. A subtle timestamp convention can shift your entire strategy by one bar.
Parse Raw Candles
A small C++ ingestion step
In production, retrieval may come from REST APIs, WebSockets, broker SDKs, or archived CSV files. The preprocessing mindset is the same: convert provider-specific data into your internal format.
Below is a standalone example that parses simple CSV candle data into a typed C++ structure, sorts by timestamp, and prints the normalized result.
This is intentionally small. The goal is not to build a full CSV parser; it is to make the ingestion boundary explicit.
```cpp
#include <algorithm>
#include <iostream>
#include <sstream>
#include <string>
#include <vector>

struct Candle {
    long long timestamp; // Unix seconds, UTC
    double open;
    double high;
    double low;
    double close;
    double volume;
};

Candle parseLine(const std::string& line) {
    std::stringstream ss(line);
    std::string cell;
    std::vector<std::string> parts;

    while (std::getline(ss, cell, ',')) {
        parts.push_back(cell);
    }

    return Candle{
        std::stoll(parts[0]),
        std::stod(parts[1]),
        std::stod(parts[2]),
        std::stod(parts[3]),
        std::stod(parts[4]),
        std::stod(parts[5])
    };
}

int main() {
    std::string csv =
        "1700000060,101.0,103.0,100.5,102.5,1500\n"
        "1700000000,100.0,102.0,99.5,101.0,1200\n";

    std::stringstream input(csv);
    std::string line;
    std::vector<Candle> candles;

    while (std::getline(input, line)) {
        if (!line.empty()) {
            candles.push_back(parseLine(line));
        }
    }

    std::sort(candles.begin(), candles.end(), [](const Candle& a, const Candle& b) {
        return a.timestamp < b.timestamp;
    });

    std::cout << "Normalized candles:\n";
    for (const auto& c : candles) {
        std::cout << c.timestamp << " close=" << c.close
                  << " volume=" << c.volume << "\n";
    }

    return 0;
}
```
First Validation Check
You retrieved 1-minute OHLCV candles from a provider and want to preprocess them before any calculations.
Which validation check should usually happen first?
Time Alignment Rules
Clean time before cleaning price
Financial data is a time series, so timestamp handling is not a side detail. It is the index of your entire system.
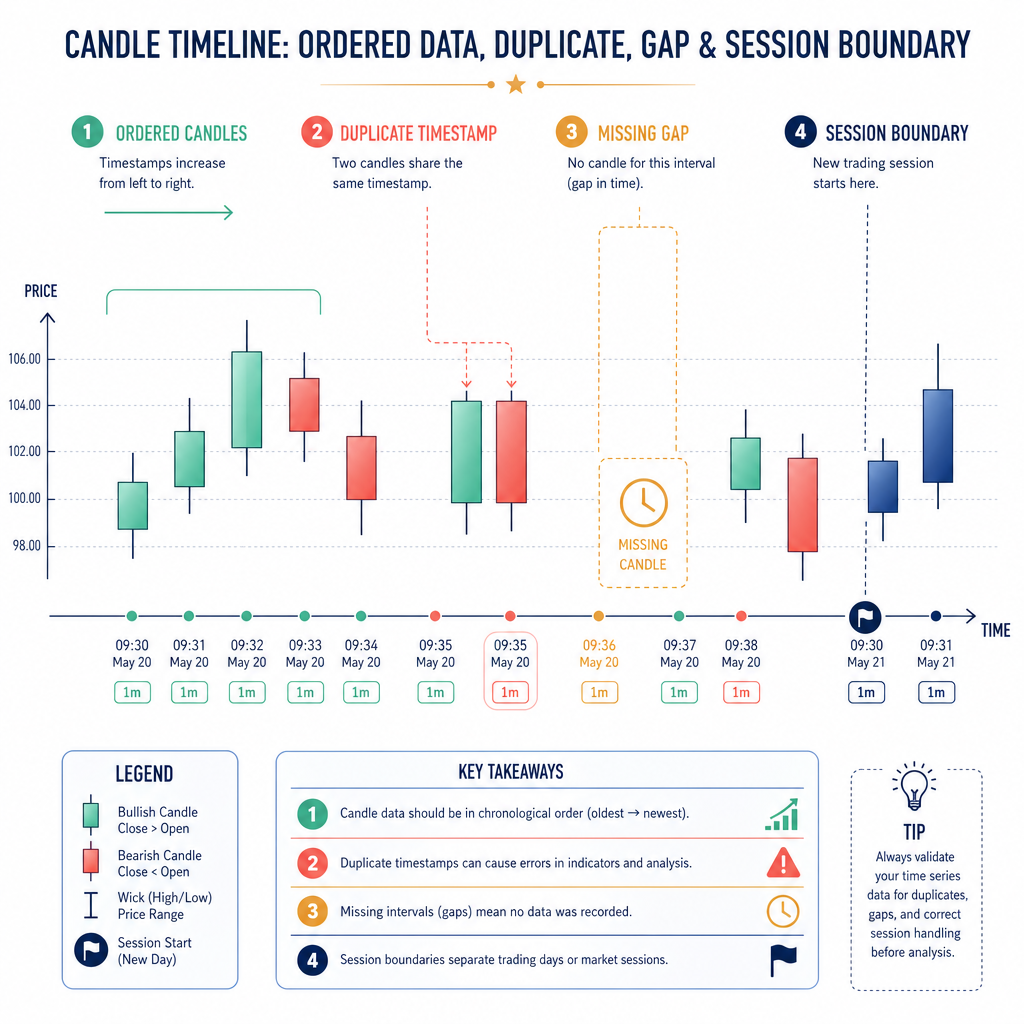
A preprocessing layer should define rules for:
1. Sorting
Always process candles in chronological order.
2. Deduplication
If two records share the same timestamp, decide which one wins:
- Latest provider revision?
- Highest volume record?
- Reject both and log an error?
3. Gap detection
For 1-minute candles, timestamps should usually differ by 60 seconds during active trading.
Expected: 09:30, 09:31, 09:32, 09:33
Observed: 09:30, 09:31,       09:33
                         ↑ gap
4. Session awareness
Markets have schedules. Crypto trades continuously; equities usually do not. A missing Saturday equity candle is not the same as a missing Tuesday morning candle.
The key habit: never silently repair time series data without recording what you changed.
Expected Gap Size
For a properly aligned 1-minute candle series using Unix seconds, the expected difference between consecutive timestamps is ____ seconds during an active continuous session.
Build Larger Bars
Aggregating time frames
This course section emphasizes dynamic time series and multiple time frames. Preprocessing is where that foundation begins.
Given smaller bars, such as 1-minute candles, we can aggregate them into larger bars, such as 5-minute candles.
For each aggregated bucket:
-
open= first open in the bucket -
high= maximum high in the bucket -
low= minimum low in the bucket -
close= last close in the bucket -
volume= sum of volume in the bucket
The following C++ example aggregates 1-minute candles into 5-minute candles. Notice that we are still preparing data, not deciding whether to trade.
```cpp
#include <algorithm>
#include <iostream>
#include <limits>
#include <map>
#include <vector>

struct Candle {
    long long timestamp;
    double open, high, low, close, volume;
};

int main() {
    std::vector<Candle> oneMinute = {
        {1700000000, 100, 101,  99, 100.5, 10},
        {1700000060, 100.5, 102, 100, 101.5, 12},
        {1700000120, 101.5, 103, 101, 102.0, 9},
        {1700000180, 102.0, 104, 101.8, 103.5, 15},
        {1700000240, 103.5, 105, 103, 104.0, 20},
        {1700000300, 104.0, 106, 103.5, 105.0, 18}
    };

    const long long bucketSize = 5 * 60;
    std::map<long long, std::vector<Candle>> buckets;

    for (const auto& c : oneMinute) {
        long long bucketStart = (c.timestamp / bucketSize) * bucketSize;
        buckets[bucketStart].push_back(c);
    }

    std::cout << "5-minute candles:\n";
    for (const auto& [bucketStart, bars] : buckets) {
        Candle out;
        out.timestamp = bucketStart;
        out.open = bars.front().open;
        out.close = bars.back().close;
        out.high = -std::numeric_limits<double>::infinity();
        out.low = std::numeric_limits<double>::infinity();
        out.volume = 0.0;

        for (const auto& b : bars) {
            out.high = std::max(out.high, b.high);
            out.low = std::min(out.low, b.low);
            out.volume += b.volume;
        }

        std::cout << out.timestamp
                  << " O=" << out.open
                  << " H=" << out.high
                  << " L=" << out.low
                  << " C=" << out.close
                  << " V=" << out.volume << "\n";
    }

    return 0;
}
```
Silent Filling
True or false:
It is safe to fill missing intraday candles by copying the previous candle’s OHLCV values without recording that the data was imputed.
Preprocess Numeric Inputs
Prepare math-safe series
Once candles are ordered, cleaned, and aligned, we can compute simple numeric transformations that later components may use.
Common preprocessing outputs include:
- Returns instead of raw prices
- Log returns for additive time behavior
- Rolling mean or rolling volatility
- Normalized volume
- Flags for missing or imputed data
This does not make a trading model yet. It only converts raw market data into safer mathematical inputs.
Below, we compute simple returns and log returns from closing prices.
```cpp
#include <cmath>
#include <iomanip>
#include <iostream>
#include <vector>

int main() {
    std::vector<double> close = {100.0, 101.0, 100.5, 102.0, 104.0};

    std::cout << std::fixed << std::setprecision(5);
    std::cout << "index close simple_return log_return\n";

    for (std::size_t i = 1; i < close.size(); ++i) {
        double simpleReturn = (close[i] - close[i - 1]) / close[i - 1];
        double logReturn = std::log(close[i] / close[i - 1]);

        std::cout << i << " "
                  << close[i] << " "
                  << simpleReturn << " "
                  << logReturn << "\n";
    }

    return 0;
}
```
Pipeline Handoff
What your preprocessing layer should output
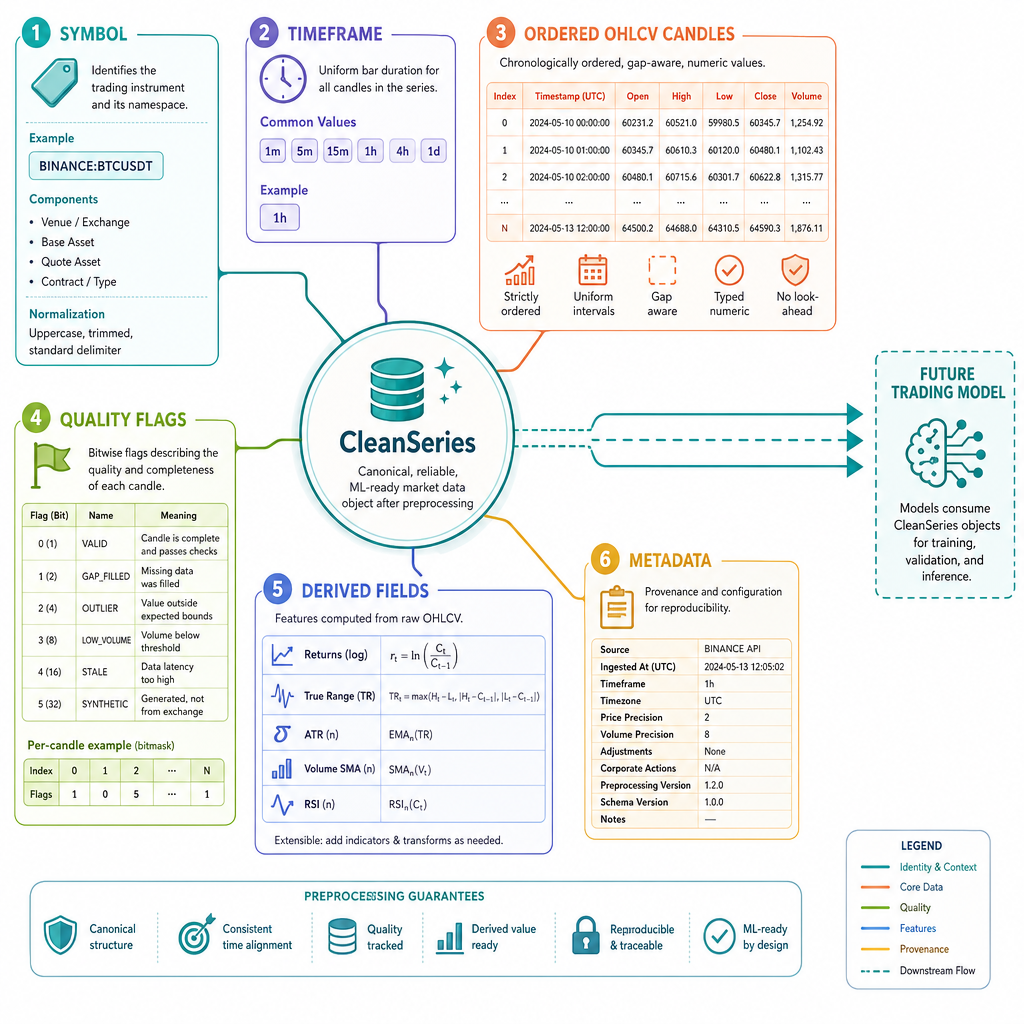
By the end of retrieval and preprocessing, your C++ system should be able to hand later components a clean structure like this:
CleanSeries
├── symbol: BTC-USD or AAPL
├── timeframe: 1m, 5m, 1h, ...
├── candles: ordered OHLCV records
├── quality flags: gaps, duplicates, imputed bars
├── derived fields: returns, log returns, normalized values
└── metadata: provider, timezone, adjustment policy
This is the bridge from engineering to strategy.
A strong preprocessing layer lets you experiment with alternative financial algorithms without repeatedly solving the same messy data problems. In the next lesson, Building Trading Models, you’ll use clean time series as inputs for decision logic.