Data Structure and Algorithm Fundamentals
Read at your own pace. Code execution, quizzes, progress tracking, and the AI tutor are available in the interactive view with JavaScript enabled.
Course Starting Point
Why this lesson matters
You already have years of hands-on DSA practice, so this lesson will not treat data structures as trivia. Instead, we’ll reset the fundamentals the way interviewers at Google, Microsoft, and Amazon often evaluate them:
- Can you choose the right structure under constraints?
- Can you explain the tradeoff clearly?
- Can you reason about time, space, and implementation details in Java?
- Can you avoid overengineering when a simple structure is enough?
In simple terms: data structures are how we arrange data so that the operations we care about become cheap.
This first lesson builds the foundation. Next, we’ll use these tools in Problem Solving Techniques, then later connect engineering judgment to System Design and Scalability.

Structure As Contract
Think in operations, not names
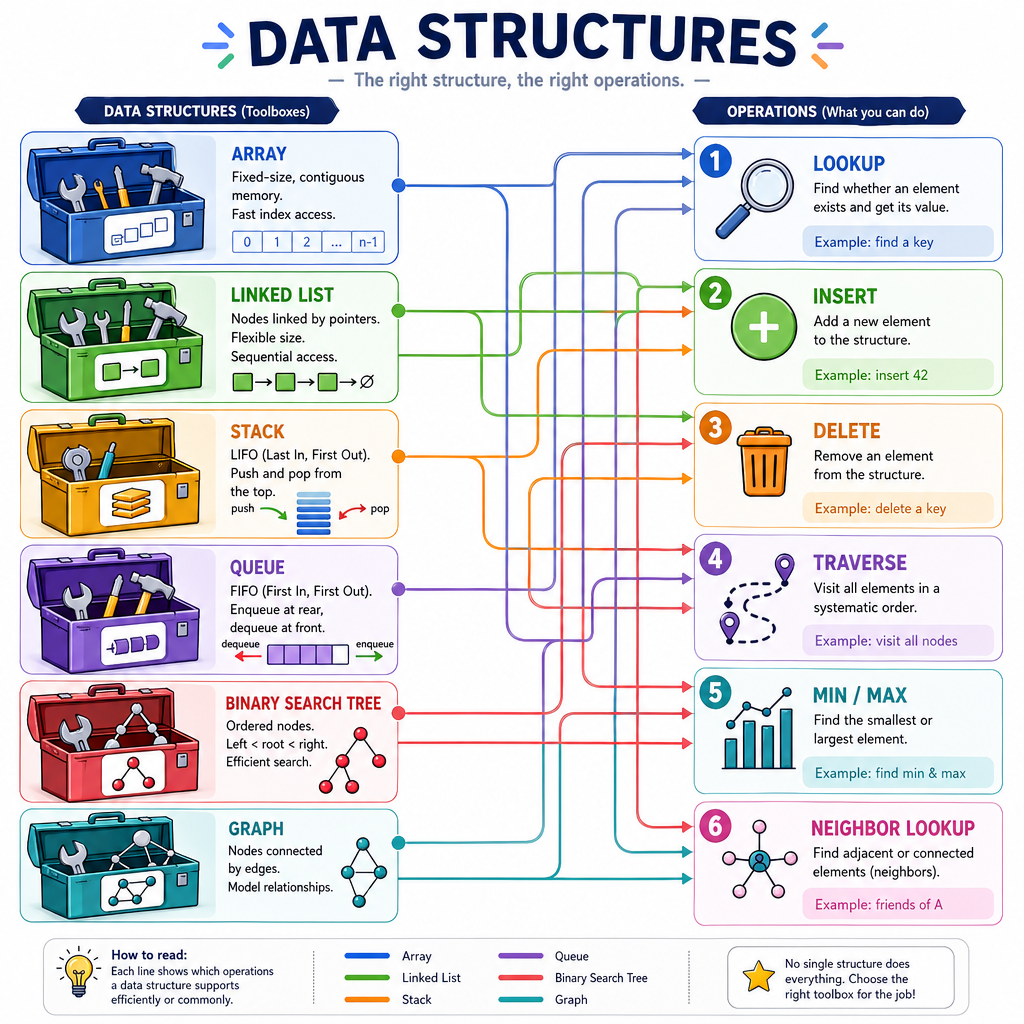
A data structure is a contract around operations.
Instead of asking, “Should I use an array, hash map, or tree?”, ask:
Need Operation Good candidates Access by indexget(i)
Array, ArrayList
Lookup by key
containsKey(k)
HashMap, HashSet
Maintain order
sorted traversal
Tree, heap depending on need
Process newest first
push/pop
Stack / Deque
Process oldest first
offer/poll
Queue / Deque
Model relationships
neighbors
Graph adjacency list
For senior interviews, the expected answer is rarely just “use a map.” It is usually: use a map because lookup dominates, ordering is irrelevant, and memory overhead is acceptable.
Cost Beats Syntax
Big-O is about growth
Interviewers care less about whether you remember a table and more about whether you can predict what happens as input grows.
A simple example: looking up whether an ID exists.
- With a list, worst-case search checks many elements: O(n)
- With a hash set, average lookup is direct: O(1)
The syntax difference in Java is small. The performance difference can dominate the whole solution.
```java
import java.util.*;

public class Main {
    public static void main(String[] args) {
        List<Integer> idsList = new ArrayList<>();
        Set<Integer> idsSet = new HashSet<>();

        for (int i = 1; i <= 10; i++) {
            idsList.add(i);
            idsSet.add(i);
        }

        int target = 10;
        int comparisons = 0;
        boolean foundInList = false;

        for (int id : idsList) {
            comparisons++;
            if (id == target) {
                foundInList = true;
                break;
            }
        }

        boolean foundInSet = idsSet.contains(target);

        System.out.println("List found: " + foundInList + ", comparisons: " + comparisons);
        System.out.println("Set found: " + foundInSet + ", average lookup: O(1)");
    }
}
```
Choose Lookup Structure
You are processing millions of user events. For each event, you need to quickly check whether the userId is in a known banned-user collection. Ordering does not matter.
Which data structure is the best default choice?
Arrays And Lists
Contiguous storage mindset
Arrays and ArrayList are strong when you need:
- Fast indexed access:
arr[i],list.get(i) - Compact memory locality
- Simple iteration
- Append-heavy behavior
But they are weaker when you frequently insert/delete in the middle, because elements may need shifting.
In Java:
-
int[]is fixed-size and primitive-friendly -
ArrayList<Integer>resizes dynamically but boxes primitives - Random access is cheap
- Middle insertion is usually expensive
A useful interview phrase: arrays optimize access; linked structures optimize local rewiring, but often lose on cache locality and traversal cost.
```java
import java.util.*;

public class Main {
    public static void main(String[] args) {
        List<String> names = new ArrayList<>();
        names.add("Asha");
        names.add("Ben");
        names.add("Chen");

        System.out.println("Index 1 before insert: " + names.get(1));

        names.add(1, "Dina"); // shifts Ben and Chen to the right

        System.out.println("After middle insert: " + names);
        System.out.println("Index 1 after insert: " + names.get(1));
    }
}
```
Linked List Trap
True or false:
LinkedList is always better than ArrayList for insertions and deletions because pointer changes are O(1).
Maps And Sets
Hashing gives direct access
HashMap and HashSet are interview workhorses because they turn repeated scanning into direct lookup.
Use them when you need:
- Frequency counts
- Membership checks
- Deduplication
- Key-to-value association
- Seen-before detection
Java details worth remembering:
-
HashMapaverage operations: O(1) - Worst case can degrade, though Java treeifies heavy collision buckets in modern implementations
- Correct
equals()andhashCode()are mandatory for custom keys -
LinkedHashMappreserves insertion order -
TreeMapkeeps keys sorted with O(log n) operations
```java
import java.util.*;

public class Main {
    public static void main(String[] args) {
        String[] events = {"login", "click", "login", "purchase", "click", "login"};
        Map<String, Integer> frequency = new HashMap<>();

        for (String event : events) {
            frequency.put(event, frequency.getOrDefault(event, 0) + 1);
        }

        System.out.println("Event frequencies: " + frequency);
        System.out.println("Login count: " + frequency.get("login"));
        System.out.println("Contains refund? " + frequency.containsKey("refund"));
    }
}
```
Stack Queue Heap
Data flow structures
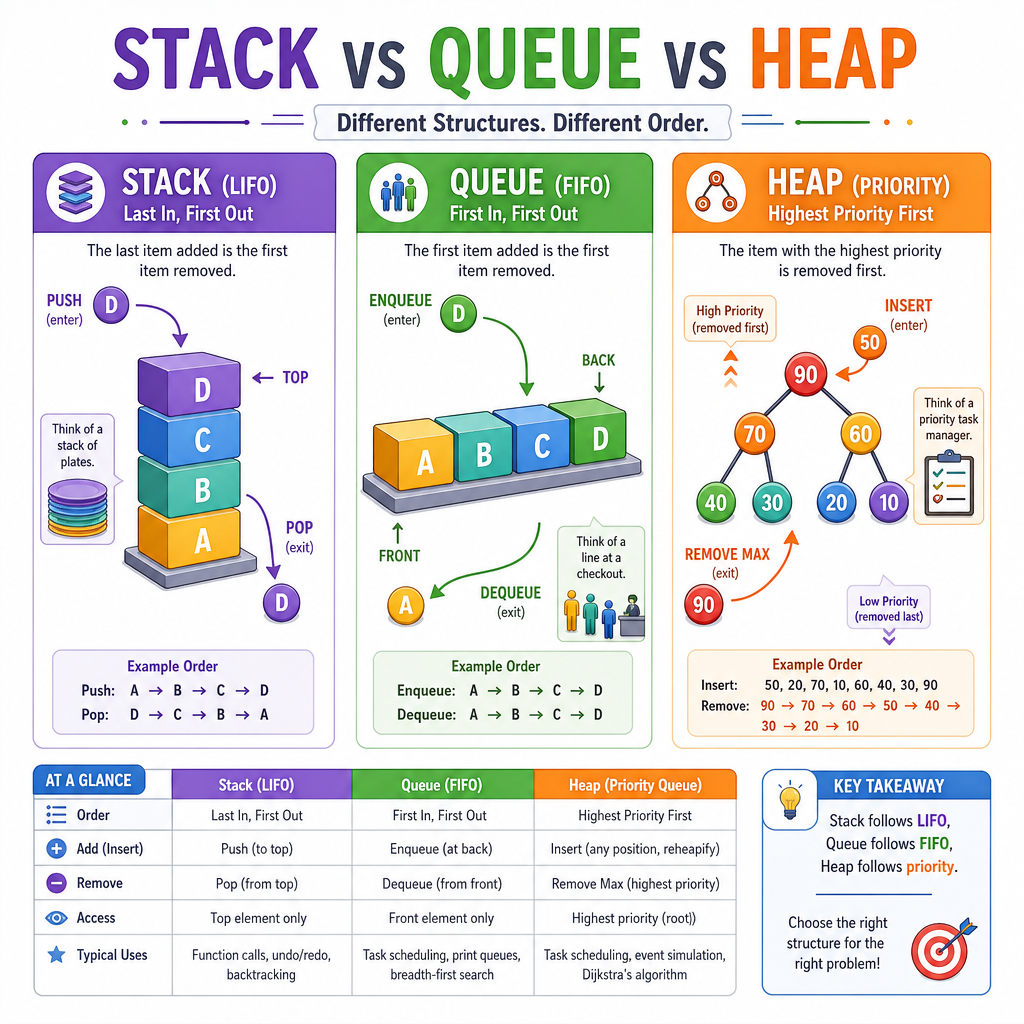
Some structures are less about storage and more about processing order.
Stack: LIFO
Last in, first out.
push A, push B, push C
pop -> C
Common uses: parsing, backtracking, undo behavior, DFS implementation.
Queue: FIFO
First in, first out.
offer A, offer B, offer C
poll -> A
Common uses: task scheduling, BFS implementation, producer-consumer pipelines.
Heap / PriorityQueue
Always retrieves the highest-priority item according to a comparator.
In Java, PriorityQueue is a min-heap by default.
Use Deque for stack/queue behavior in modern Java rather than legacy Stack.
Java Queue Type
Fill in the blank:
In modern Java, the common interface used for FIFO operations such as offer() and poll() is _____.
Trees And Graphs
Relationships and hierarchy
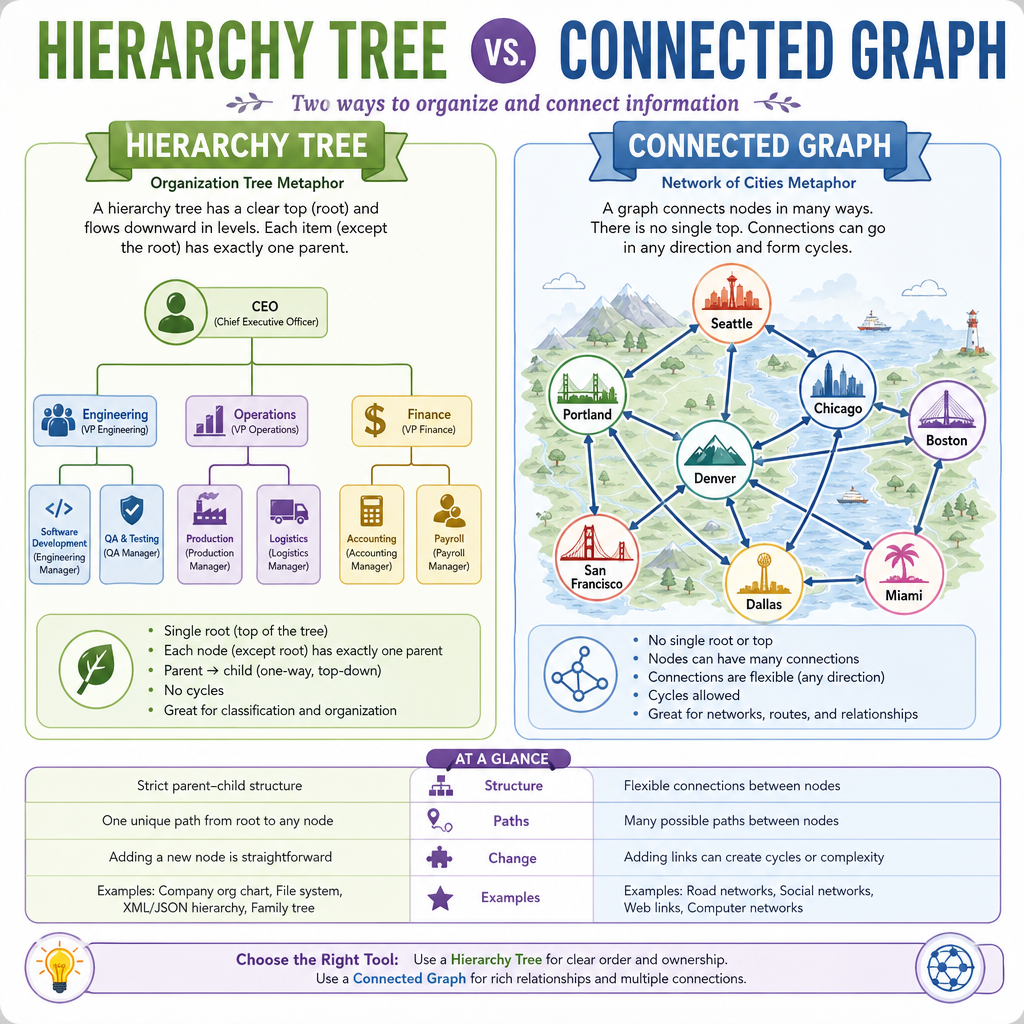
Trees and graphs model relationships rather than simple linear storage.
Tree
A tree is usually hierarchical:
        CEO
       /   \
    Eng    Sales
   /   \
 API   ML
Common interview structures:
- Binary tree
- Binary search tree
- Trie
- Segment tree
- Heap as a tree-shaped structure
Graph
A graph models arbitrary connections:
A -- B -- C
|    |
D -- E
Common representations:
- Adjacency list: efficient for sparse graphs
- Adjacency matrix: useful when edge lookup dominates and space is acceptable
For this lesson, the key is not memorizing every variant. The key is recognizing when data is linear, keyed, prioritized, hierarchical, or connected.
Fundamental Decision
You need to store employee records and repeatedly answer: “Who are the direct reports of this manager?” Each employee has exactly one manager except the CEO.
Which model best fits the data?