Hashmaps: Efficient Data Retrieval
Read at your own pace. Code execution, quizzes, progress tracking, and the AI tutor are available in the interactive view with JavaScript enabled.
Why Hashmaps Now
From movement to instant access
In Graphs: Concepts and Operations, you learned how adjacency lists help us move through connected data. In Recursion: Principles and Algorithms, you learned how a problem can shrink step by step until it reaches a base case.
Now we switch to a different superpower: retrieving information quickly.
A hashmap stores data as key-value pairs:
- key: what you search by
- value: what you want back
Think:
- basketball jersey number → player name
- case file ID → evidence summary
- username → account profile
The goal is simple but powerful: given a key, find its value without scanning everything.
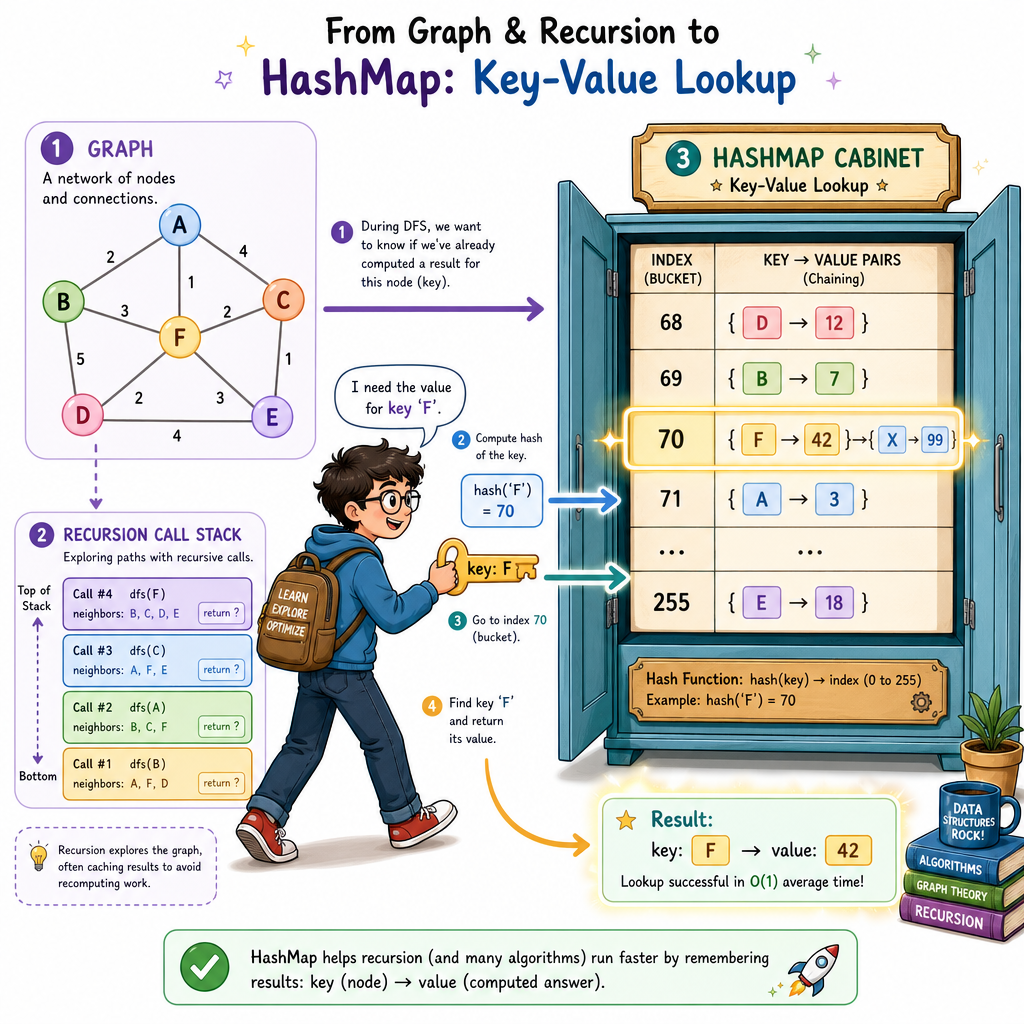
Key Value Thinking
A hashmap is like labeled storage
Instead of asking, “Where is this item in the list?”, a hashmap asks:
“What label should take me directly to the item?”
Example mental model:
Key                Value
--------------------------------
"LeBron"       -> 23
"Curry"        -> 30
"Jokic"        -> 15
"case-1042"    -> "fingerprint report"
The key should be something you can identify exactly. The value can be almost anything: a number, string, list, object, or another data structure.
In Python, the built-in hashmap type is called a dictionary, or dict.
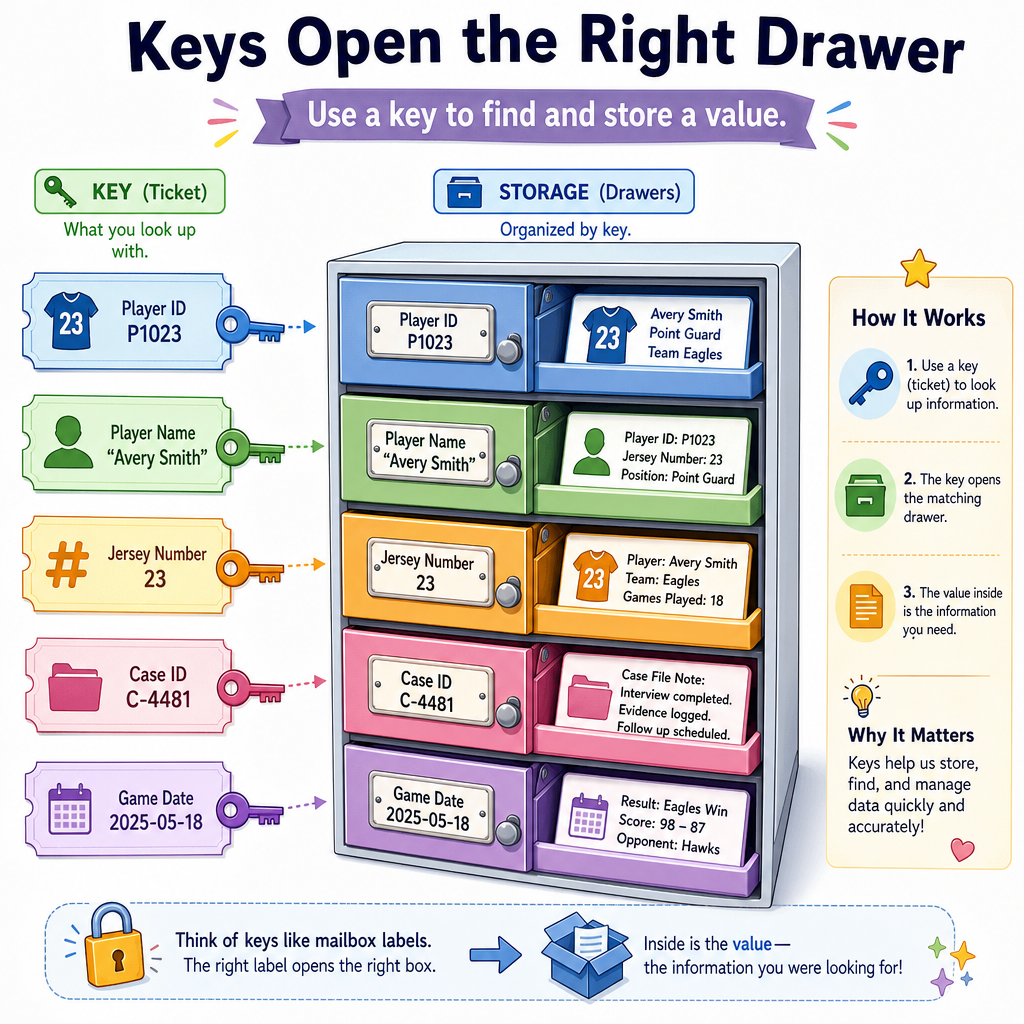
Python Dict Basics
Insert, retrieve, update, delete
Python dictionaries give us hashmap behavior directly.
The core operations are:
- insert: add a new key-value pair
- retrieve: get the value for a key
- update: replace the value for an existing key
- delete: remove a key-value pair
Here is a small basketball roster example.
```python
# Python dictionaries are hashmaps.
roster = {}

# Insert
roster[23] = "Jordan"
roster[30] = "Curry"
roster[15] = "Jokic"

print("Initial roster:", roster)

# Retrieve
print("Player wearing #30:", roster[30])

# Update
roster[23] = "LeBron"
print("Updated #23:", roster[23])

# Delete
del roster[15]
print("After deleting #15:", roster)

# Safe retrieval when a key might not exist
print("Player wearing #7:", roster.get(7, "not found"))
```
Best Lookup Tool
You have 50,000 case-file IDs, and each ID maps to the detective assigned to that case.
You frequently need to answer: “Who owns case A17-902?”
Which structure is the best fit?
How Hashing Works
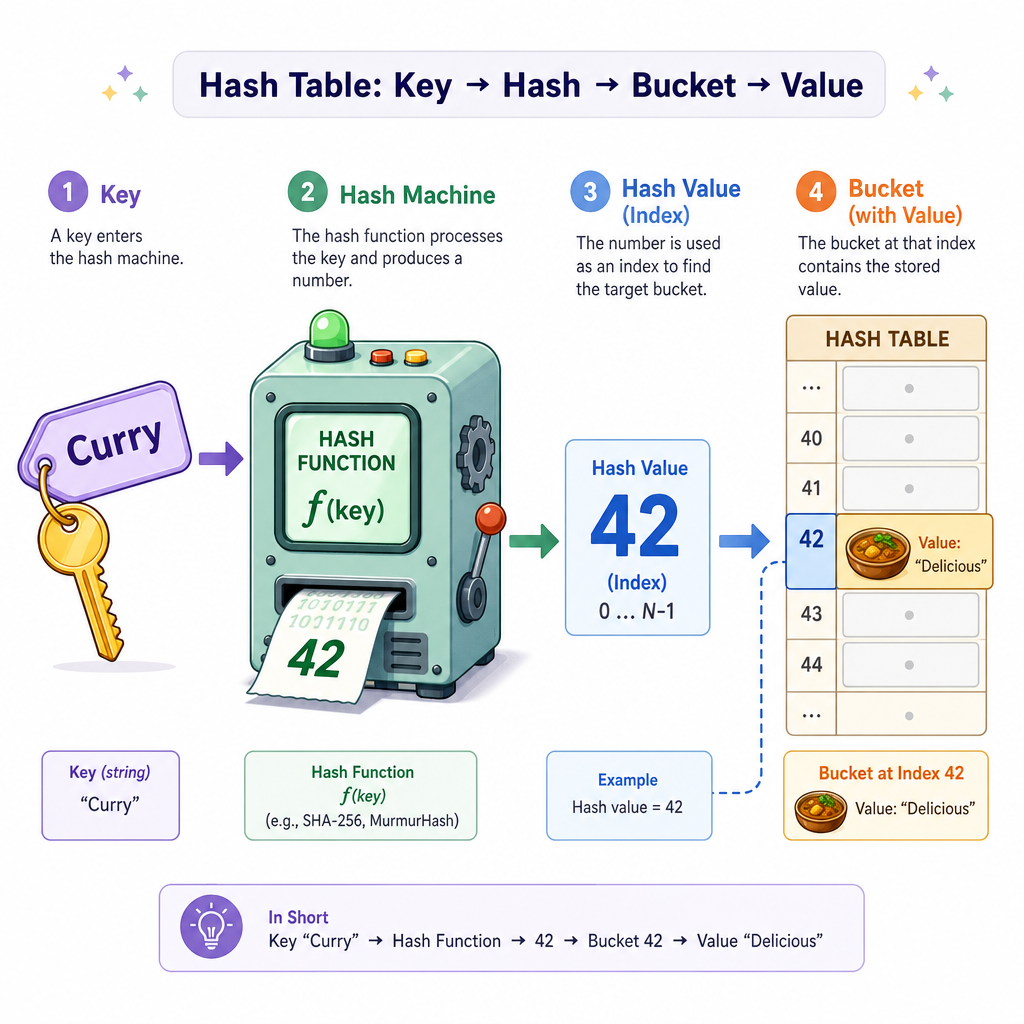
The secret step: hashing
A hashmap does not usually store keys in neat sorted order. Instead, it uses a hash function.
A hash function turns a key into a number, and that number helps choose where the value should live internally.
key -> hash function -> bucket/index -> value
For example:
"Curry" -> hash(...) -> 42 -> "Warriors guard"
You do not need to design Python's hash function to use dictionaries. But understanding the idea helps explain why lookups can often be so fast.
When Keys Collide
Two keys can land together
A collision happens when two different keys map to the same internal location.
That sounds bad, but hashmaps are designed for it.
Two common strategies are:
- Chaining: each bucket stores a small list of key-value pairs
- Open addressing: if a spot is taken, search for another spot using a rule
Below is a tiny educational hashmap using chaining. It is not meant to replace Python's dict; it is just a clear model of the idea.
```python
class TinyHashMap:
    def __init__(self, bucket_count=4):
        self.buckets = [[] for _ in range(bucket_count)]

    def _index(self, key):
        # Simple stable hash for teaching: sum character codes.
        return sum(ord(ch) for ch in key) % len(self.buckets)

    def insert(self, key, value):
        index = self._index(key)
        bucket = self.buckets[index]

        for pair in bucket:
            if pair[0] == key:
                pair[1] = value
                return

        bucket.append([key, value])

    def get(self, key):
        index = self._index(key)
        bucket = self.buckets[index]

        for stored_key, stored_value in bucket:
            if stored_key == key:
                return stored_value

        return None

    def delete(self, key):
        index = self._index(key)
        bucket = self.buckets[index]

        for i, pair in enumerate(bucket):
            if pair[0] == key:
                bucket.pop(i)
                return True

        return False

hm = TinyHashMap()

# These two keys intentionally collide with this simple hash.
hm.insert("ad", "first clue")
hm.insert("bc", "second clue")
hm.insert("mvp", "basketball award")

print("Buckets:", hm.buckets)
print("Lookup ad:", hm.get("ad"))
print("Lookup bc:", hm.get("bc"))
print("Deleted ad?", hm.delete("ad"))
print("Lookup ad after delete:", hm.get("ad"))
```
Collision Check
True or false?
If two keys collide in a hashmap, one of the keys must be discarded.
Complexity Tradeoffs
Why hashmaps feel fast
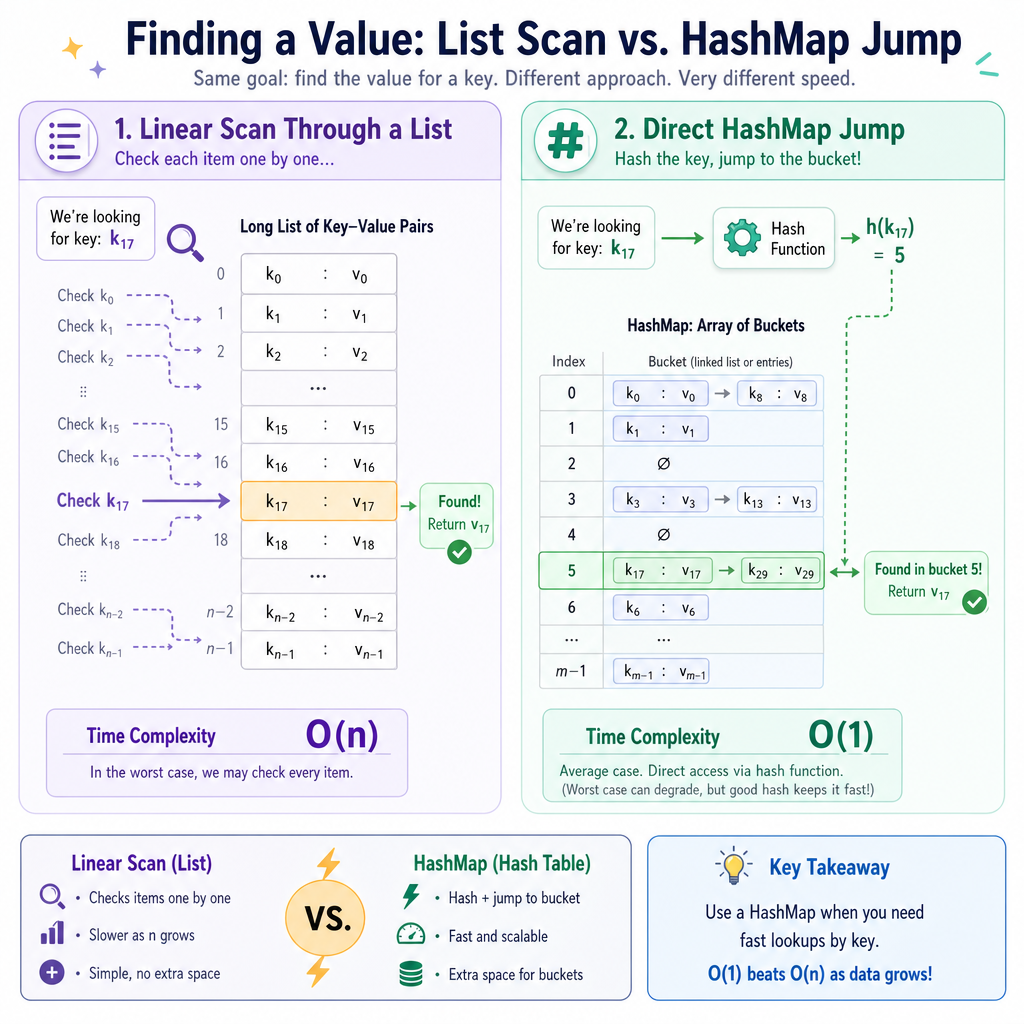
For a well-sized hashmap with a good hash function, common operations are usually:
Operation Average Time InsertO(1)
Retrieve
O(1)
Delete
O(1)
O(1) means the operation does not grow proportionally with the number of stored items. Looking up one detective by case ID should still feel direct even if there are thousands of cases.
But there is a tradeoff:
- Hashmaps use extra memory for buckets.
- Bad collisions can make operations slower.
- In the worst case, operations can degrade toward
O(n).
Python's dict handles resizing and collision management for you, which is why it is one of the most useful tools in everyday Python problem solving.
Average Lookup
Fill in the blank:
The average-case time complexity for retrieving a value from a well-sized hashmap by key is ____.
Hashmap Instincts
Which problem is the strongest signal that a hashmap would be useful?