Incidents SLOs and Runbooks
Read at your own pace. Code execution, quizzes, progress tracking, and the AI tutor are available in the interactive view with JavaScript enabled.
Operate Under Pressure
Now that we've covered Observability 101: Metrics, Logs, and Traces and Logging with the ELK Stack, we can answer a harder production question:
What do we do when the system is visibly unhealthy and users are affected?
That is where incidents, SLOs, and runbooks come in.
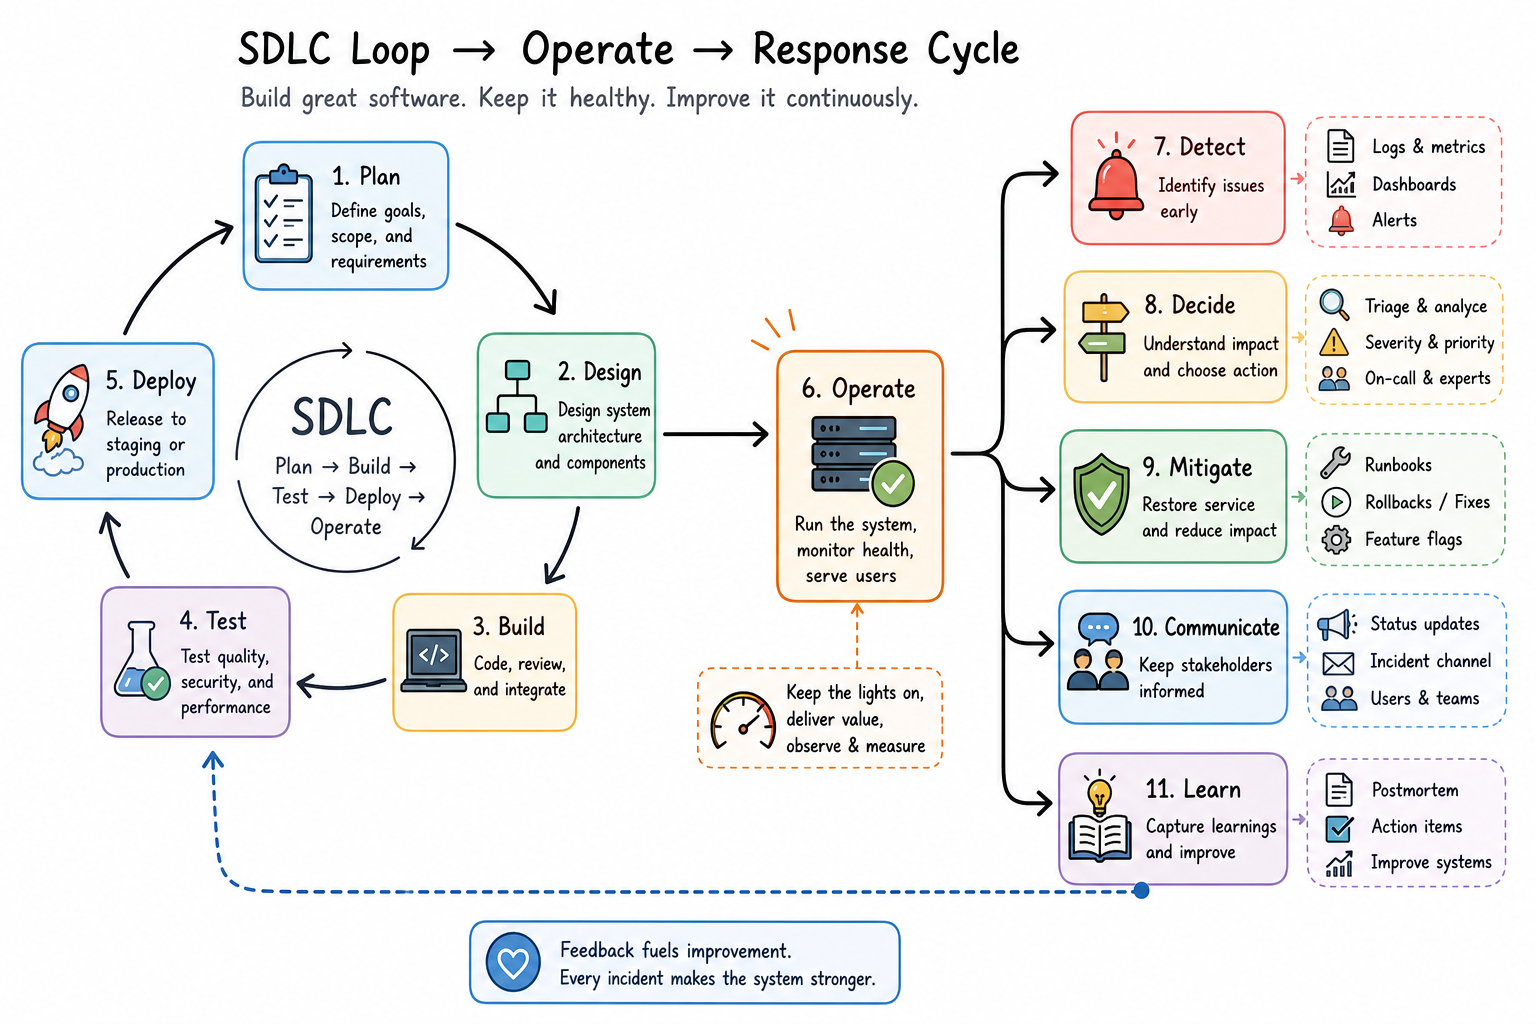
Earlier in the course, the SDLC loop ended with Operate and Feedback. This lesson is the practical operating manual for that final phase:
Detect -> Decide -> Mitigate -> Communicate -> Learn
A strong DevOps team does not pretend incidents will never happen. It designs systems, alerts, and team habits so incidents are noticed quickly, handled calmly, and converted into better engineering work.
CONTINUE WITH ALGODAILY PREMIUM
Keep going with the complete tutorial.
Unlock the remaining explanations and exercises, alongside the full learning library.
Explore Premium →