Introduction to Artificial Intelligence
Read at your own pace. Code execution, quizzes, progress tracking, and the AI tutor are available in the interactive view with JavaScript enabled.
Why AI Now
From data and qubits to intelligent behavior
Now that you've completed Introduction to Data Science and Introduction to Quantum Computing, you're ready to connect two powerful ideas:
- From data science: programs can learn useful patterns from examples.
- From quantum computing: computation can be framed as state, transformation, probability, and measurement.
Artificial Intelligence sits in the practical middle: we build systems that perceive context, make predictions, choose actions, and improve with feedback.
For your background in Angular and .NET, think of AI as another service layer: not just CRUD logic, but a component that can rank, classify, recommend, summarize, detect, or decide.

AI As Decisions
A useful definition
Artificial Intelligence is the engineering of systems that produce behavior we would call intelligent if a human did it.
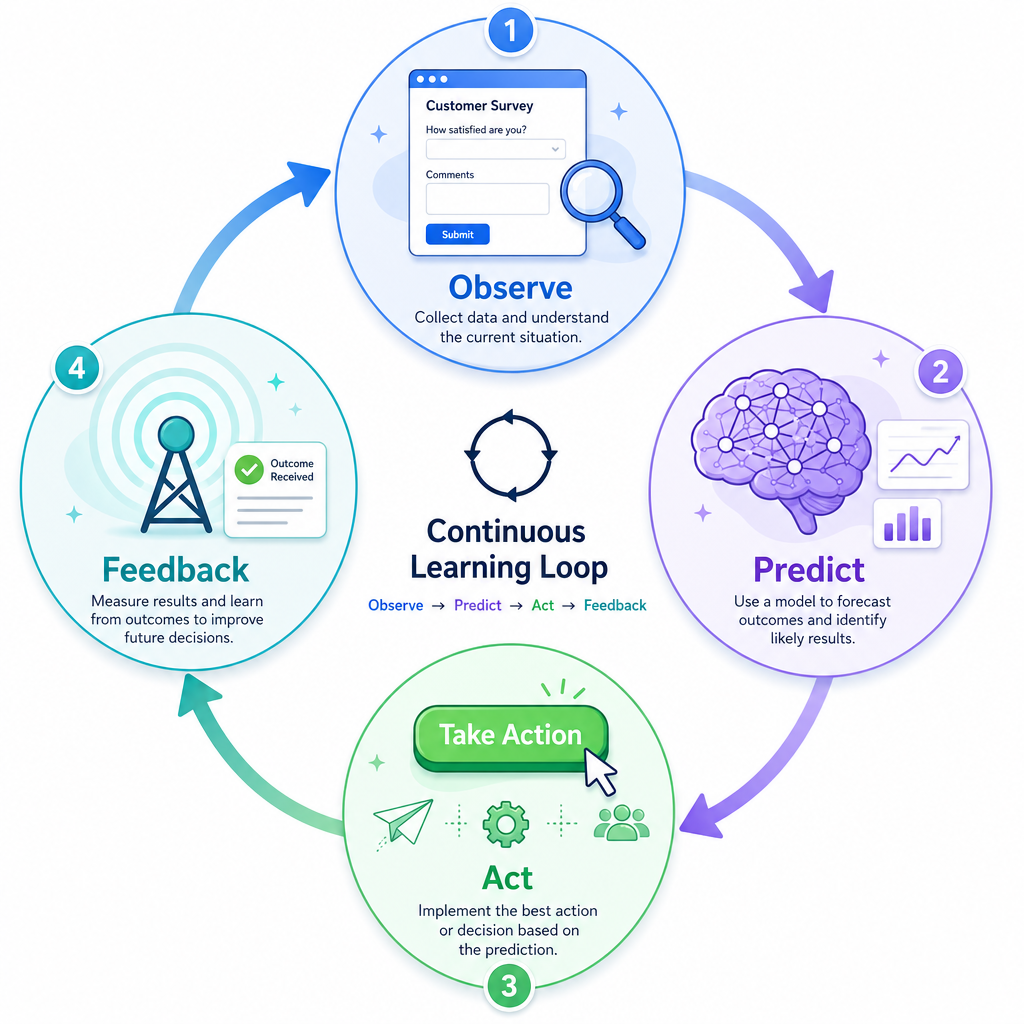
A practical AI system usually follows this loop:
observe context -> infer/predict -> choose action -> receive feedback
Examples:
- A support chatbot reads a question and drafts an answer.
- A fraud detector scores a transaction.
- A recommendation engine ranks products.
- A code assistant predicts the next useful snippet.
The important shift: instead of encoding every rule manually, we often encode a learning process and let data shape the behavior.
Spot The Learning
Which system is the clearest example of supervised learning?
Rules Versus Learning
Two ways to build behavior
As an experienced developer, you already know rule-based systems:
if condition:
    do thing
AI often starts when the rules become too numerous, fuzzy, or context-dependent.
Below, the first classifier uses a hand-written threshold. The second learns a threshold from labeled examples. This is intentionally tiny, but it captures the key difference: the behavior comes from data, not only from the developer's assumptions.
```python
# Rule-based vs learned threshold classifier

# Data: (minutes_on_page, converted)
examples = [
    (1.0, 0),
    (1.5, 0),
    (2.0, 0),
    (3.5, 1),
    (4.0, 1),
    (5.0, 1),
]

# 1) Hand-written rule
def rule_based(minutes):
    return 1 if minutes >= 3.0 else 0

# 2) Learned threshold: try many thresholds and keep the best one
best_threshold = None
best_accuracy = -1

for candidate in [x / 10 for x in range(10, 61)]:
    correct = 0
    for minutes, label in examples:
        prediction = 1 if minutes >= candidate else 0
        correct += prediction == label
    accuracy = correct / len(examples)

    if accuracy > best_accuracy:
        best_accuracy = accuracy
        best_threshold = candidate

print("Rule prediction for 2.8 minutes:", rule_based(2.8))
print("Learned threshold:", best_threshold)
print("Learned accuracy:", best_accuracy)
print("Learned prediction for 2.8 minutes:", 1 if 2.8 >= best_threshold else 0)
```
The Learning Loop
AI is not just a model
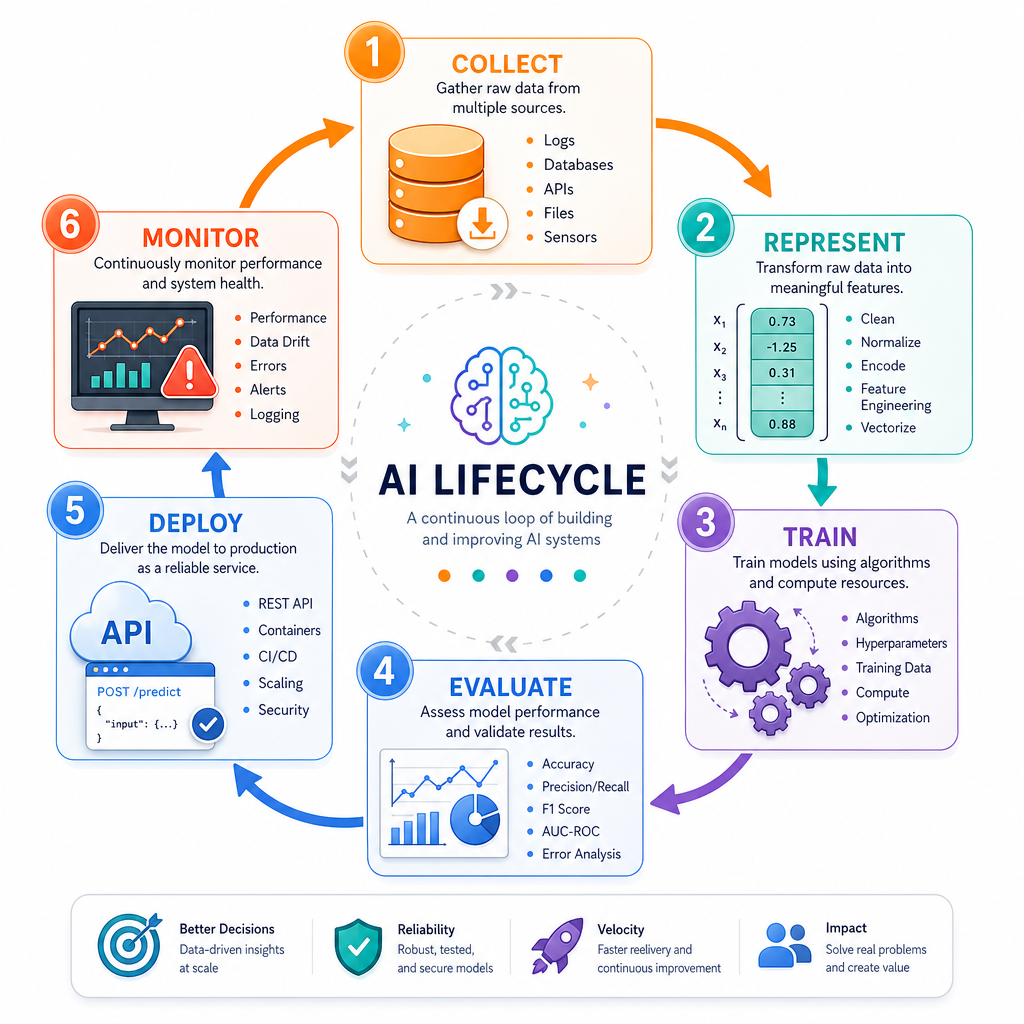
A model is only one part of an AI system. The production loop looks more like this:
- Collect examples from a real task.
- Represent inputs as features, embeddings, tokens, pixels, or structured values.
- Train by adjusting parameters to reduce error.
- Evaluate on data not used for training.
- Deploy behind an API, job, workflow, or UI.
- Monitor for drift, bias, latency, and failure modes.
This should feel familiar from backend engineering: a model is a dependency with behavior, constraints, metrics, and operational risk.
Train Tiny Model
A minimal classifier
Let's train a tiny linear model using pure Python.
Scenario: predict whether a website visitor is likely to engage based on two features:
minutes_on_sitepages_viewed
This is not meant to be production ML. It is meant to reveal the core mechanism: make a prediction, measure error, adjust weights, repeat.
```python
# Tiny perceptron-style classifier in pure Python

training_data = [
    # minutes_on_site, pages_viewed, engaged
    (0.5, 1, 0),
    (1.0, 2, 0),
    (1.5, 1, 0),
    (3.0, 4, 1),
    (4.0, 5, 1),
    (5.0, 6, 1),
]

weights = [0.0, 0.0]
bias = 0.0
learning_rate = 0.1

def predict(minutes, pages):
    score = weights[0] * minutes + weights[1] * pages + bias
    return 1 if score >= 0 else 0

for epoch in range(10):
    mistakes = 0
    for minutes, pages, label in training_data:
        guess = predict(minutes, pages)
        error = label - guess

        if error != 0:
            mistakes += 1
            weights[0] += learning_rate * error * minutes
            weights[1] += learning_rate * error * pages
            bias += learning_rate * error

    print(f"epoch={epoch}, mistakes={mistakes}, weights={weights}, bias={round(bias, 2)}")

print("Prediction for 2.5 minutes and 3 pages:", predict(2.5, 3))
print("Prediction for 0.8 minutes and 1 page:", predict(0.8, 1))
```
Generalization Check
True or false: A model that perfectly memorizes its training examples is always a good AI system.
Neural Network Intuition
Parameters as adjustable behavior
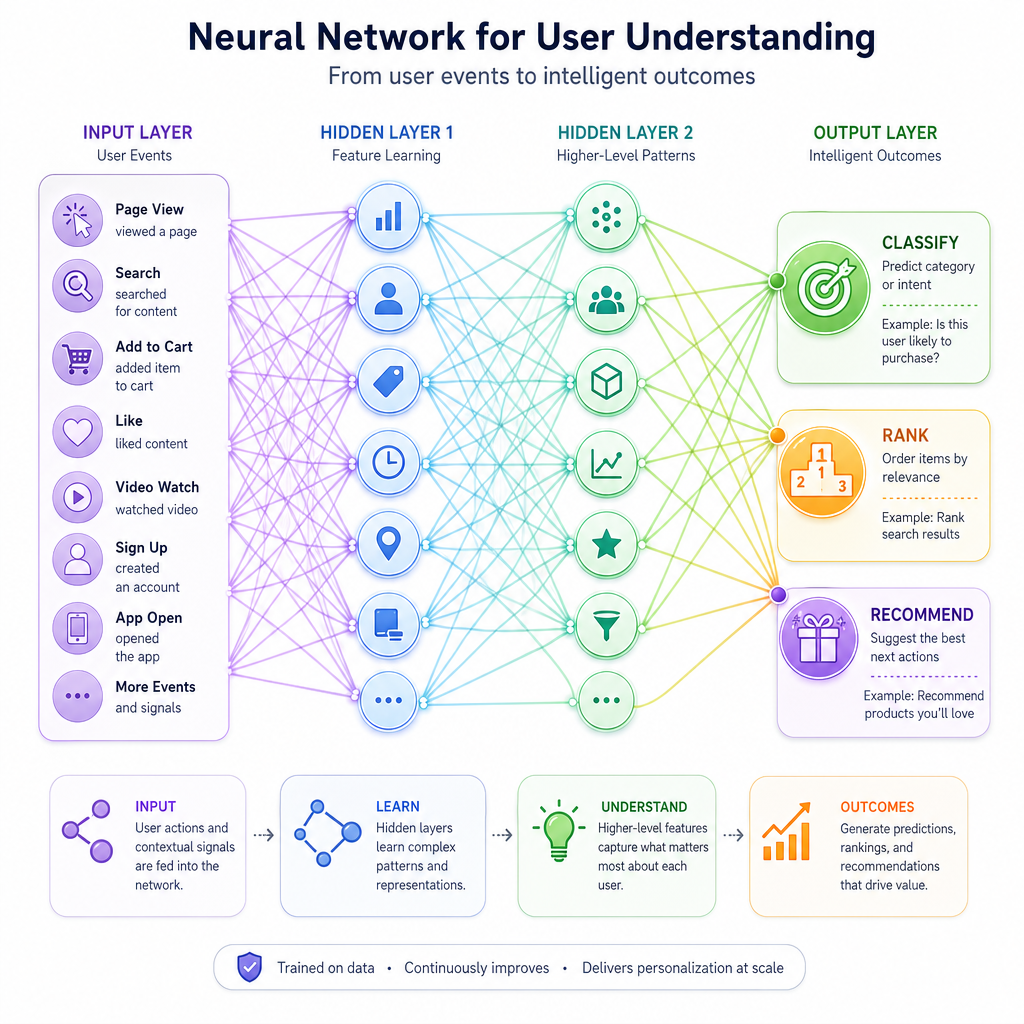
A neural network is a stack of simple mathematical transformations with many adjustable parameters.
You can think of it as:
input features -> layer -> layer -> output prediction
Each layer transforms the representation. Early layers may capture simple patterns; later layers combine them into more task-specific signals.
For images, that might mean edges becoming shapes becoming objects. For text, tokens become contextual meaning. For app behavior, raw events can become user-intent signals.
The essential idea is not magic: training repeatedly nudges parameters so predictions become less wrong on examples.
Name The Target
In supervised learning, the known answer attached to a training example is called the ______.
Responsible AI
Engineering judgment matters
AI systems can fail in ways ordinary software does not:
- A model may work for one user group and fail for another.
- Data can drift after deployment.
- Training examples may encode historical bias.
- Confident predictions can still be wrong.
- Latency, cost, and explainability may constrain design.
So responsible AI engineering means measuring more than average accuracy. You also inspect subgroup behavior, edge cases, and real-world impact.
Next, in Introduction to Website Development, we'll shift from intelligent behavior to how web experiences are structured and delivered.
```python
# Simple subgroup accuracy audit

predictions = [
    # group, predicted, actual
    ("new_users", 1, 1),
    ("new_users", 1, 0),
    ("new_users", 0, 0),
    ("returning_users", 1, 1),
    ("returning_users", 0, 1),
    ("returning_users", 1, 1),
]

stats = {}
for group, predicted, actual in predictions:
    if group not in stats:
        stats[group] = {"correct": 0, "total": 0}
    stats[group]["correct"] += predicted == actual
    stats[group]["total"] += 1

for group, values in stats.items():
    accuracy = values["correct"] / values["total"]
    print(f"{group}: accuracy={accuracy:.2f} ({values['correct']}/{values['total']})")
```