Tokenization and Embeddings
Read at your own pace. Code execution, quizzes, progress tracking, and the AI tutor are available in the interactive view with JavaScript enabled.
Why This Matters
Tokenization and Embeddings
Now that we've covered how LLMs learn statistical patterns in How Do Large Language Models Work?, we are ready to zoom into the first critical step:
How does raw text become something a neural network can process?
Neural networks do not understand strings like "machine learning is useful". They operate on tensors: arrays of numbers with known shapes and dtypes, just like we saw in Practical Introduction to TensorFlow.
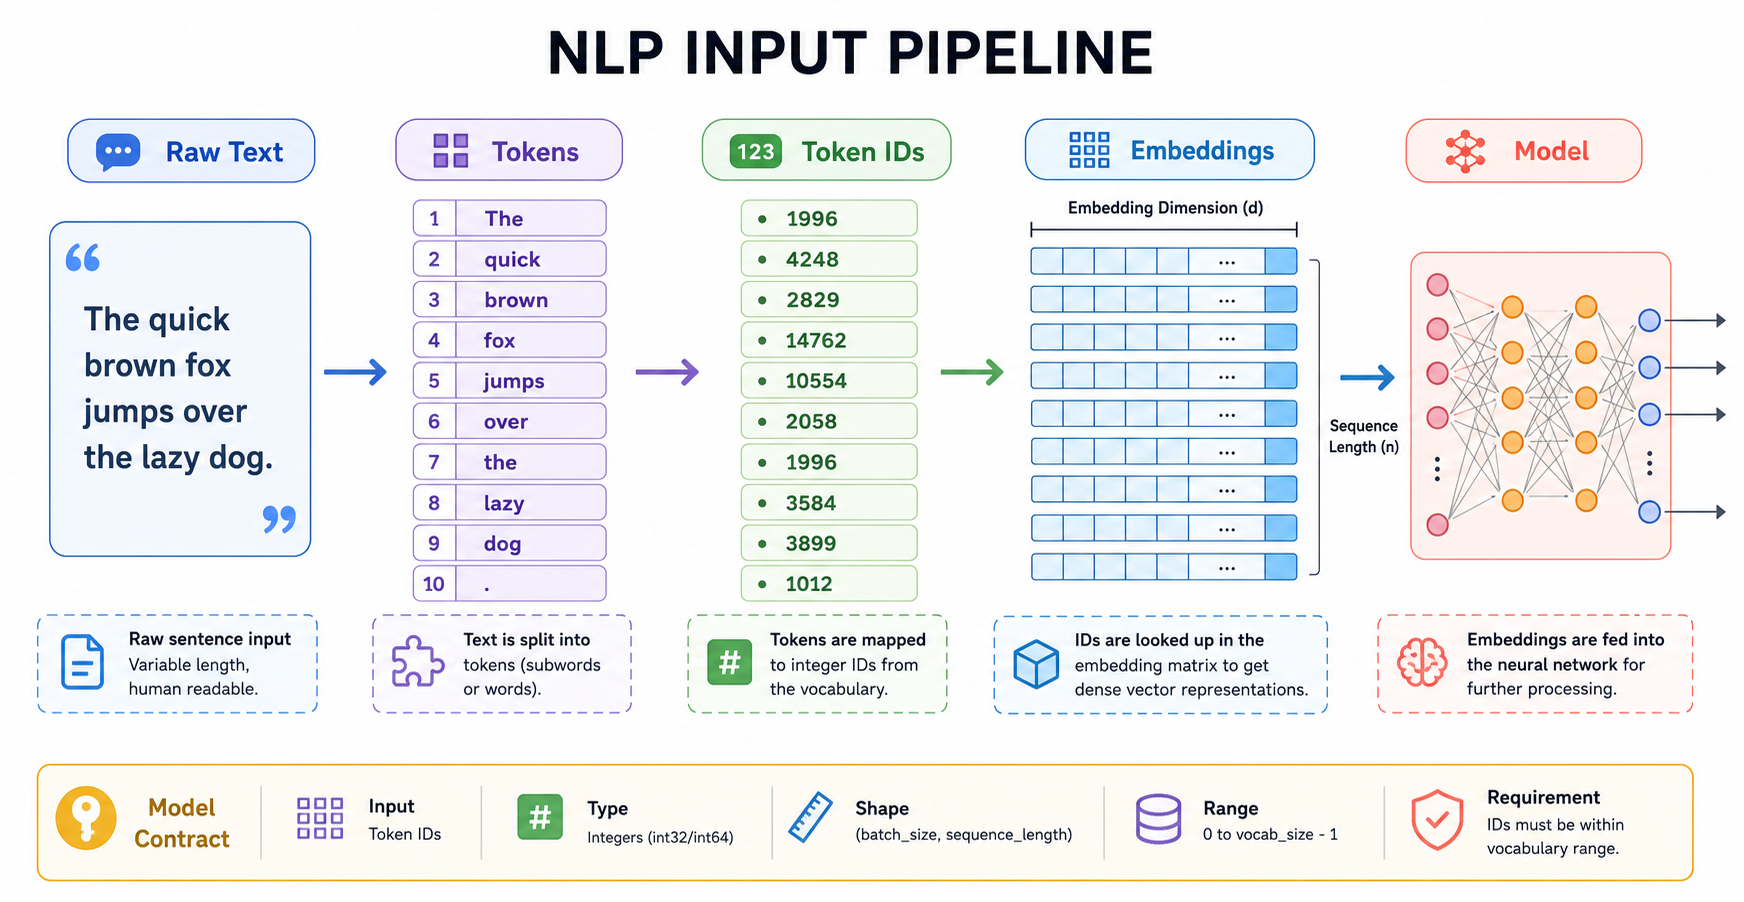
The language-model input pipeline is usually:
raw text → tokens → token IDs → embeddings → neural network
This lesson focuses on the middle of that pipeline. For a software engineer, think of tokenization as parsing and encoding, and embeddings as the typed data structure the model actually consumes.
CONTINUE WITH ALGODAILY PREMIUM
Keep going with the complete tutorial.
Unlock the remaining explanations and exercises, alongside the full learning library.
Explore Premium →