Refining your Relational Database System
Read at your own pace. Code execution, quizzes, progress tracking, and the AI tutor are available in the interactive view with JavaScript enabled.
From Tables To Guarantees
Why this lesson matters
In Building a Relational Database System, we built the core relational pieces: tables, normal forms, relational algebra, a nested-loop join, and a tiny SQL-like surface.
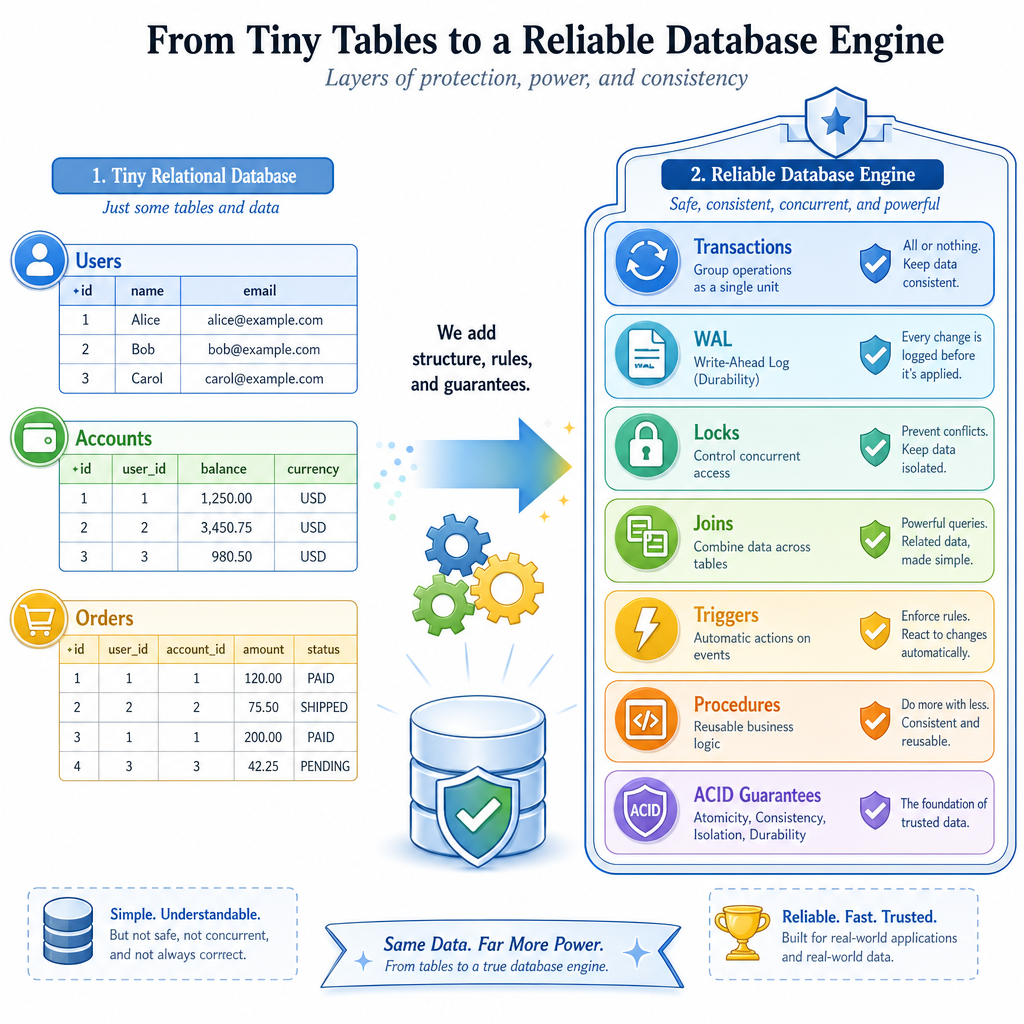
Now we move from “can answer table queries” to “can safely run real applications.” A relational database becomes valuable when it can handle:
- multi-step changes that succeed or fail together
- concurrent users without corrupted data
- joins that scale beyond toy examples
- logic that runs close to the data
- the ACID contract we introduced back in Data Store Fundamentals
Think of a finance app: transferring money, recording trades, and updating balances are not just table operations. They are promises.
Atomic Transactions
All-or-nothing changes
A transaction groups several operations into one logical unit.
For our tiny relational system, the simplest useful transaction model is copy-on-write:
-
begin()creates a working copy of tables. - writes modify only the working copy.
-
commit()replaces the real tables. -
rollback()discards the working copy.
This is not how PostgreSQL fully works internally, but it gives us the right mental model: users should never see a half-finished money transfer.
```python
from copy import deepcopy

class TinyRelDB:
    def __init__(self):
        self.tables = {
            'accounts': [
                {'id': 1, 'owner': 'Ada', 'balance': 100},
                {'id': 2, 'owner': 'Linus', 'balance': 50},
            ]
        }
        self._tx_tables = None

    def begin(self):
        if self._tx_tables is not None:
            raise RuntimeError('transaction already open')
        self._tx_tables = deepcopy(self.tables)

    def active_tables(self):
        return self._tx_tables if self._tx_tables is not None else self.tables

    def update_balance(self, account_id, delta):
        for row in self.active_tables()['accounts']:
            if row['id'] == account_id:
                row['balance'] += delta
                return
        raise KeyError(account_id)

    def commit(self):
        if self._tx_tables is None:
            raise RuntimeError('no transaction')
        self.tables = self._tx_tables
        self._tx_tables = None

    def rollback(self):
        self._tx_tables = None

    def balances(self):
        return [(r['owner'], r['balance']) for r in self.tables['accounts']]


db = TinyRelDB()
print('start:', db.balances())

try:
    db.begin()
    db.update_balance(1, -30)
    raise ValueError('network failure before crediting Linus')
    db.update_balance(2, 30)
    db.commit()
except Exception as e:
    print('error:', e)
    db.rollback()

print('after rollback:', db.balances())

db.begin()
db.update_balance(1, -30)
db.update_balance(2, 30)
db.commit()
print('after commit:', db.balances())
```
Transaction Boundary
A transaction transfers $25 from account A to account B. The debit from A succeeds, then the process crashes before crediting B.
What should a relational database with atomic transactions guarantee?
Durability With WAL
Write-ahead logging
Copy-on-write helps atomicity while the process is alive. But what if the machine crashes?
A classic durability pattern is WAL: write-ahead logging.
Rule: before changing table data, append an intent record to a durable log.
On restart, the database can replay committed operations. This is the same spirit as the durability discussion from Data Store Fundamentals, now applied to our relational layer.
```python
import json
import os
import tempfile

class WALDatabase:
    def __init__(self, log_path):
        self.log_path = log_path
        self.tables = {'accounts': {1: 100, 2: 50}}
        self.recover()

    def append_log(self, record):
        with open(self.log_path, 'a') as f:
            f.write(json.dumps(record) + '\n')
            f.flush()
            os.fsync(f.fileno())

    def transfer(self, from_id, to_id, amount):
        record = {'op': 'transfer', 'from': from_id, 'to': to_id, 'amount': amount}
        self.append_log(record)      # log first
        self.apply(record)           # then mutate memory

    def apply(self, record):
        if record['op'] == 'transfer':
            self.tables['accounts'][record['from']] -= record['amount']
            self.tables['accounts'][record['to']] += record['amount']

    def recover(self):
        if not os.path.exists(self.log_path):
            return
        with open(self.log_path) as f:
            for line in f:
                self.apply(json.loads(line))


with tempfile.TemporaryDirectory() as d:
    path = os.path.join(d, 'wal.log')

    db = WALDatabase(path)
    db.transfer(1, 2, 30)
    print('before crash:', db.tables)

    recovered = WALDatabase(path)
    print('after recovery:', recovered.tables)
```
Isolation By Locks
Concurrent transactions need rules
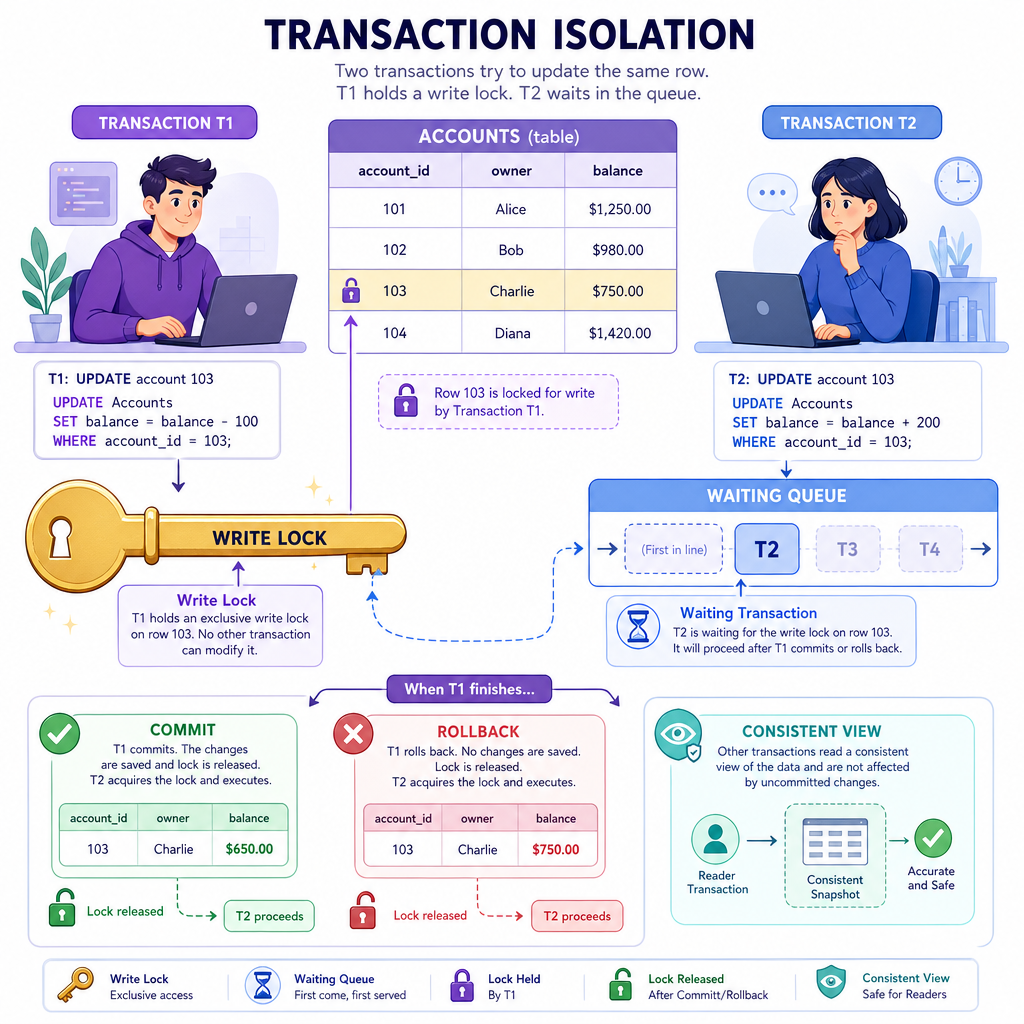
If two users update the same rows at the same time, atomicity alone is not enough. We also need isolation: each transaction should behave as if it has a coherent view of the database.
A tiny implementation can start with table-level locks:
- a transaction must acquire a write lock before changing a table
- only one writer can hold the lock at a time
- the lock is released on commit or rollback
This is coarse-grained, but it teaches the real tradeoff: stronger isolation usually reduces concurrency.
Common isolation levels, from weaker to stronger:
Level Rough meaning Read committed only read committed data Repeatable read repeated reads see stable rows Serializable result is equivalent to one-at-a-time executionReal systems often combine locks, multi-version concurrency control, timestamps, and conflict detection. Our scratch version can begin with locks because they make the contract visible.
Serializable Reality
True or false: Serializable isolation means the database must literally run every transaction one at a time with no overlap.
Better Joins
Beyond nested loops
In Building a Relational Database System, we implemented a nested-loop join. It is simple and correct, but it compares many row pairs.
A common upgrade is a hash join:
- Build a hash map from the smaller table using the join key.
- Scan the larger table.
- For each row, look up matching rows in the hash map.
This is the same idea you used for indexes in Enhancing your Document-Oriented Database: spend memory to avoid repeated scanning.
```python
users = [
    {'id': 1, 'name': 'Ada'},
    {'id': 2, 'name': 'Linus'},
    {'id': 3, 'name': 'Grace'},
]

orders = [
    {'id': 101, 'user_id': 1, 'total': 42},
    {'id': 102, 'user_id': 1, 'total': 99},
    {'id': 103, 'user_id': 3, 'total': 15},
]

def hash_join(left, right, left_key, right_key):
    index = {}
    for row in right:
        index.setdefault(row[right_key], []).append(row)

    joined = []
    for lrow in left:
        for rrow in index.get(lrow[left_key], []):
            joined.append({**lrow, **rrow})
    return joined

result = hash_join(orders, users, 'user_id', 'id')
for row in result:
    print(f"order={row['id']} customer={row['name']} total={row['total']}")
```
Triggers And Procedures
Logic near the data
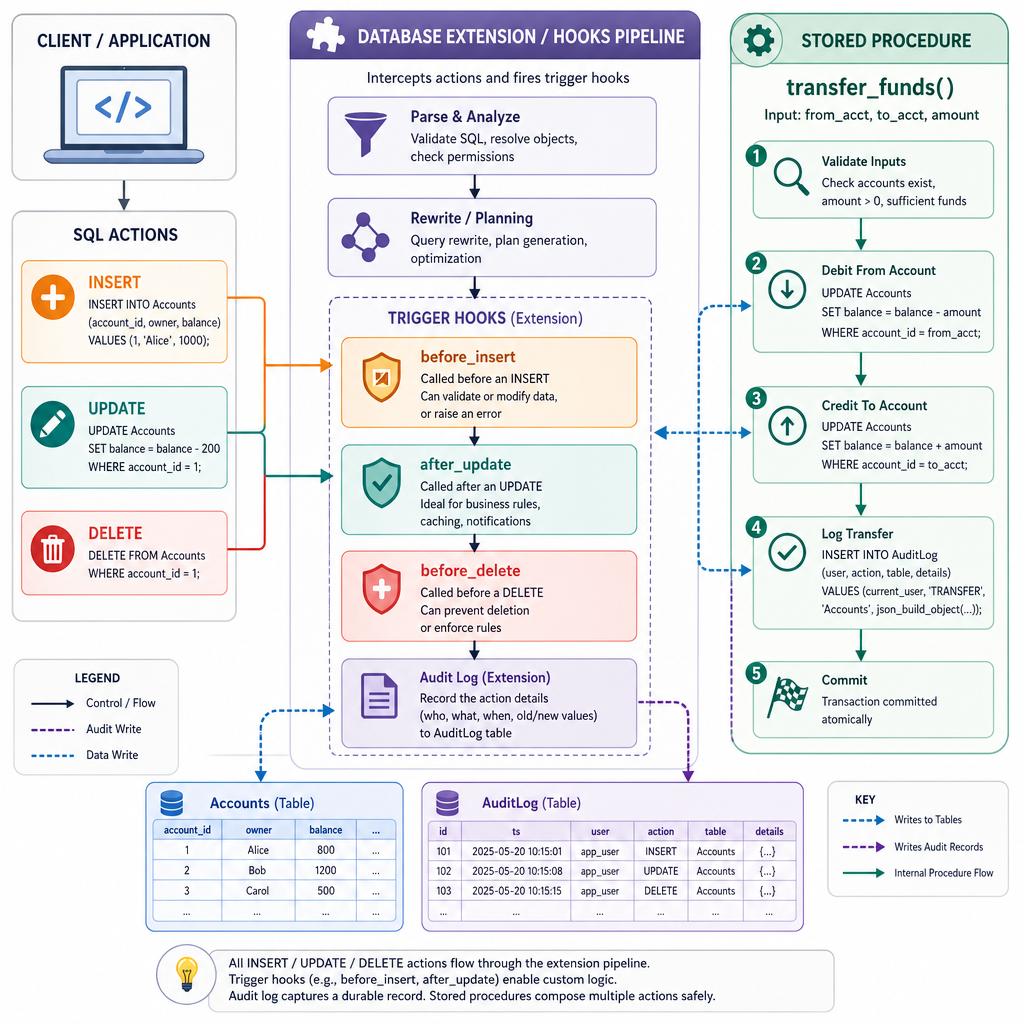
Relational databases often support two powerful extension points:
Triggers
A trigger runs automatically when an event happens, such as before_insert, after_update, or before_delete.
Use cases:
- validate an invariant before insert
- write an audit log after update
- maintain a derived summary table
Stored procedures
A stored procedure is a named routine executed by the database engine.
Use cases:
- perform a business operation consistently
- reduce round trips between app and database
- centralize rules like
transfer_funds(from_id, to_id, amount)
In a scratch database, you can model both as Python callables registered with the engine. The important design question is: when does this logic run relative to the transaction? Usually, it should participate in the same transaction so rollback undoes both data changes and side effects recorded inside the database.
Name The Property
The ACID property that prevents concurrent transactions from observing or interfering with each other’s half-finished work is called ____.
ACID In One Engine
The refined relational engine
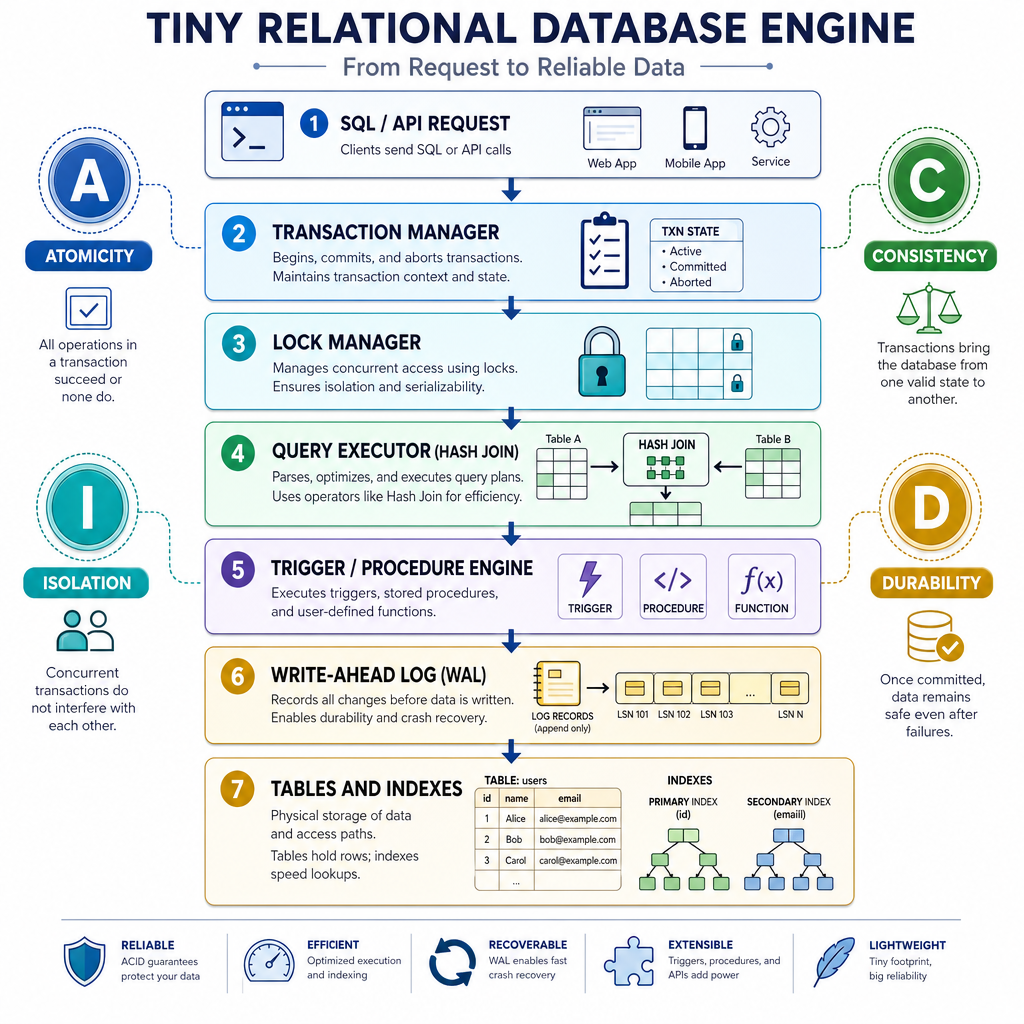
By layering these pieces onto the table engine from the previous lesson, we get a much more realistic relational database:
- Atomicity: transactions commit or roll back as units
- Consistency: constraints, triggers, and procedures preserve valid states
- Isolation: locks or stronger concurrency control protect active transactions
- Durability: WAL lets committed work survive crashes
A useful mental model:
SQL/API request
   ↓
transaction manager
   ↓
lock manager + constraint checks
   ↓
join/query execution
   ↓
write-ahead log
   ↓
tables + indexes
This is still a primitive PostgreSQL-like system, but it now has the core shape of a real relational datastore. Next, we will shift data models again and look at how search engines organize text for fast retrieval.