Introducing Search Engine
Read at your own pace. Code execution, quizzes, progress tracking, and the AI tutor are available in the interactive view with JavaScript enabled.
From Databases To Search
Why this lesson matters
In Enhancing your Document-Oriented Database, you added field indexes so queries like status == "open" could avoid scanning every document.
Now we shift to a different datastore contract: a search engine. Instead of asking for exact matches, users ask for relevance:
- “python finance risk models”
- “transaction log durability”
- “redis cache eviction”
A search engine must answer: Which documents are most likely useful for this text query?
In this lesson, we’ll build the core of an Elasticsearch-like system:
- Break documents into searchable tokens
- Store an inverted index
- Execute full-text queries
- Add simple ranking
- Wrap the pieces into a tiny Python search engine
Next lesson, we’ll refine this with more advanced search-engine behavior.
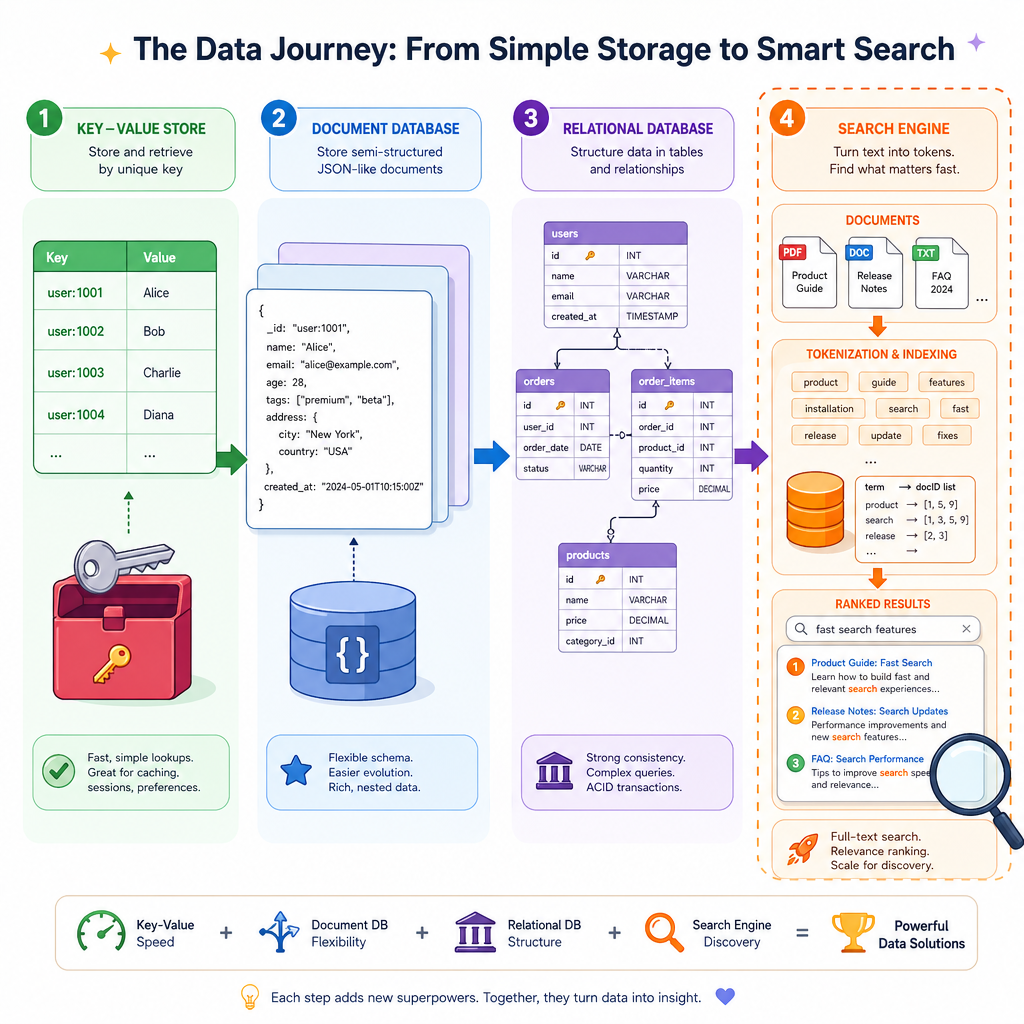
The Inverted Index
Flip the lookup direction
A normal document store often starts with this shape:
doc_id -> document
A search engine adds another structure:
term -> doc_ids containing that term
That second structure is an inverted index.
Example documents:
1: "Python powers finance tools"
2: "Finance teams search transaction logs"
3: "Python search engines use indexes"
Inverted index:
python  -> {1, 3}
finance -> {1, 2}
search  -> {2, 3}
indexes -> {3}
So a query like python finance can jump directly to candidate documents instead of scanning everything.
This is the same broad idea as the field index you built earlier, but the indexed values are extracted from free text rather than stored as neat fields.
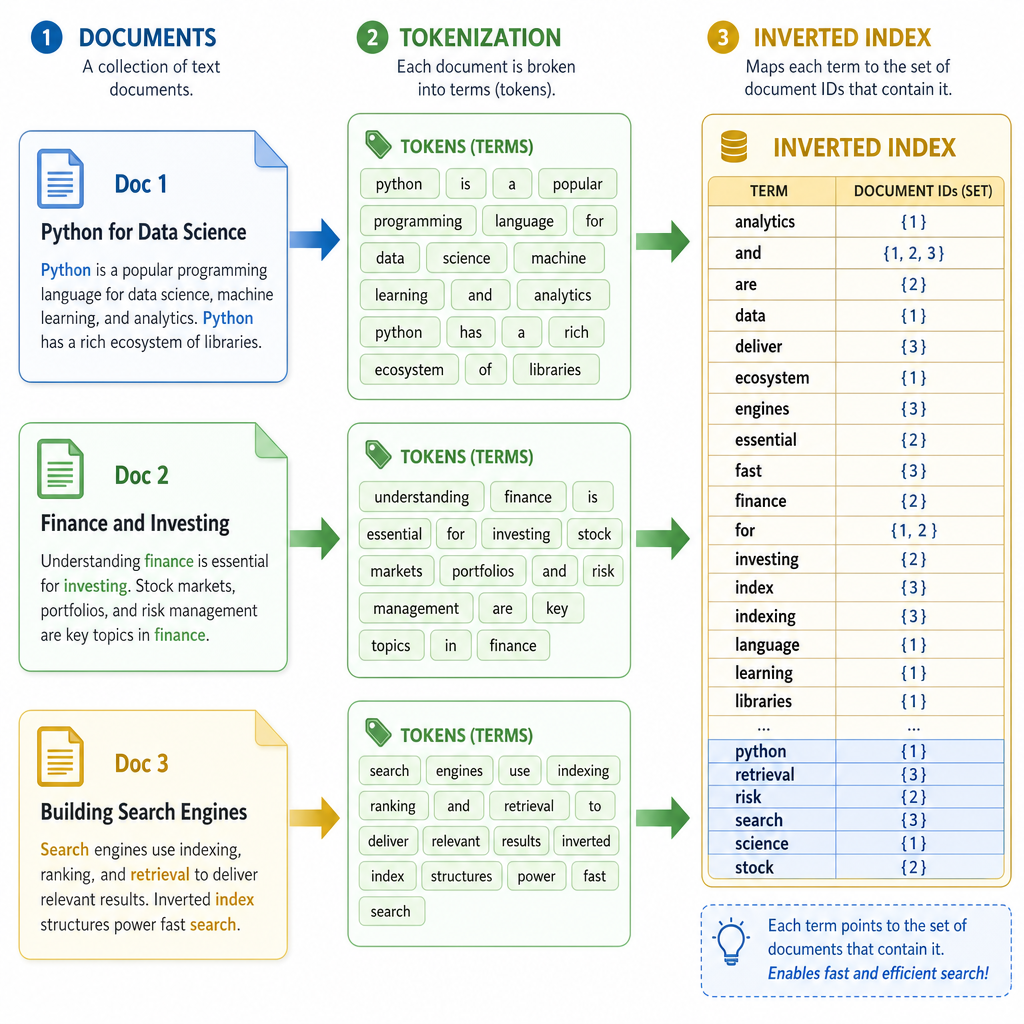
Tokenization Pipeline
Text must become terms
Before we can index text, we need an analysis pipeline.
For a tiny search engine, that usually means:
- Lowercase the text
- Extract word-like chunks
- Remove common stop words
- Normalize related words with simple stemming
Real search engines have sophisticated analyzers for language, punctuation, Unicode, synonyms, and domain-specific vocabulary. We’ll keep ours intentionally small so the mechanics stay visible.
```python
import re

STOP_WORDS = {"the", "a", "an", "and", "or", "of", "to", "in", "for"}


def simple_stem(token):
    # Very small demo stemmer, not production-grade.
    for suffix in ("ing", "ed", "s"):
        if token.endswith(suffix) and len(token) > len(suffix) + 2:
            return token[:-len(suffix)]
    return token


def analyze(text):
    raw_tokens = re.findall(r"[a-z0-9]+", text.lower())
    return [simple_stem(t) for t in raw_tokens if t not in STOP_WORDS]

examples = [
    "Python powers financial searching tools!",
    "The traders searched transaction logs.",
]

for text in examples:
    print(text, "->", analyze(text))
```
Index Direction Check
A search engine stores an inverted index primarily so it can:
Build The Index
From tokens to postings
The list of document IDs for a term is called a posting list.
For now, our posting list will just be a set of document IDs:
term -> {doc_id, doc_id, ...}
Later, search engines often store richer postings:
- term frequency
- token positions
- field names
- offsets for highlighting
But a set is enough to support basic full-text matching.
```python
import re
from collections import defaultdict

STOP_WORDS = {"the", "a", "an", "and", "or", "of", "to", "in", "for"}


def analyze(text):
    tokens = re.findall(r"[a-z0-9]+", text.lower())
    return [t for t in tokens if t not in STOP_WORDS]


def build_index(documents):
    index = defaultdict(set)
    for doc_id, text in documents.items():
        for term in analyze(text):
            index[term].add(doc_id)
    return index


def search_all_terms(index, query):
    terms = analyze(query)
    if not terms:
        return []

    posting_lists = [index.get(term, set()) for term in terms]
    matches = set.intersection(*posting_lists) if posting_lists else set()
    return sorted(matches)


docs = {
    1: "Python powers finance analytics",
    2: "Finance teams search transaction logs",
    3: "Python search engines use inverted indexes",
    4: "Cache systems expire keys quickly",
}

idx = build_index(docs)

for term in ["python", "finance", "search"]:
    print(term, "->", sorted(idx[term]))

print("query: python search ->", search_all_terms(idx, "python search"))
```
Posting Lists
True or false: if a query has two terms and we want documents containing both terms, we can intersect the two posting lists.
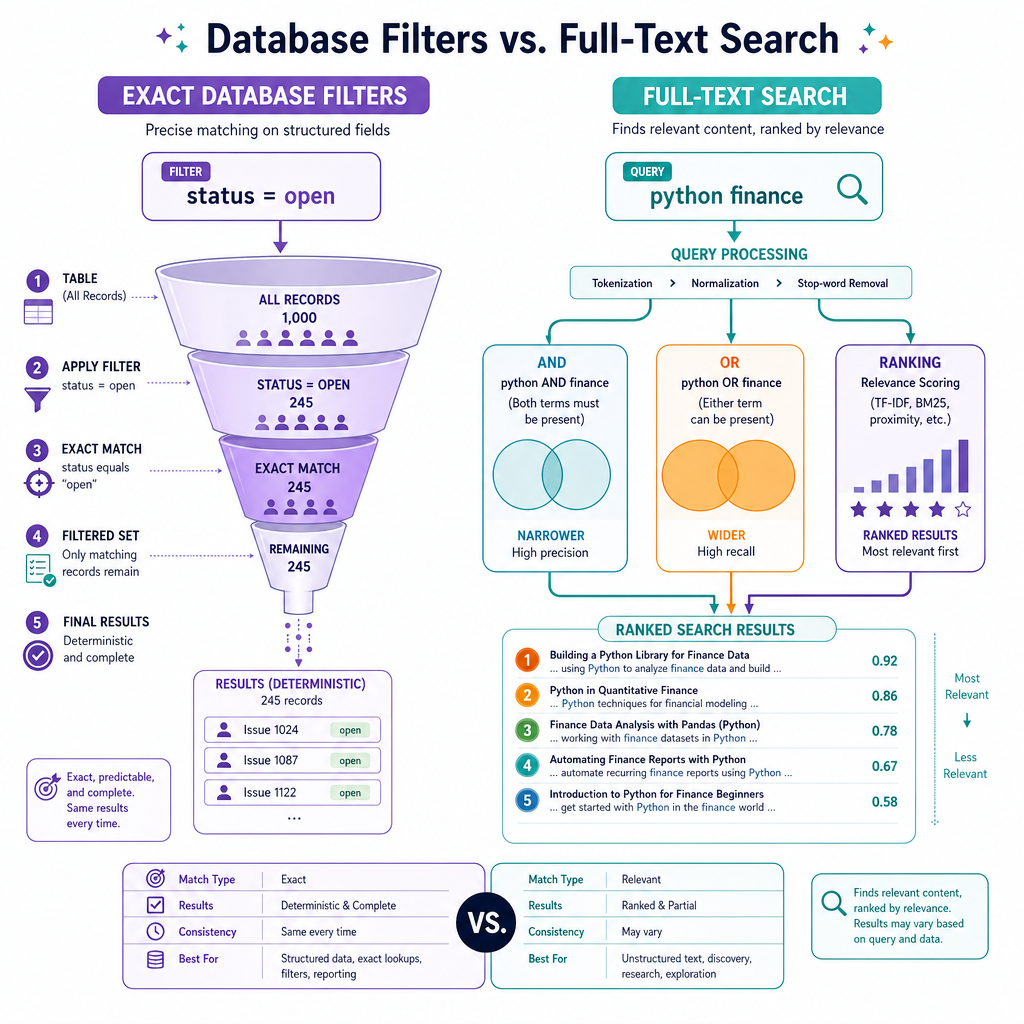
Full Text Semantics
Search is not just equality
A field index from the document database lesson works well for exact predicates:
status == "open"
account_id == 42
Full-text search is fuzzier. A query like:
python finance search
might reasonably return documents that contain:
- all three terms
- two of the terms
- related stemmed forms
- terms in a useful field like
title
For this first version, we’ll keep query semantics simple:
- AND search: return documents containing every query term
- OR search: return documents containing at least one query term
- Ranking: sort likely-better matches first
This is where search begins to feel different from the datastores we’ve built so far: correctness is no longer only “does it match?” but also “how relevant is it?”
Ranking Results
Not every match is equal
If ten documents match python finance, which should appear first?
A useful first ranking idea is TF-IDF:
- TF, term frequency: a term that appears more often in a document may matter more
- IDF, inverse document frequency: a rare term is usually more informative than a common term
Intuition:
score(doc, query) = sum(tf(term in doc) * idf(term))
A rare term like wal or arbitrage often carries more meaning than a common term like system.
Modern engines use more advanced ranking formulas, but TF-IDF is a great first step because it connects directly to the inverted index.
```python
import math
import re
from collections import Counter, defaultdict


def analyze(text):
    return re.findall(r"[a-z0-9]+", text.lower())


docs = {
    1: "python finance finance risk",
    2: "python web search engine",
    3: "finance risk model portfolio",
    4: "python python data tools",
}

# Store per-document term frequencies.
doc_terms = {doc_id: Counter(analyze(text)) for doc_id, text in docs.items()}

# Store document frequency per term.
df = defaultdict(int)
for counts in doc_terms.values():
    for term in counts:
        df[term] += 1

N = len(docs)


def idf(term):
    return math.log((N + 1) / (df.get(term, 0) + 1)) + 1


def score(doc_id, query):
    query_terms = analyze(query)
    counts = doc_terms[doc_id]
    return sum(counts[term] * idf(term) for term in query_terms)

query = "python finance"
ranked = sorted(
    ((doc_id, score(doc_id, query)) for doc_id in docs),
    key=lambda pair: pair[1],
    reverse=True,
)

for doc_id, s in ranked:
    print(f"doc {doc_id}: score={s:.3f} text={docs[doc_id]!r}")
```
Name The Structure
Fill in the blank: the structure that maps a term to the documents containing that term is called an ________.
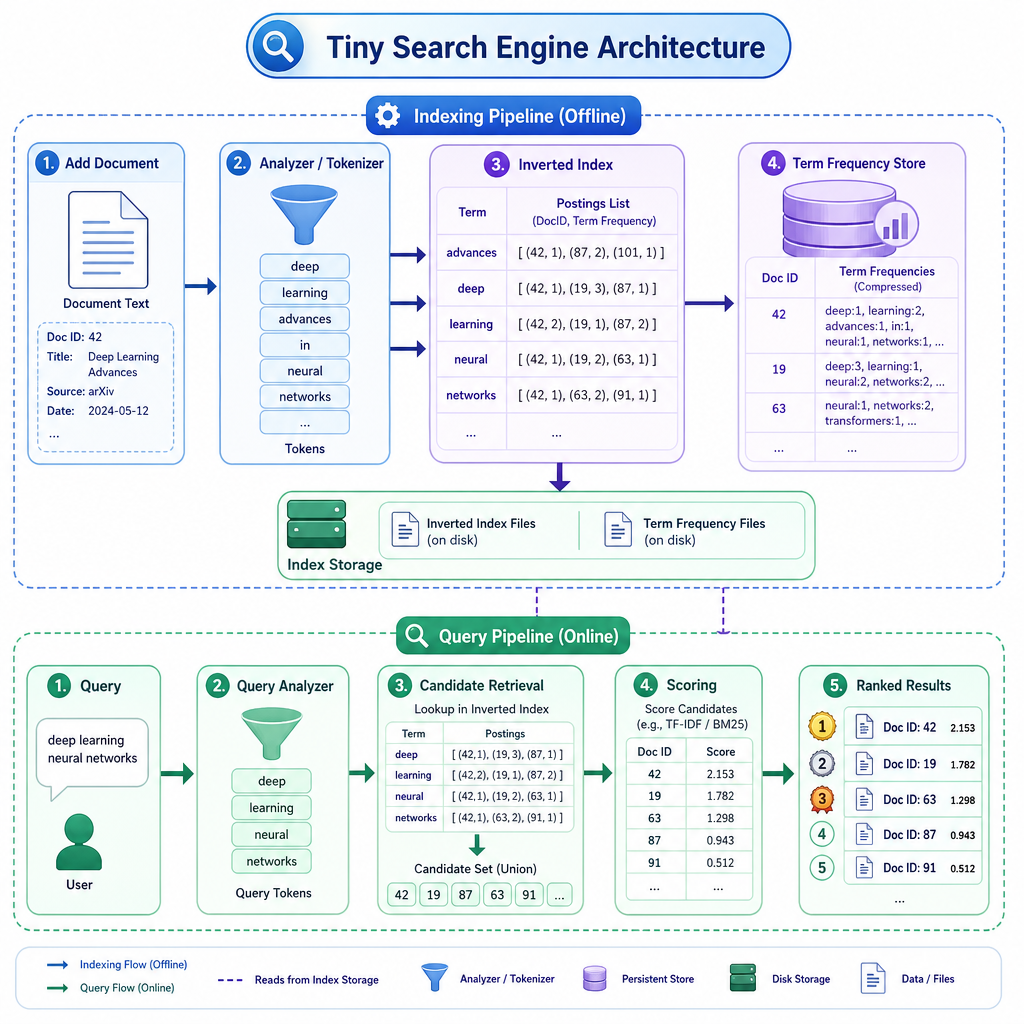
Tiny Search Engine
Wrap it like a datastore
Just like our earlier systems, we can expose a small datastore-like API.
A minimal search engine needs:
-
add(doc_id, text)to store and index a document -
search(query)to analyze the query and rank candidate documents - internal structures for documents, postings, and term frequencies
This is not Elasticsearch yet. But the shape is now recognizable: documents go in, text is analyzed, an inverted index is updated, and queries return ranked hits.
```python
import math
import re
from collections import Counter, defaultdict


class TinySearchEngine:
    def __init__(self):
        self.documents = {}
        self.inverted = defaultdict(set)
        self.term_counts = {}

    def analyze(self, text):
        return re.findall(r"[a-z0-9]+", text.lower())

    def add(self, doc_id, text):
        # Replace existing document in the simplest possible way.
        if doc_id in self.documents:
            old_terms = self.term_counts[doc_id]
            for term in old_terms:
                self.inverted[term].discard(doc_id)

        self.documents[doc_id] = text
        counts = Counter(self.analyze(text))
        self.term_counts[doc_id] = counts

        for term in counts:
            self.inverted[term].add(doc_id)

    def idf(self, term):
        n_docs = len(self.documents)
        doc_freq = len(self.inverted.get(term, set()))
        return math.log((n_docs + 1) / (doc_freq + 1)) + 1

    def search(self, query, limit=5):
        terms = self.analyze(query)
        if not terms:
            return []

        candidates = set()
        for term in terms:
            candidates |= self.inverted.get(term, set())

        scored = []
        for doc_id in candidates:
            counts = self.term_counts[doc_id]
            score = sum(counts[t] * self.idf(t) for t in terms)
            scored.append((score, doc_id, self.documents[doc_id]))

        scored.sort(reverse=True)
        return scored[:limit]


engine = TinySearchEngine()
engine.add(1, "Python search engine with inverted indexes")
engine.add(2, "Finance analytics with Python and risk models")
engine.add(3, "Transaction logs and durability in database systems")
engine.add(4, "Search transaction logs for finance investigations")

for score, doc_id, text in engine.search("python finance search"):
    print(f"{score:.3f} | doc {doc_id} | {text}")
```