How Does TensorFlow Work?
Read at your own pace. Code execution, quizzes, progress tracking, and the AI tutor are available in the interactive view with JavaScript enabled.
A Story to Start: From “Do Math” to “Build a Machine”
A Story to Start: From “Do Math” to “Build a Machine”
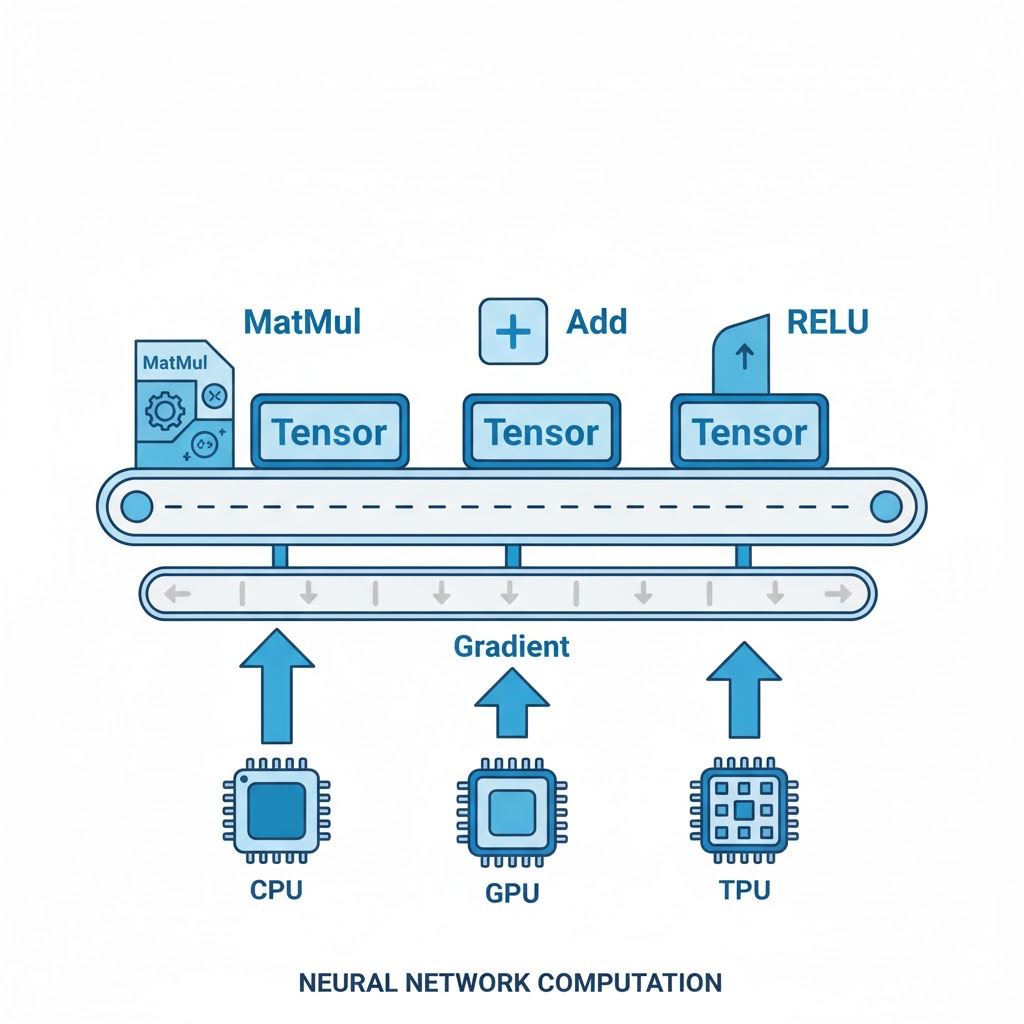
Imagine you’re teaching a robot to recognize cats. You don’t write rules like “if pointy ears then cat.” Instead, you build a machine that learns rules from data. Under the hood, that machine is a stack of layers wired into a computational graph. TensorFlow is the toolkit that builds the graph, runs it efficiently on CPUs/GPUs/TPUs, and optimizes the machine using gradients.
TensorFlow = Tensors (multi-dimensional arrays) + Flow (they flow through operations) + Autodiff (automatic differentiation) + Execution engines (graph runtime).
The Big Picture: What TensorFlow Does
The Big Picture: What TensorFlow Does
- Represents computations as a
graphofopsconnected bytensors. - Uses
automatic differentiationto computegradientsof alosswith respect tovariables. - Executes efficiently on different
devices(CPU/GPU/TPU), scheduling and batching work. - Provides
optimizers(e.g.,SGD,Adam) to update model parameters.
The magic: You describe the forward pass (how outputs are computed). TensorFlow builds enough metadata to compute the backward pass (gradients) automatically.
Tensors: The Things That Flow
Tensors: The Things That Flow
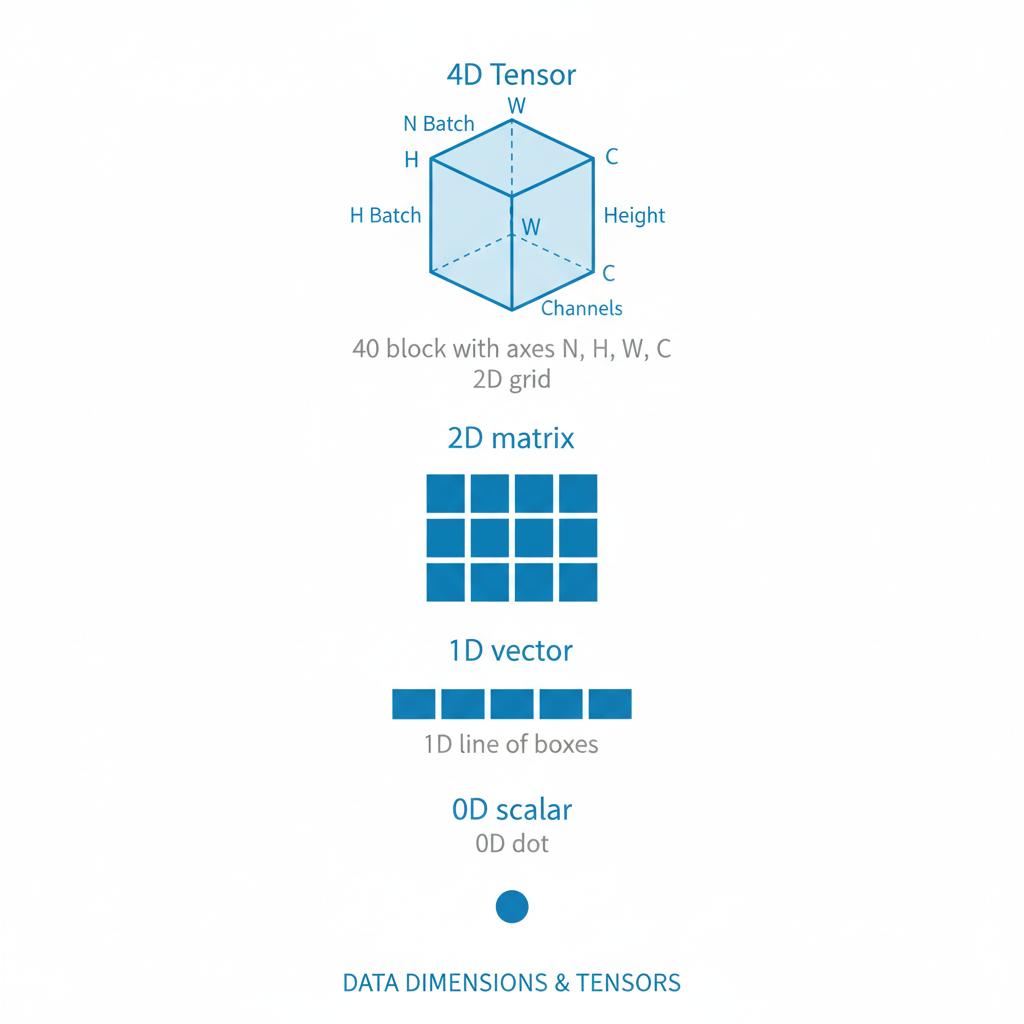
A tensor is a container for numbers with a shape (like [batch, height, width, channels] for images).
-
rank: number of dimensions (scalar=0D, vector=1D, matrix=2D, etc.). -
dtype: numeric type (float32,int32, …).
Mental model: a tensor is a spreadsheet that can have many tabs (dimensions). Ops know how to broadcast and combine them.
Graphs and Ops: Blueprint vs. Execution
Graphs and Ops: Blueprint vs. Execution
A computational graph is a directed acyclic graph (DAG) where nodes are ops (like MatMul, Add, Conv2D) and edges carry tensors. In TensorFlow 2, you usually write imperative Python (eager mode), and optionally decorate functions with tf.function to trace them into graphs for speed.
Think: you sketch a blueprint (graph). The TensorFlow runtime is a construction crew that reads the blueprint and builds results quickly, using all the hardware lanes.
Autodiff: Why Gradients Matter
Autodiff: Why Gradients Matter
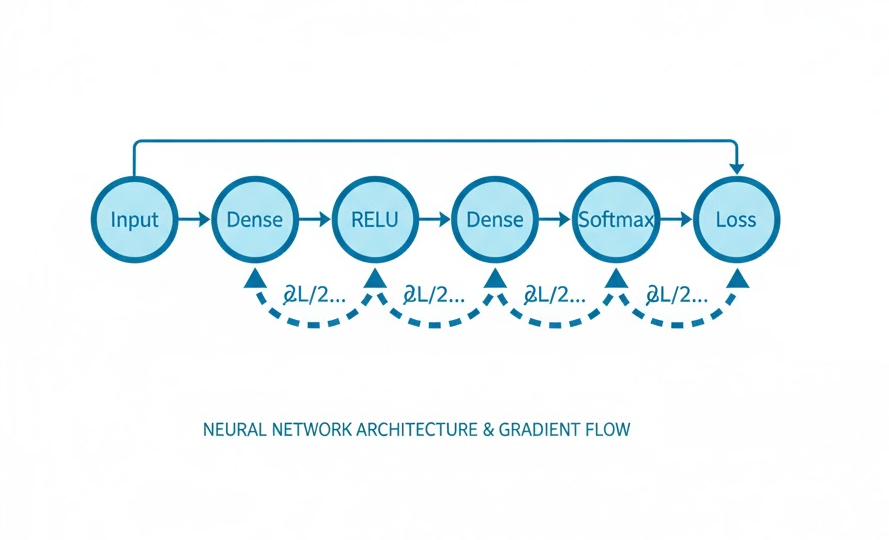
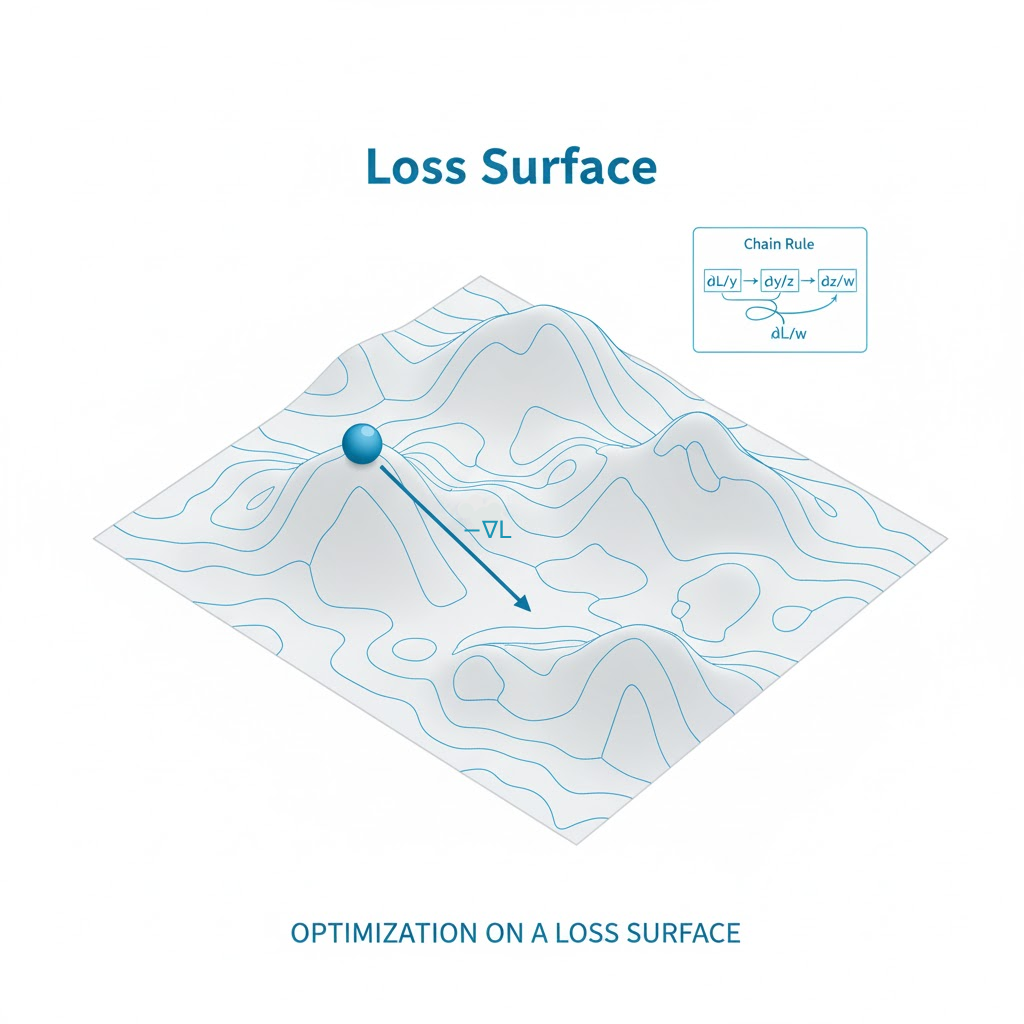
Automatic differentiation (autodiff) uses the chain rule to compute how changing each weight will change the loss. Forward: compute predictions. Backward: propagate ∂loss/∂node from outputs to inputs, accumulating gradients.
Without gradients, your model can’t learn. With them, an optimizer updates variables:
w ← w − η * ∂L/∂w where η is the learning rate.
Hands-On Analogy: Build a Mini Autodiff Engine
Hands-On Analogy: Build a Mini Autodiff Engine
Using raw Python (no libraries), we’ll mirror TensorFlow’s core idea: a Tensor that remembers how it was made, so we can backprop. For illustration, here is a minimal scalar/vector autodiff to mirror TensorFlow's gradient tapes.
This is not TensorFlow, but it rhymes with its GradientTape: track ops → compute loss → call backward() → update weights.
```python
class Tensor:
    def __init__(self, data, parents=(), op="leaf"):
        self.data = data            # number or list[float]
        self.grad = 0.0             # dL/dThis (scalar engine for clarity)
        self.parents = parents      # upstream nodes
        self.op = op                # for debug

    def __add__(self, other):
        other = other if isinstance(other, Tensor) else Tensor(other)
        out = Tensor(self.data + other.data, (self, other), "add")
        def _backward():
            self.grad += out.grad
            other.grad += out.grad
        out._backward = _backward
        return out

    def __mul__(self, other):
        other = other if isinstance(other, Tensor) else Tensor(other)
        out = Tensor(self.data * other.data, (self, other), "mul")
        def _backward():
            self.grad += other.data * out.grad
            other.grad += self.data * out.grad
        out._backward = _backward
        return out

    def relu(self):
        out = Tensor(self.data if self.data > 0 else 0.0, (self,), "relu")
        def _backward():
            self.grad += (1.0 if self.data > 0 else 0.0) * out.grad
        out._backward = _backward
        return out

    def backward(self):
        # topological order (simple since our examples are small chains)
        topo = []
        visited = set()
        def build(v):
            if v not in visited:
                visited.add(v)
                for p in v.parents:
                    build(p)
                topo.append(v)
        build(self)
        self.grad = 1.0
        for v in reversed(topo):
            if hasattr(v, "_backward"):
                v._backward()

# Demo: Fit y = 2x + 1 using tiny gradient descent
if __name__ == "__main__":
    x = Tensor(3.0)
    w = Tensor(0.5)
    b = Tensor(0.0)
    y_true = Tensor(7.0)  # 2*3 + 1 = 7

    for step in range(100):
        # forward
        y_pred = (w * x + b).relu()  # just to use a nonlinearity
        loss = (y_pred + (Tensor(-1.0) * y_true)) * (y_pred + (Tensor(-1.0) * y_true))  # (y_pred - y_true)^2

        # backward
        for t in [w, b, x, y_pred, loss]:
            t.grad = 0.0
        loss.backward()

        # update
        lr = 0.01
        w.data -= lr * w.grad
        b.data -= lr * b.grad

        if step % 20 == 0:
            print(f"step={step} loss={loss.data:.4f} w={w.data:.3f} b={b.data:.3f}")
```
GradientTape in TensorFlow
GradientTape in TensorFlow
The mini autodiff engine showed the idea: remember operations, compute a loss, then walk backward. In real TensorFlow, tf.GradientTape() records tensor operations during the forward pass.
A typical training step is:
- Create or read
Variablevalues. - Compute predictions.
- Compute a
loss. - Ask the tape for
gradients. - Let an
optimizerupdate the variables.
Here is the same pattern in actual TensorFlow:
```python
import tensorflow as tf

# A tiny model: y = w*x + b
w = tf.Variable(0.5, dtype=tf.float32)
b = tf.Variable(0.0, dtype=tf.float32)

x = tf.constant([1.0, 2.0, 3.0])
y_true = tf.constant([2.0, 4.0, 6.0])

optimizer = tf.keras.optimizers.SGD(learning_rate=0.1)

with tf.GradientTape() as tape:
    y_pred = w * x + b
    loss = tf.reduce_mean((y_true - y_pred) ** 2)

gradients = tape.gradient(loss, [w, b])
optimizer.apply_gradients(zip(gradients, [w, b]))

print("loss:", loss.numpy())
print("updated w:", w.numpy())
print("updated b:", b.numpy())
```
Multiple Choice
Which ingredient is essential for automatic differentiation to work?
Tracing Check
When you wrap a Python function with tf.function, what is TensorFlow mainly trying to create?
Eager vs Graph: Two Modes, One Goal
Eager vs Graph: Two Modes, One Goal
-
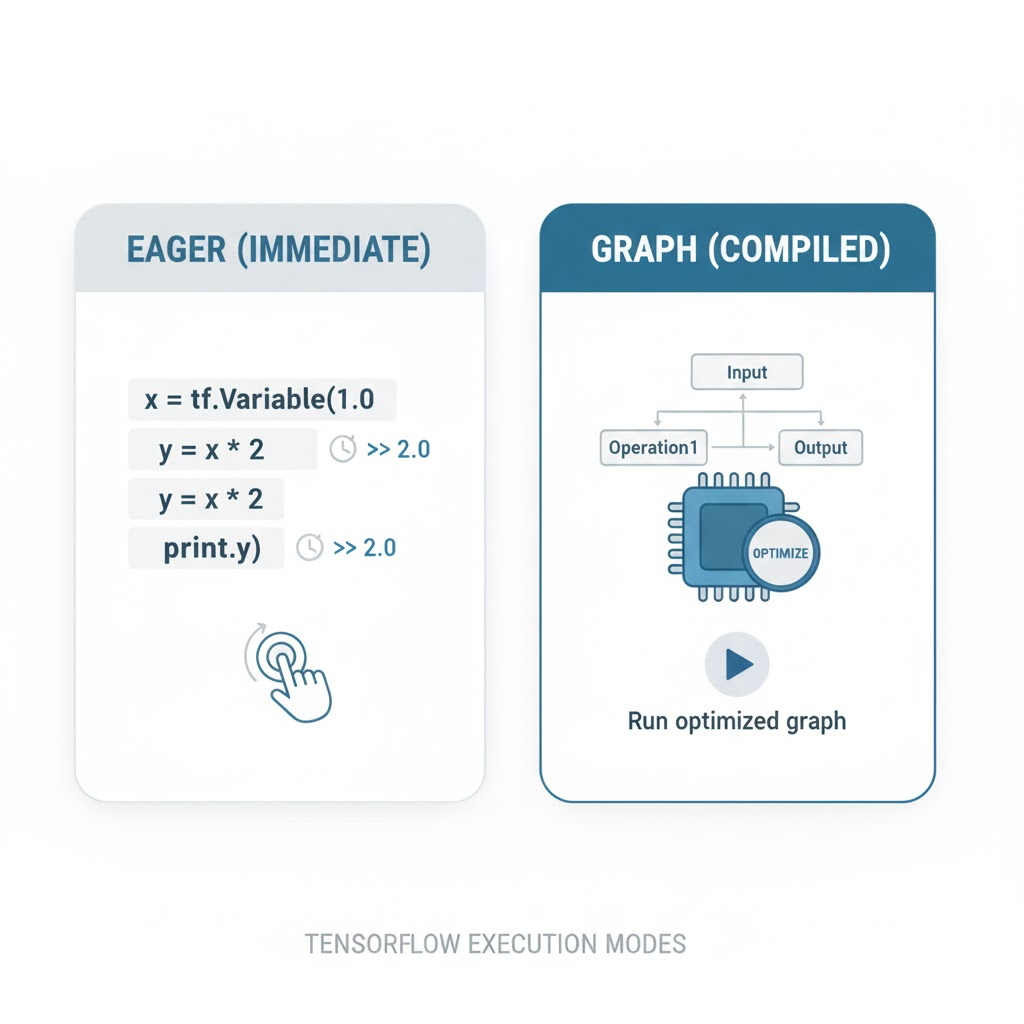
Eager execution: ops run immediately (great for debugging). -
Graph mode: trace Python functions into a static graph for optimizations like kernel fusion, device placement, and parallelism.
Think: sketch first (eager), then commit blueprints for speed (graph). TF 2 encourages eager by default, with optional graph compilation for production.
Shape Debug Habit
When a TensorFlow model fails during MatMul, Conv2D, or layer connection, checking tensor shape and dtype is usually one of the first debugging steps.
Devices & Kernels: How It Gets Fast
Devices & Kernels: How It Gets Fast
A kernel is the device-specific implementation of an op. TensorFlow schedules ops on devices:
- CPU: general-purpose; great for control-heavy tasks.
- GPU: massive parallel math (matmuls, convs).
- TPU: matrix math ASIC for large-scale training.
TensorFlow picks placements, manages memory copies, and runs kernels in parallel streams when possible.
Shape & Dtype: Contracts Between Ops
Shape & Dtype: Contracts Between Ops
Every tensor has a shape and dtype. Mismatches cause errors or implicit broadcasting. TensorFlow validates compatibility so MatMul doesn’t try to multiply [3,4] by [5,6].
Rule of thumb: when something breaks, check shapes first, then types.
Optimizers: How Variables Learn
Optimizers: How Variables Learn
Variables are tensors you can update. Optimizers compute updates from gradients:
-
SGD:w ← w − η g -
Momentum: adds velocity to smooth updates -
Adam: adaptive learning rates per parameter (mean + variance estimates)
Under the hood, these are additional ops in the graph that read gradients and write new values.
True or False?
In TensorFlow, variables are the trainable parameters whose values persist across steps.
Mini-Model From Scratch: Two-Layer MLP
Mini-Model From Scratch: Two-Layer MLP
Here is a two-layer MLP for binary classification implementation on toy data, using no external libs. We’ll mimic TensorFlow logic: forward pass + backward gradients + updates. (This helps you understand what TF automates.)
TensorFlow would: (1) define layers, (2) run forward, (3) use a GradientTape to get grads, (4) call optimizer.apply_gradients. Everything else (placement, kernels, shapes) comes “for free.”
```python
import random, math

def sigmoid(x): return 1/(1+math.exp(-x))
def dsigmoid(y): return y*(1-y)
def relu(x): return x if x>0 else 0.0
def drelu(x): return 1.0 if x>0 else 0.0

def dot(w, x): return sum(wi*xi for wi,xi in zip(w,x))

def make_blobs(n=200, seed=0):
    random.seed(seed)
    X, Y = [], []
    for _ in range(n//2):
        X.append([random.gauss(-1,0.5), random.gauss(0,0.5)]); Y.append(0.0)
    for _ in range(n//2):
        X.append([random.gauss( 1,0.5), random.gauss(0,0.5)]); Y.append(1.0)
    return X, Y

def train(hidden=8, epochs=800, lr=0.05):
    X, Y = make_blobs()
    in_dim = 2
    W1 = [[random.uniform(-0.5,0.5) for _ in range(in_dim)] for _ in range(hidden)]
    b1 = [0.0]*hidden
    W2 = [random.uniform(-0.5,0.5) for _ in range(hidden)]
    b2 = 0.0

    for ep in range(epochs):
        dW1 = [[0.0]*in_dim for _ in range(hidden)]
        db1 = [0.0]*hidden
        dW2 = [0.0]*hidden
        db2 = 0.0
        loss = 0.0
        for x,y in zip(X,Y):
            # forward
            z1 = [dot(W1[j], x) + b1[j] for j in range(hidden)]
            a1 = [relu(z) for z in z1]
            z2 = dot(W2, a1) + b2
            a2 = sigmoid(z2)
            eps = 1e-8
            loss += -(y*math.log(a2+eps) + (1-y)*math.log(1-a2+eps))

            # backward
            dL_dz2 = (a2 - y)  # derivative of BCE wrt z2 using y∈{0,1}
            for j in range(hidden):
                dW2[j] += dL_dz2 * a1[j]
            db2 += dL_dz2

            da1 = [dL_dz2 * W2[j] for j in range(hidden)]
            dz1 = [da1[j]*drelu(z1[j]) for j in range(hidden)]
            for j in range(hidden):
                for i in range(in_dim):
                    dW1[j][i] += dz1[j]*x[i]
                db1[j] += dz1[j]

        n = len(X)
        for j in range(hidden):
            for i in range(in_dim): W1[j][i] -= lr*(dW1[j][i]/n)
            b1[j] -= lr*(db1[j]/n)
            W2[j] -= lr*(dW2[j]/n)
        b2 -= lr*(db2/n)

        if (ep+1)%100==0:
            print(f"epoch={ep+1} loss={loss/n:.4f}")
    return (W1,b1,W2,b2)

if __name__=="__main__":
    train()
```
Multiple Choice
Why is eager mode helpful during model development?
Input Pipelines: Feeding the Beast
Input Pipelines: Feeding the Beast
Large models are hungry. tf.data pipelines let you read, shuffle, batch, prefetch, and parallelize input work so your accelerators never starve. Conceptually: a conveyor belt that keeps the GPU fed while the CPU prepares the next batch.
Distribution Strategies: Use All the Compute
Distribution Strategies: Use All the Compute
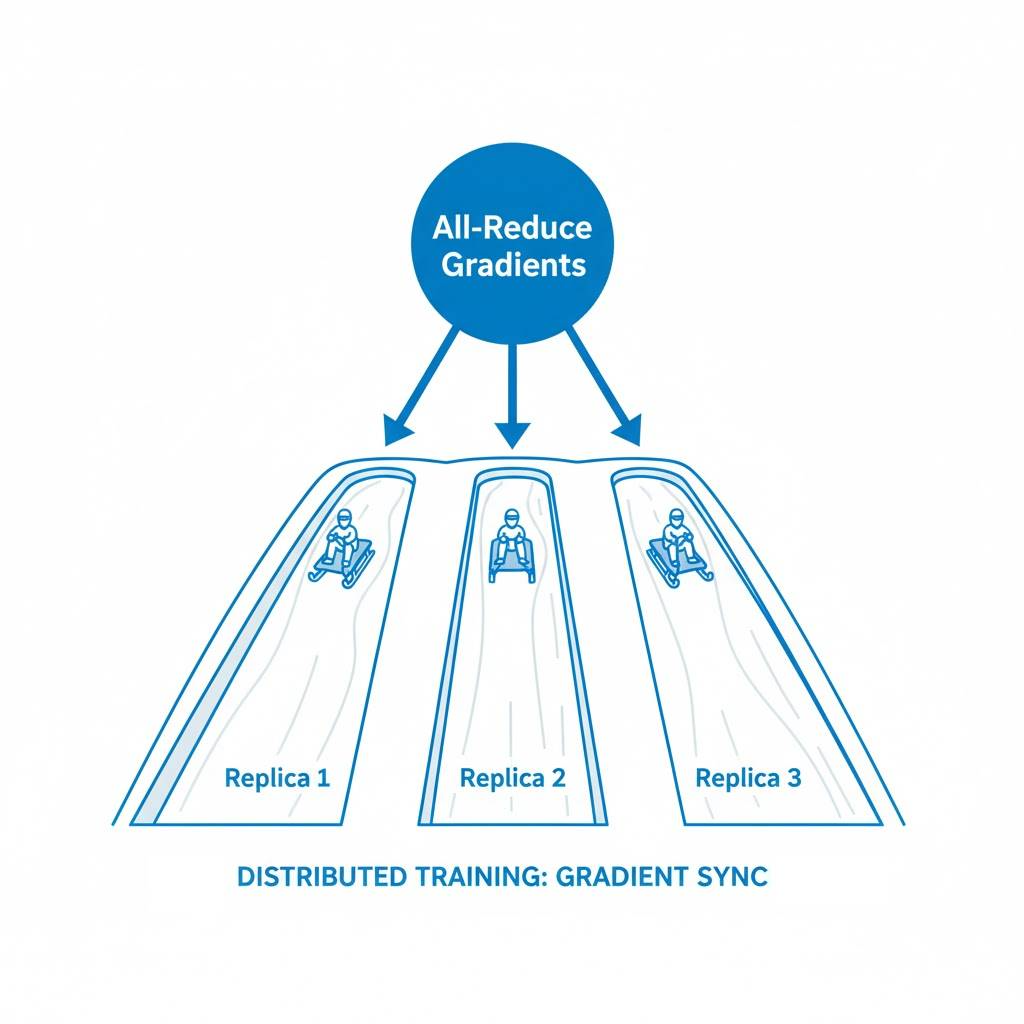
tf.distribute.Strategy scales training across multiple GPUs/TPUs or machines. It shards your batches, runs replicas in parallel, and reduces gradients correctly (e.g., all-reduce).
Mental model: many workers push identical sleds uphill (same model) on different snow lanes (data shards), then share what they learned at checkpoints.
Wrap-Up
Wrap-Up
TensorFlow’s secret sauce is representing math as graphs of tensor ops, then using autodiff and device kernels to train models at scale. You write the math; TensorFlow handles the gradients, speed, and hardware. Once this mental model clicks, using high-level APIs (Keras) feels like calling a well-tuned orchestra: you conduct, it performs.
One Pager Cheat Sheet
One Pager Cheat Sheet
- Instead of hand-coding rules, you build a machine that learns rules—a stack of
layersorganized as acomputational graph—andTensorFlowbuilds the graph, runs it efficiently on CPUs/GPUs/TPUs, and optimizes the machine using gradients, combiningTensors,Flow,Autodiff, and execution engines. - TensorFlow represents computations as a
graphofopsconnected bytensors, usesautomatic differentiationto computegradientsof alosswith respect tovariables(automating the backward pass from your forward pass), executes efficiently acrossdevices(CPU/GPU/TPU) with scheduling and batching, and provides optimizers likeSGDandAdamto update model parameters. -
tensoris a container for numbers with ashape(e.g.,[batch, height, width, channels]), described byrank(number of dimensions) anddtype(numeric type likefloat32), and can be thought of as a spreadsheet with many tabs that operations broadcast and combine. - TensorFlow lets you write imperative Python (eager mode) that you can
tf.function-trace into acomputational graph—a DAG ofops(e.g.,MatMul,Add,Conv2D) withtensorson the edges—so the TensorFlow runtime acts like a construction crew that reads the blueprint and executes it efficiently across hardware. -
autodiffuses thechain ruleto compute how changing each weight affects theloss, performing a forward pass to get predictions and a backward pass propagating∂loss/∂nodeso the resulting gradients let an optimizer update variables viaw ← w − η * ∂L/∂wwithηthelearning rate, without which the model can’t learn. - Using raw Python (no libraries), we build a mini autodiff engine whose
Tensorremembers how it was made so we canbackproplike TensorFlow'sGradientTape—track ops → compute loss → callbackward()→ update weights. - Automatic differentiation must record the computational graph — i.e. the recorded history of how each tensor was computed (the
op, itsinputsandoutput, and the node’sgrad_fn) — because it applies the chain rule to composed operations and needs that structure to perform backpropagation and compute/accumulate the local derivatives. - TensorFlow offers Eager execution (where
opsrun immediately for easy debugging) and Graph mode (which traces Python into a staticgraphto enable optimizations like kernel fusion, device placement, and parallelism), and TF 2 defaults to eager with optional graph compilation for production. -
TensorFlowtreats akernelas the device-specific implementation of anop, assigns work to CPU (control-heavy), GPU (massive parallel math), or TPU (matrix-math ASIC), and picks placements, manages memory copies, and runs kernels in parallel streams to maximize speed. - Tensors have
shapeanddtypeas contracts—mismatches lead to errors or implicitbroadcasting, and frameworks like TensorFlow validates compatibility (soMatMulwon’t try to multiply[3,4]by[5,6]); rule of thumb: check shapes first, then types when something breaks. -
Variablesare updatabletensorsandoptimizerscompute updates from gradients—e.g.SGD(w ← w − η g),Momentum(adds velocity), andAdam(adaptive per-parameter rates using mean and variance estimates)—and are implemented as additional ops in the graph that read gradients and write new values. - A
tf.Variableis the mutable, persisted storage for model parameters—unlike atf.Tensorwhich is immutable—so it persists across training steps, can be marked as trainable parameters (e.g.tf.Variable(..., trainable=True)) whose gradients (collected viatf.trainable_variables()ormodel.trainable_weights) are used by optimizers that read gradients and write new variable values via assignment ops (e.g.v.assign_sub(...)) and may create slottf.Variables for optimizer state, while all variables (including non-trainable ones like batch-norm moving averages) are saved and restored with checkpoints (e.g.tf.train.Checkpoint/tf.train.Saver). - A two-layer MLP for binary classification, implemented from scratch with no external libs, explicitly performs the
forward pass, computesbackward gradients, and makes parameterupdatesto mimic TensorFlow logic—the same steps TensorFlow automates usingGradientTapeandoptimizer.apply_gradients. - Because
eager executionruns operations immediately, it provides immediate, inspectable values and natural Python control flow, which makes debugging, shape/gradient verification, and rapid iteration much easier (e.g., withGradientTape,tensor.numpy(),print) and supports a smooth transition to production via@tf.function, though it's slower than graph mode and still requires final testing under tracing. - Because large models are hungry,
tf.datapipelines—by reading, shuffling, batching, prefetching, and parallelizing—act as a conveyor belt that keeps theGPUfed so your accelerators never starve. -
tf.distribute.Strategyscales training across multiple GPUs/TPUs or machines by sharding batches, running replicas in parallel, and reducing gradients correctly (e.g.,all-reduce), so workers train identical models on different data shards and share updates at checkpoints. -
TensorFlowrepresents math as graphs of tensor ops, usesautodiffanddevice kernelsto handle gradients, performance, and hardware, and so once this model clicks, usingKerasfeels like conducting a well-tuned orchestra.